Global-batch load balance almost free lunch to improve your MoE LLM training
- Source
- qwenlm.github.io
- Author
- Qwen Team
- Date
Context
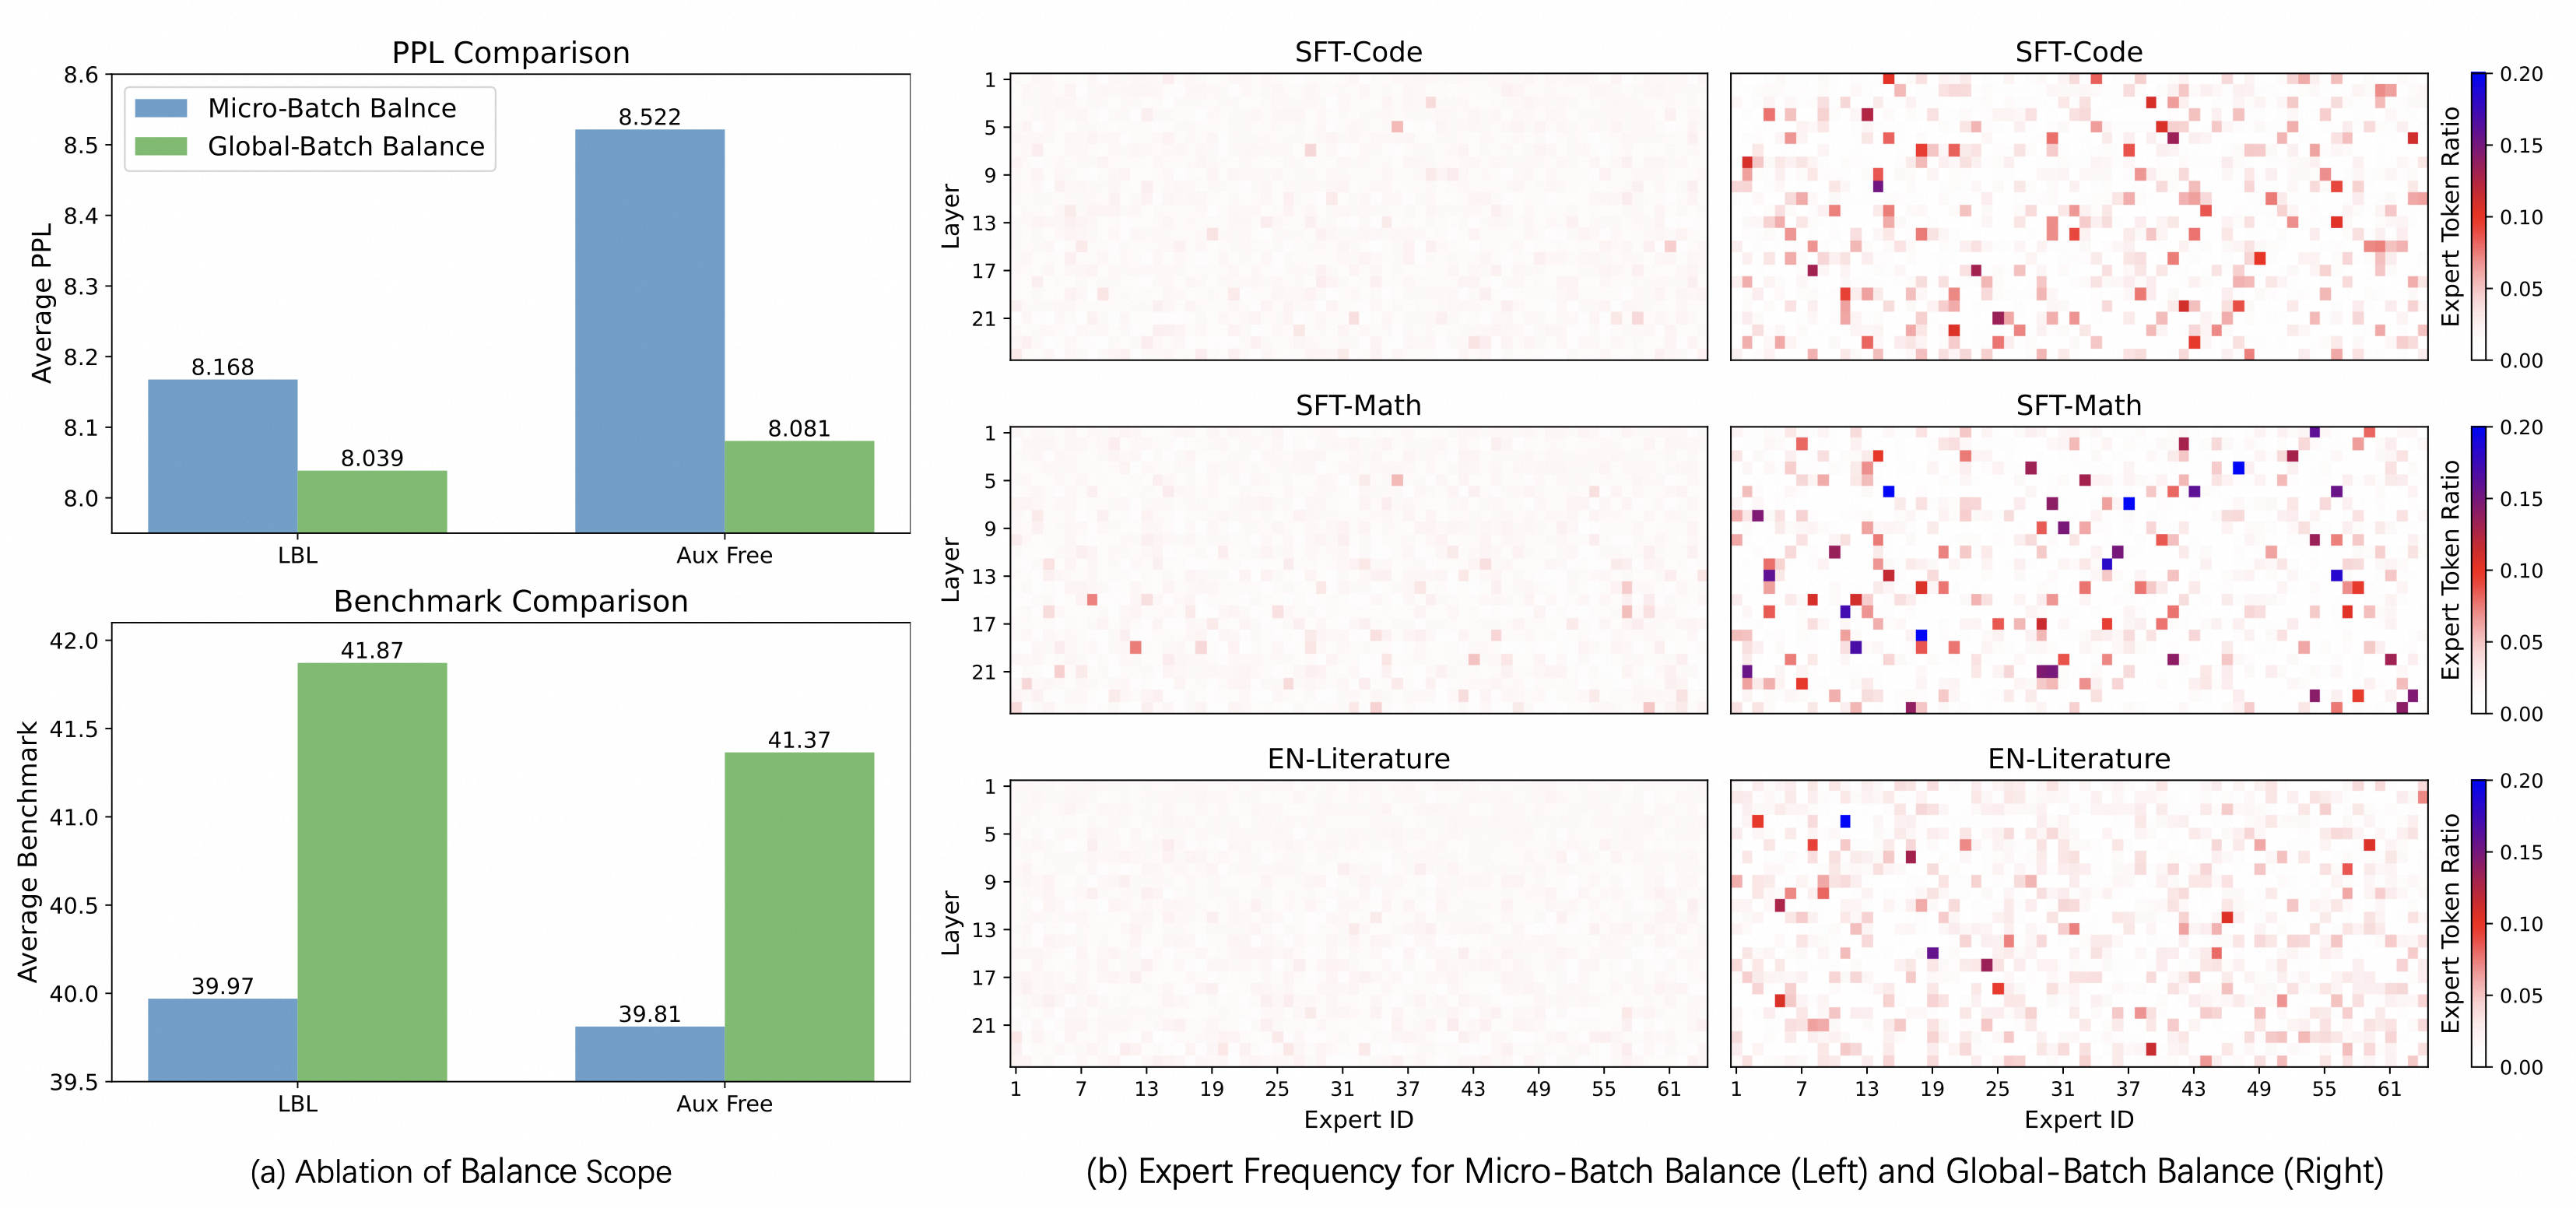
An AI model's specialist components can struggle to specialize if training forces every small batch of data through them equally. Qwen describes this problem in models, which route each input through selected parts of the network. A batch containing only code still faces pressure to spread work uniformly. Its proposed fix balances expert usage across the larger combined training batch, allowing individual batches to favor particular experts. The research account reports better performance and clearer specialization in the tested configurations.
Balancing the whole batch can leave individual devices with uneven workloads. The researchers therefore also tested a smaller local balancing adjustment, recovering some processing speed while largely preserving the gains. This makes the proposal a way to reconcile specialization with efficient training.
- mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
Checking sign-in…
Loading comments…