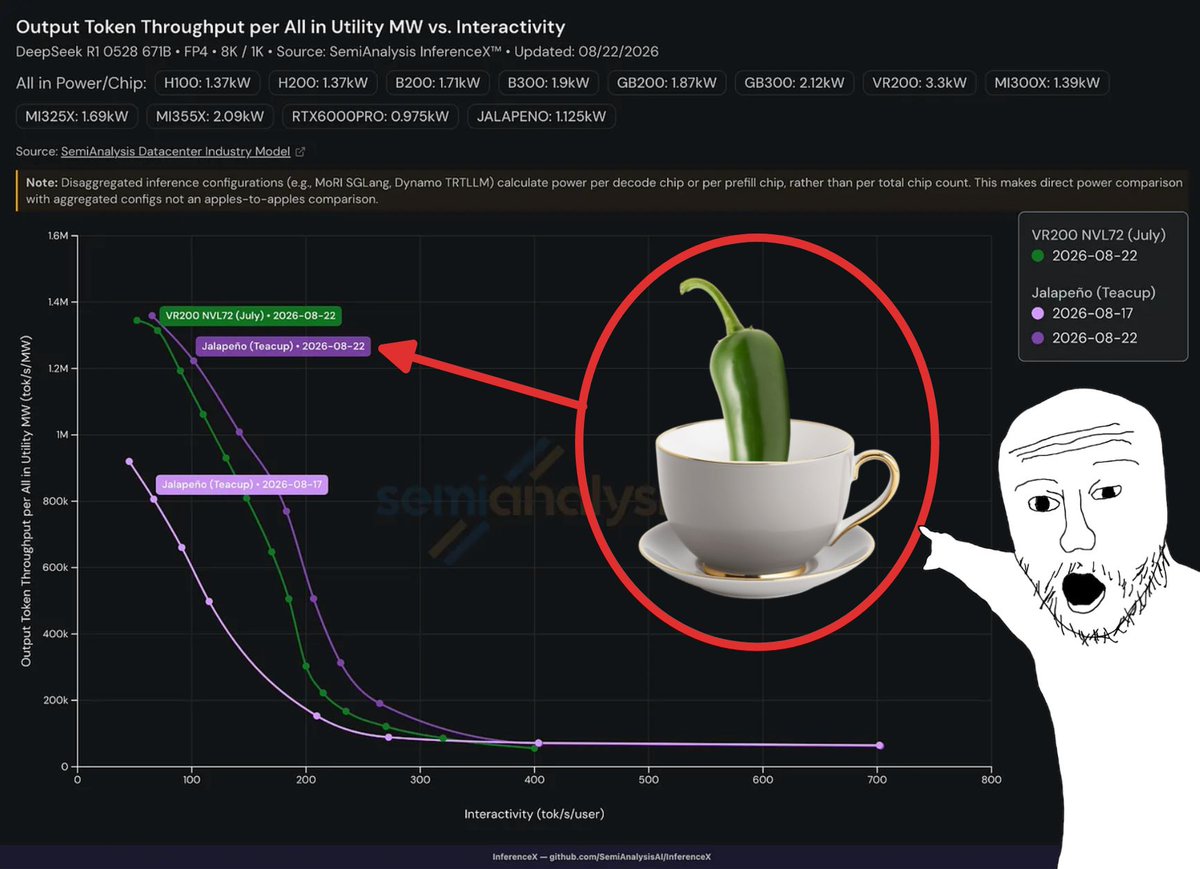
BREAKING NEWS🚨🚨 OPENAI'S NEWEST CHIP IS UP TO 2x BETTER PERF PER WATT THAN NVIDIA'S JULY RUBIN PERFORMANCE. OPENAI'S CHIP DIDN'T EVEN ENABLE SPEC DECODING, YET BEATS RUBIN NVL72 WITH SPEC DECODING. (1/2)🧵
OPENAI JALAPENO CHIP IS MEASURED TO HAVE BETTER PERFORMANCE ACROSS THE ENTIRE PARETO VERSUS JULY RUBIN. (2/2)
If a lab's in-house accelerator genuinely beats Nvidia's current part on performance per watt, the cost floor for inferenceRunning a trained model to get answers — the phase where AI is actually used, as opposed to trained.Full definition → — and who controls it — starts moving.
Terms in this piece · Glossary
speculative decoding — A speed trick where a small model drafts several tokens ahead and the big model verifies them in one pass, often doubling generation speed.
inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.