API pricing update 💰 With the V4 lineup release, we’re updating our API pricing
- Source
- x.com
- Date

We’re launching DeepSeek-V4-Pro today! 🚀 🔷 Major Agent upgrades with strong production gains! 🔷 Flexible reasoning effort for V4-Pro & V4-Flash: low for simple tasks, high for daily Agent workflows, max for complex tasks. 🔷 Native OpenAI Responses API support, optimized for Codex with one-click setup. V4 Pro is now available on app/web. Try it via “Expert Mode”. V4 Pro is also available via API. Model names remain unchanged—please refer to the API docs for setup details.

API pricing update 💰 With the V4 lineup release, we’re updating our API pricing and introducing peak and off-peak rates. Off-peak rates are 50% lower than peak, enabling more flexible workload scheduling. 📉 New pricing takes effect at 16:00 UTC, Aug 16, 2026 🕒

Context
DeepSeek's pricing change makes the time of day part of what an API request costs. In the second post of its V4-Pro launch thread, the company says that with the V4 lineup it is introducing peak and off-peak rates, with off-peak rates 50% lower than peak, and that the new prices take effect at 16:00 UTC on August 16, 2026, three days after the announcement. DeepSeek presents the split as a way to schedule workloads more flexibly: the same model costs half as much when the work can be sent outside peak hours.
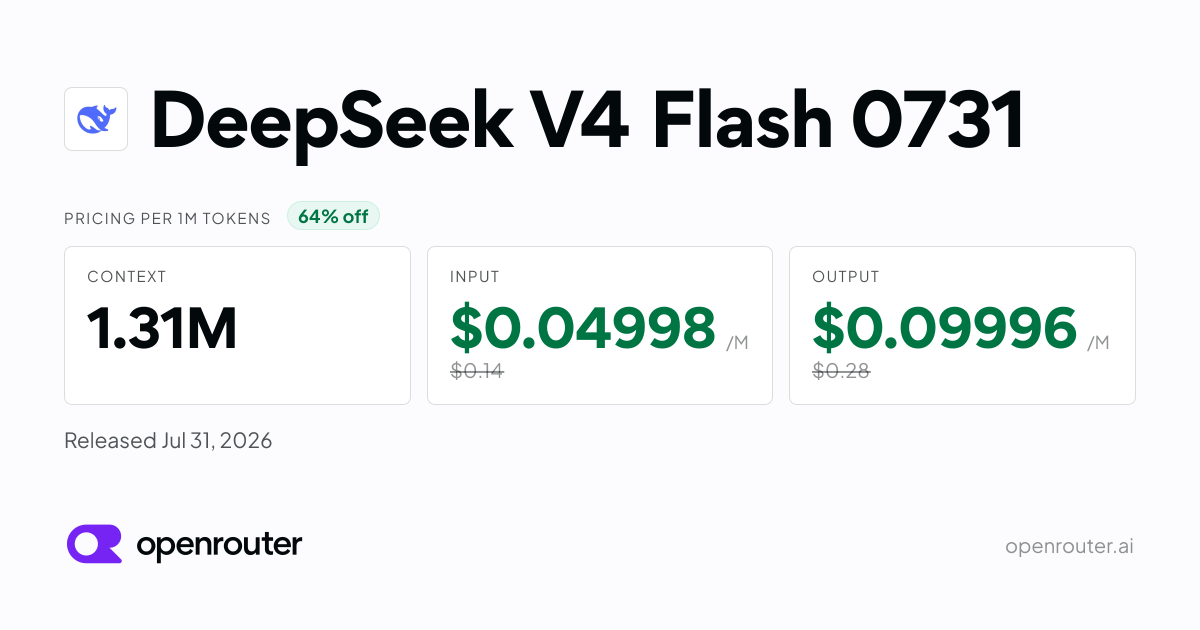
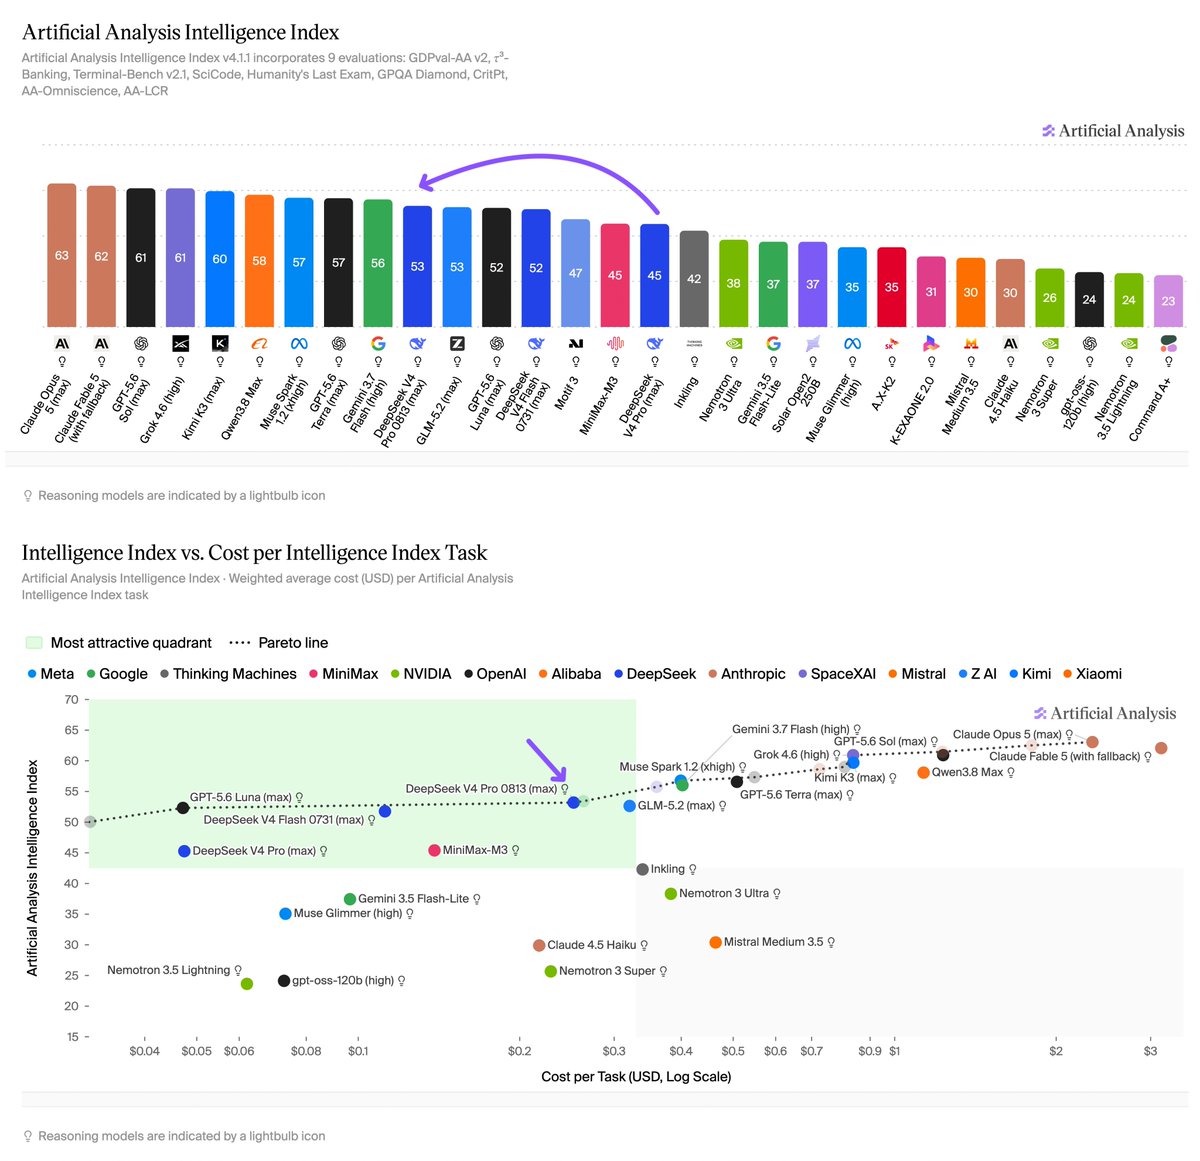
The thread's text does not say which hours count as peak or what the new per- rates are, so it establishes how the discount works but not how much a given workload will pay. Artificial Analysis's evaluation of the new model, published two days later, lists the new per-token prices alongside its results. The first post in the same thread, which announces V4-Pro itself, is covered separately.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
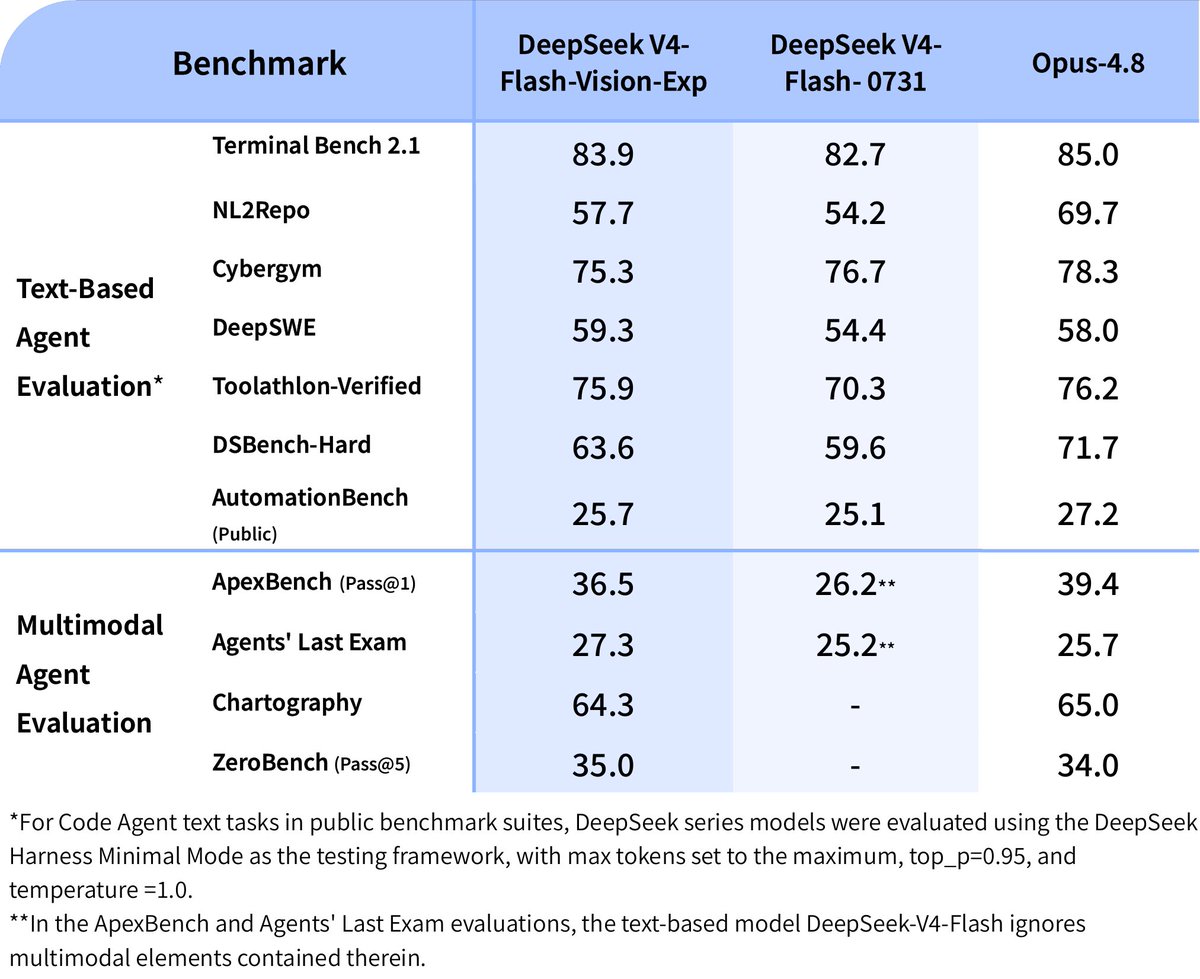
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.


Checking sign-in…
Loading comments…