Developing Nemotron 3.5 Lightning NVFP4 with QAD Using NVIDIA Model Optimizer
- Source
- developer.nvidia.com
- Author
- Tanya Lenz
- Date
Context
Compressing a model can reduce accuracy because its learned numerical values must fit a coarser representation. NVIDIA's Nemotron 3.5 Lightning work adds training after that compression: the compressed model experiences simulated while learning to match the original model's outputs. This gives it a way to adapt to compression errors. The technical article describes the two-stage process.
For one aggressively compressed intermediate checkpoint in the evaluation tables, median -score recovery rose from 96.33% to 99.72% of the original model's scores, with the same 21.19 GB checkpoint size. The final, more conservative recipe had mixed results and a slightly lower median after the added training. The strongest evidence is that this training can recover losses from aggressive compression; the benefit depends on the recipe and workload.
- quantization — Shrinking a model by storing its numbers less precisely — like rounding — so it runs faster and fits on smaller hardware, at a small quality cost.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- distillation — Training a small, cheap model to imitate a big one's outputs, keeping much of the capability at a fraction of the cost.
 articleAccelerating Reinforcement Learning Weight Refit with the Reshard Collective
 articleScaling NVIDIA TensorRT Performance Optimization Beyond a Single Build Route with the Global Performance Tuner, Part 2
 articleAccelerating Mamba-2 with High-Performance Forward Pass Kernels in NVIDIA CUDA Tile
 articleScale Agentic Coding Workflows with Meta’s Muse Spark Open on NVIDIA GB300 NVL72
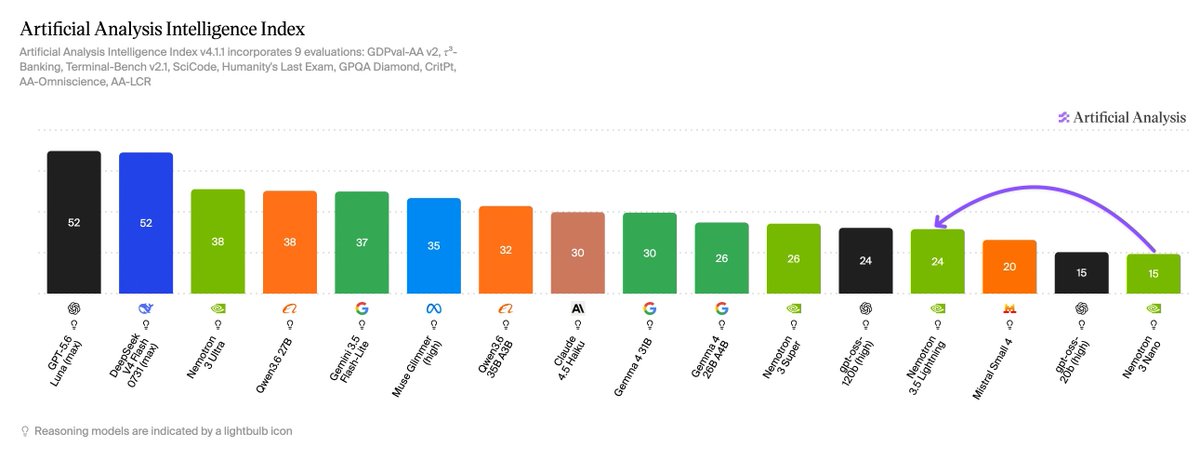 postNVIDIA has just released the first Nemotron 3.5 model: Nemotron 3.5 Lightning, aArtificial Analysis
 articleFrontier Reasoning Reaches the Edge: How to Deploy and Optimize Models on NVIDIA JetsonElizabeth Goodman
 articleHow Full-Stack NIM Optimizations Deliver 2.5x More Users on Nemotron 3 UltraElizabeth Goodman
Checking sign-in…
Loading comments…