Qwen3: Think Deeper, Act Faster
- Source
- qwenlm.github.io
- Author
- Qwen Team
- Date
Context
Qwen's Qwen3 release put extended reasoning and direct answers into the same models. Applications could enable a thinking mode for harder requests or disable it when a quick response mattered more. The April 2025 announcement describes this as a way to control the amount of computation spent answering each task.
The training process deliberately joined those behaviors. After training for extended reasoning, the team combined reasoning examples with ordinary instruction-following examples, then applied further reward-based training across general tasks. That matters for application builders because response style and reasoning effort become configurable within one model, allowing the same assistant to handle both straightforward requests and more demanding problems.
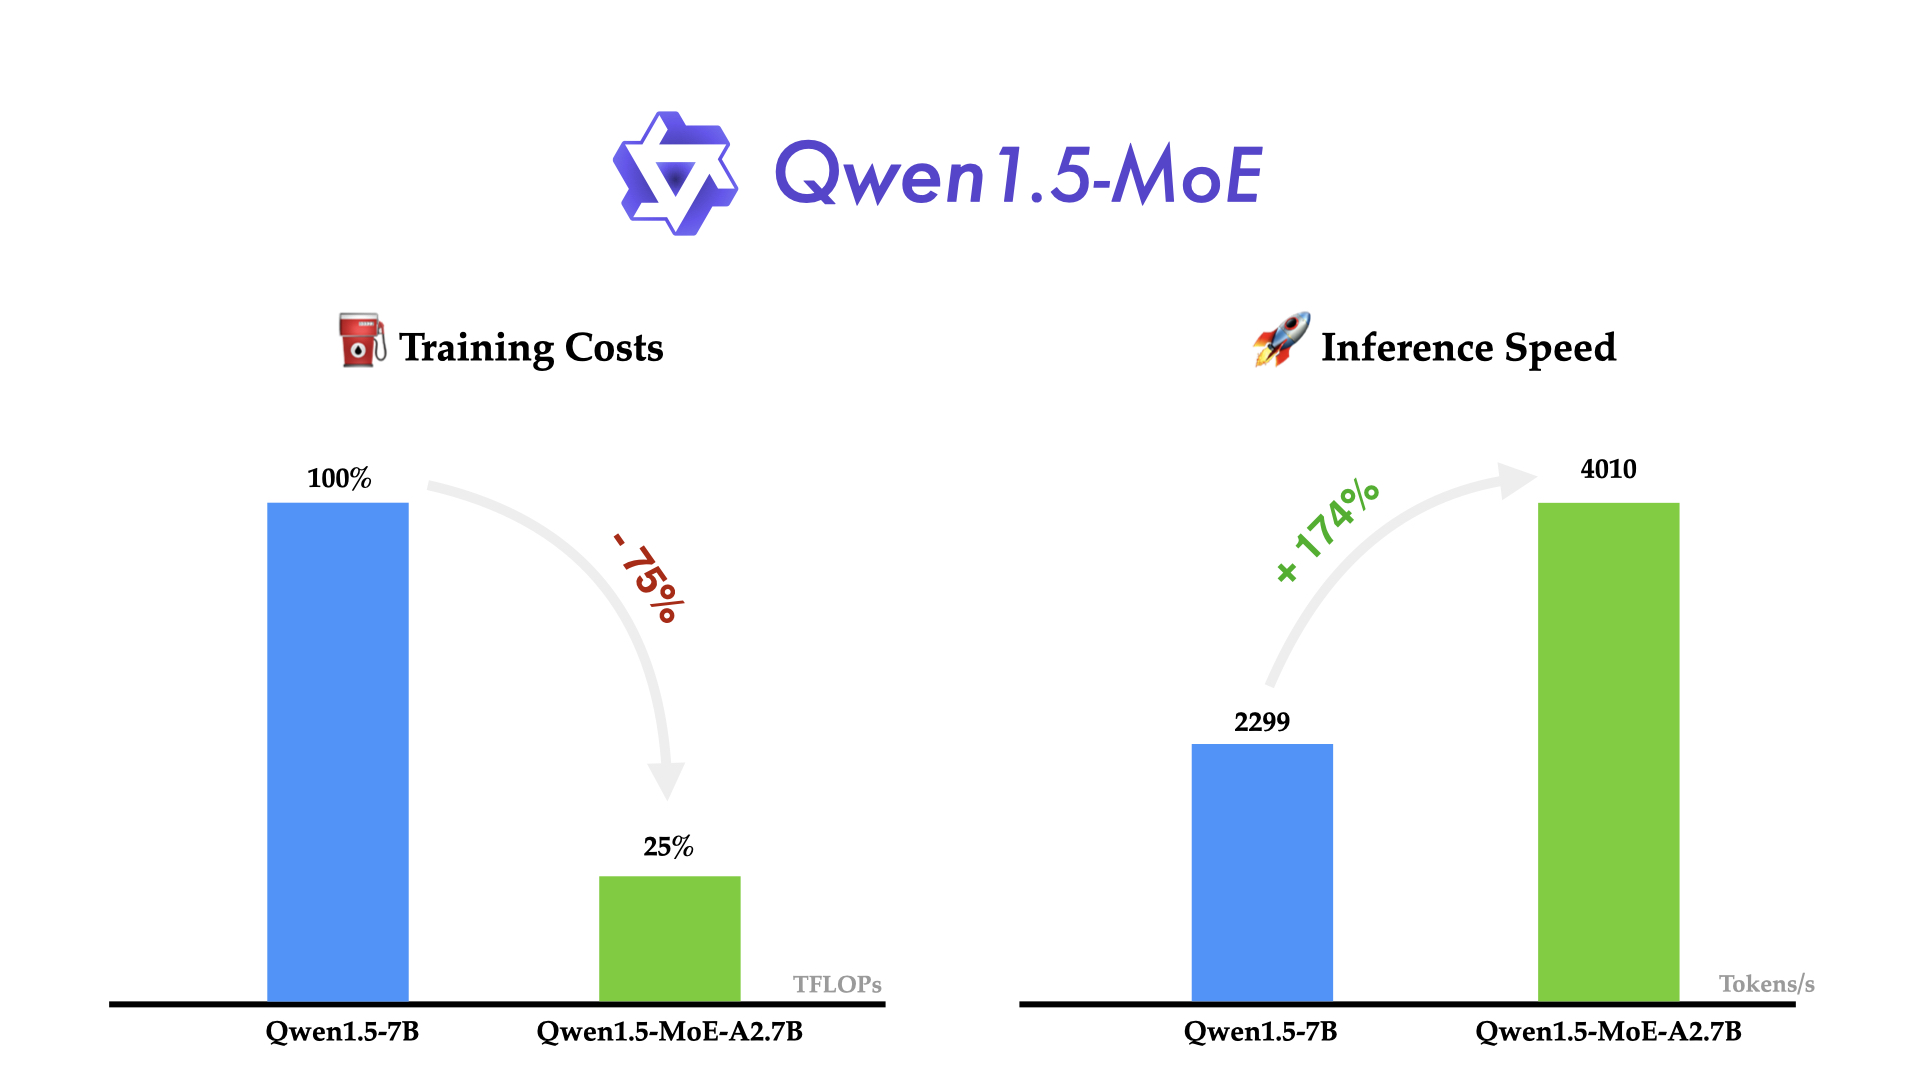
- mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
“Our flagship model, Qwen3-235B-A22B, achieves competitive results in benchmark evaluations of coding, math, general capabilities, etc., when compared to other top-tier models such as DeepSeek-R1, o1, o3-mini, Grok-3, and Gemini-2.5-Pro.”
“Additionally, the small MoE model, Qwen3-30B-A3B, outcompetes QwQ-32B with 10 times of activated parameters, and even a tiny model like Qwen3-4B can rival the performance of Qwen2.”
Checking sign-in…
Loading comments…