Opus 47 Tokenizer Analysis
- Source
- openrouter.ai
- Author
- OpenRouter
- Date
Context
An unchanged price per can still produce a higher bill when a model counts text differently. OpenRouter examined over one million requests from users switching between Anthropic's Opus 4.6 and 4.7. Using its own consistent text-counting method, it found roughly 12–27% higher normalized costs in prompt-size groups above 2,000 units; the shortest group became slightly cheaper. Analysis and methodology.
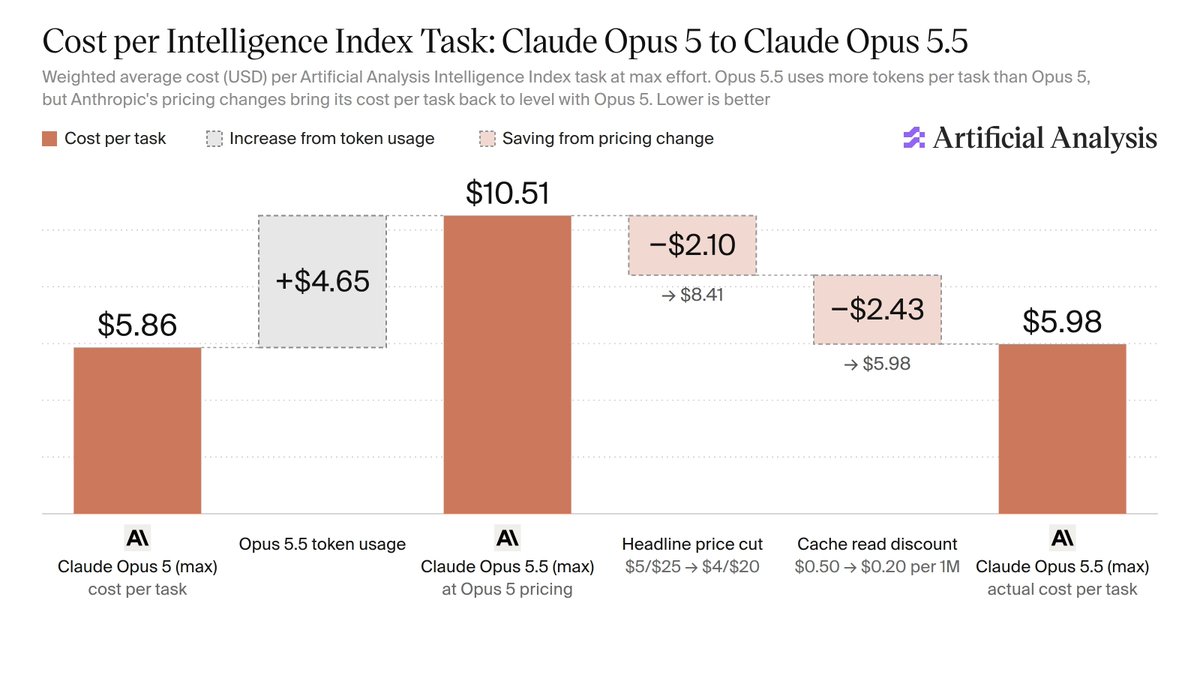
Discounted reuse of cached prompts softened the increase, while changes in answer length also affected bills. These were observations of changing workloads from the same users, not an experiment sending identical text to both models. The findings describe migration costs in that cohort, rather than a universal tokenizer surcharge. Cost breakdown.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.




Checking sign-in…
Loading comments…