Claude Opus 5.5 tops the Coding Agent Index, at higher cost per task
- Source
- x.com
- Date

Claude Opus 5.5 is the new #1 in the Artificial Analysis Coding Agent Index, with gains across all three evaluations, though at a higher Cost per Task At max effort in Claude Code, Opus 5.5 scores 66 on the Coding Agent Index, the highest score we have measured. It is up 6 points against Opus 5 (60) and 4 points against Claude Fable 5.1 (62). Anthropic has cut Opus pricing to $4/$20 per million input/output tokens, from $5/$25 for Opus 5, and cache reads to $0.20 from $0.50. Even with those reductions, Opus 5.5’s Cost per Task is $13.04, above Opus 5’s $10.79, because it uses substantially more tokens. Key takeaways: ➤ Improves across all three Coding Agent Index evaluations: Terminal-Bench 4.0 rises to 63.1% from 54.5% for Opus 5, DeepSWE v1.1 to 68.4% from 62.5%, and SWE-Atlas-QnA to 66.4% from 62.1%. The largest gain is on Terminal-Bench, at +8.6 percentage points. ➤ The top score comes at the highest Cost per Task: Opus 5.5’s Cost per Task is $13.04, up 21% from Opus 5 at $10.79. It uses about 15.6 million tokens per task against 11.4 million for Opus 5, including about 2.4× as many output tokens. ➤ Extends the Coding Agent Index vs Cost per Task Pareto frontier: No…

Context
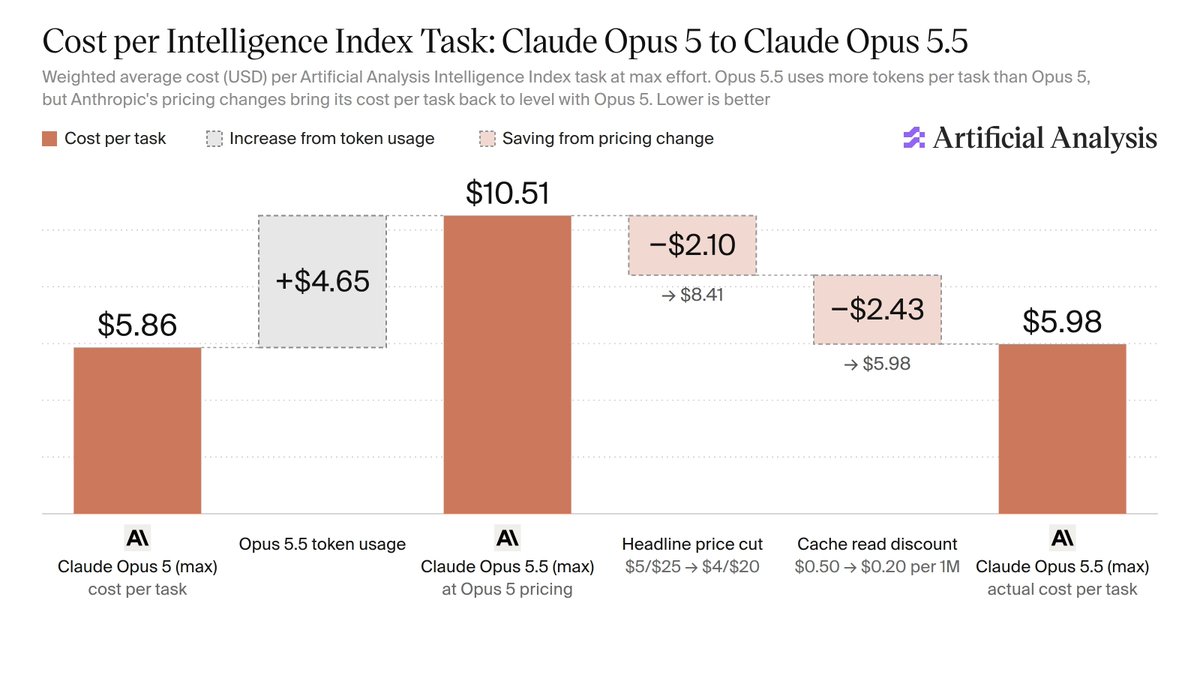
Claude Opus 5.5 costs more per coding task than Opus 5 because it uses far more , and the extra usage outweighs a lower price per token. Anthropic cut Opus pricing to $4 per million input tokens and $20 per million output tokens, down from $5 and $25, and cut cache reads to $0.20 from $0.50. Yet Artificial Analysis measured an average cost of $13.04 per task on its Coding Index, 21% above Opus 5's $10.79. Opus 5.5 used about 15.6 million tokens per task against 11.4 million for Opus 5, including about 2.4 times as many output tokens, which are the most expensive kind.
The extra spending buys the highest score Artificial Analysis has measured on the index. The Coding Agent Index averages three evaluations with equal weight, and here each was run in Claude Code at max effort. Opus 5.5 scores 66, against 60 for Opus 5 and 62 for Claude Fable 5.1. It improved on all three: Terminal-Bench 4.0 rose to 63.1% from 54.5%, the largest gain, DeepSWE v1.1 to 68.4% from 62.5%, and SWE-Atlas-QnA to 66.4% from 62.1%. Artificial Analysis says no lower-cost model in its comparison matches that score, so Opus 5.5 extends the cost-versus-score frontier at its expensive end rather than making top coding performance cheaper.
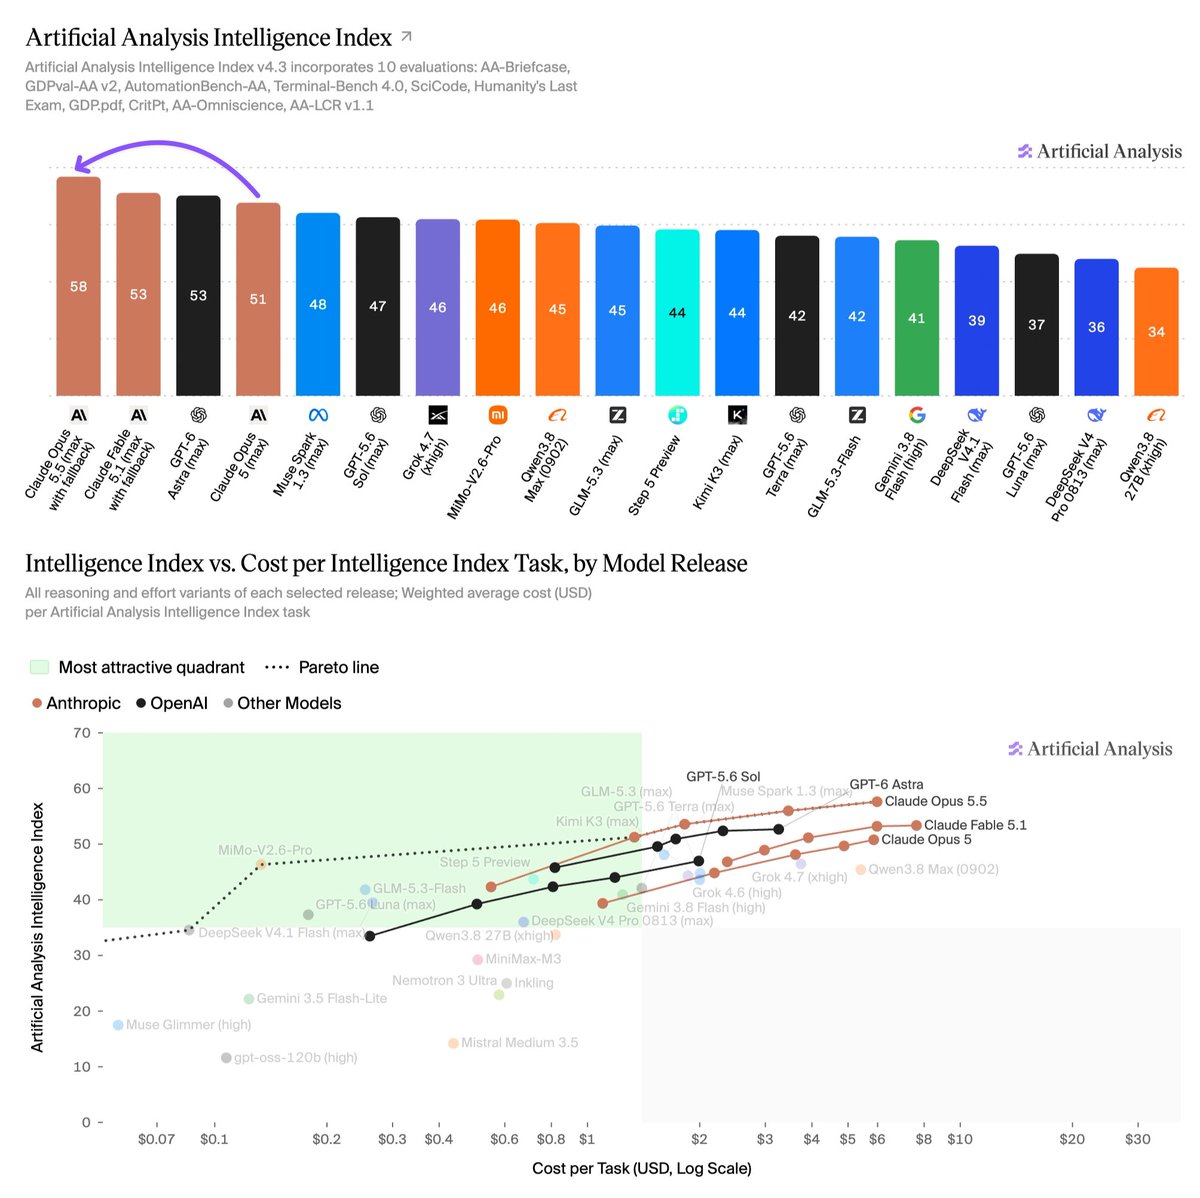
The result shows that a lower per-token price does not guarantee a cheaper task: cost per task also depends on how many tokens the model spends. Artificial Analysis found the same pattern on its broader Intelligence Index, where Opus 5.5's cost per task stayed close to Opus 5's despite the price cut. These figures cover max effort in Claude Code only.
Checking sign-in…
Loading comments…