Grok 4 5 Brings Spacexai To The The Intelligence Frontier
Source
artificialanalysis.ai
Author
Artificial Analysis articles
Date
Why it matters
Grok 4.5 in Grok Build matches GPT-5.5 in Codex on coding-agent evaluations while using about a quarter of the tokens. That makes it a serious low-cost option for agentic coding.
Key takeaways · AI-distilled
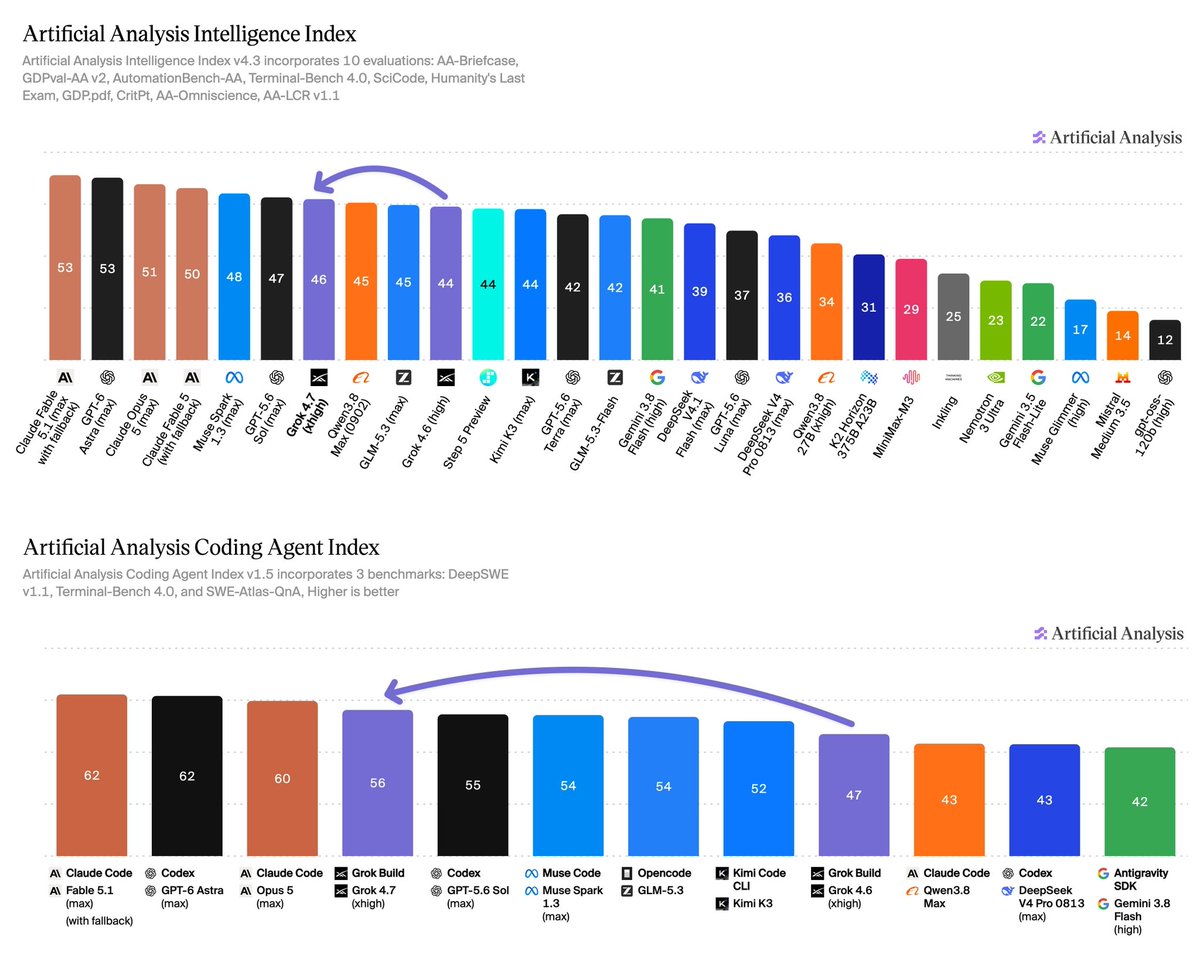
Grok 4.5 scored 54 on the Artificial Analysis Intelligence Index, 16 points over Grok 4.3, placing fourth behind Fable 5, GPT-5.5 and Opus 4.8 and ahead of all open weightsA model whose trained parameters are published for anyone to download and run — unlike API-only models you can access but never possess.Full definition → and Gemini models at the time.
In the Grok Build agent harnessThe scaffolding around a model that turns it into a working agent — the loop, the tools it can call, and the rules for when to stop.Full definition → it scored 76 on AA's Coding Agent Index, on par with GPT-5.5 in Codex, while averaging 1.9M tokens per task versus 7.2M for Fable 5 in Claude Code and 6.2M for GPT-5.5 in Codex.
Pricing is $2/$6 per 1M input/output tokens with 75% cache-hit discounts, but costs double above 200K-token inputs and the context windowThe maximum amount of text a model can consider at once — its working memory for the current conversation or task.Full definition → shrank from Grok 4.3's 1M to 500K tokens.
On AA-Omniscience its accuracy rose from 35% to 52%, but its hallucinationWhen a model states something false with full confidence — inventing facts, citations, or APIs that don't exist.Full definition → rate also climbed from 25% to 54%.
Terms in this piece · Glossary
open weights — A model whose trained parameters are published for anyone to download and run — unlike API-only models you can access but never possess.
agent harness — The scaffolding around a model that turns it into a working agent — the loop, the tools it can call, and the rules for when to stop.
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
hallucination — When a model states something false with full confidence — inventing facts, citations, or APIs that don't exist.