Safety blocks hit defensive cyber work: CyberGym results and costs
- Source
- x.com
- Date
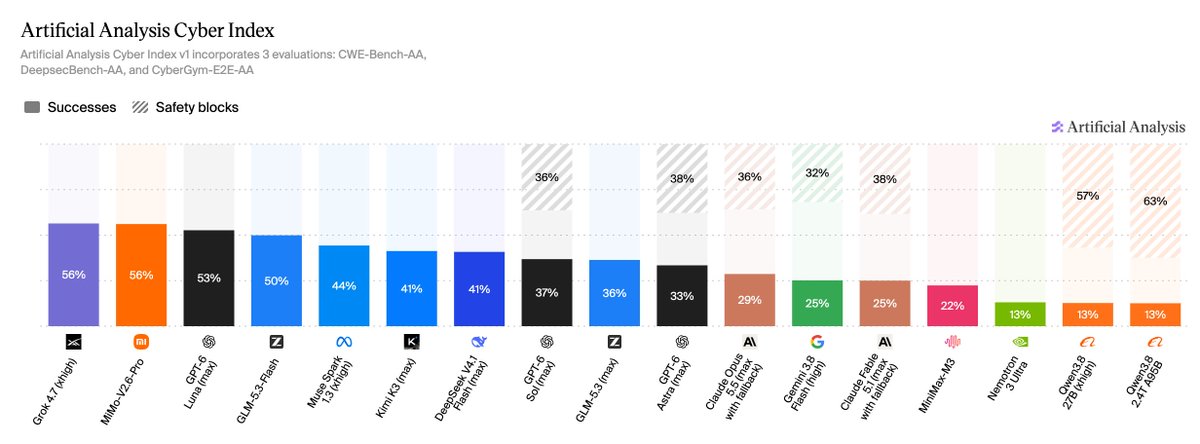
Artificial Analysis ran its CyberGym-E2E-AA evaluation, which asks models to find memory-safety bugs in large codebases, and reported a split result. Several frontier models refused most of the tasks, in some cases more than 85%, because the discovery steps of defensive work look the same as offensive exploitation to a safety filter. Cheaper models that did engage, including GPT-6 Luna and Xiaomi's MiMo-V2.6-Pro, completed roughly 100 bug hunts for about $20. For security teams, this changes how to pick a model. A higher general intelligence score does not help if the model declines the job, so refusal rate on your own defensive tasks belongs in the evaluation alongside accuracy and cost. It also explains why labs are building gated access programs for defenders, since a general filter cannot tell intent from the request alone.

Restricting offensive without blocking defensive is difficult, as finding and proving a vulnerability requires the same steps whether the goal is to exploit it or patch it On CyberGym-E2E-AA, a benchmark that measures cyber defense capabilities from discovery to patching on memory-safety tasks, some frontier intelligence models are safety blocked from responding on 85%+ of tasks. The good news is that some of the most capable models are also the most cost effective. With GPT-6 Luna or MiMo-V2.6-Pro, you can run ~100 bug hunts in a 1M+ line codebase for ~$20 - up to 100x cheaper per task than the next most capable model Grok 4.7.

Context
Safety rules meant to stop AI models from helping attackers can also stop them from helping defenders, according to Artificial Analysis. Its argument is that finding a software vulnerability and proving it is real takes the same steps whether the goal is to exploit it or to patch it, so the steps alone do not show which goal they serve. On its CyberGym-E2E-AA , some frontier models were safety blocked, meaning they declined to respond, on 85% or more of the tasks. The benchmark covers defensive work from finding a bug to patching it, on memory-safety tasks. Memory-safety bugs are flaws where a program reads or writes memory it should not, a common source of serious security holes.
A model that refuses most of the work is of little use to a security team, however capable it is. The same post reports that cost points the other way from what one might expect: some of the most capable models on the benchmark are also among the cheapest to run. Artificial Analysis estimates that GPT-6 Luna or MiMo-V2.6-Pro can run about 100 bug hunts in a codebase of more than a million lines for about $20. It says that is up to 100 times cheaper per task than Grok 4.7, which it ranks as the next most capable model. The post's text does not name the models that refused, and its chart was not reviewed here.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
Checking sign-in…
Loading comments…