Reka Quantization Technology
- Source
- reka.ai
- Author
- Reka AI
- Date
Context
Reka describes a way to compress a model's numerical weights while recovering some of the accuracy lost in the conversion. Reka Quant converts weights in stages, freezes those already converted, and trains the remaining network to match the original model's outputs. It also measures each layer's current behavior before converting it, so corrections reflect changes already made elsewhere. The technical article explains how these steps address both local rounding errors and interactions across layers.
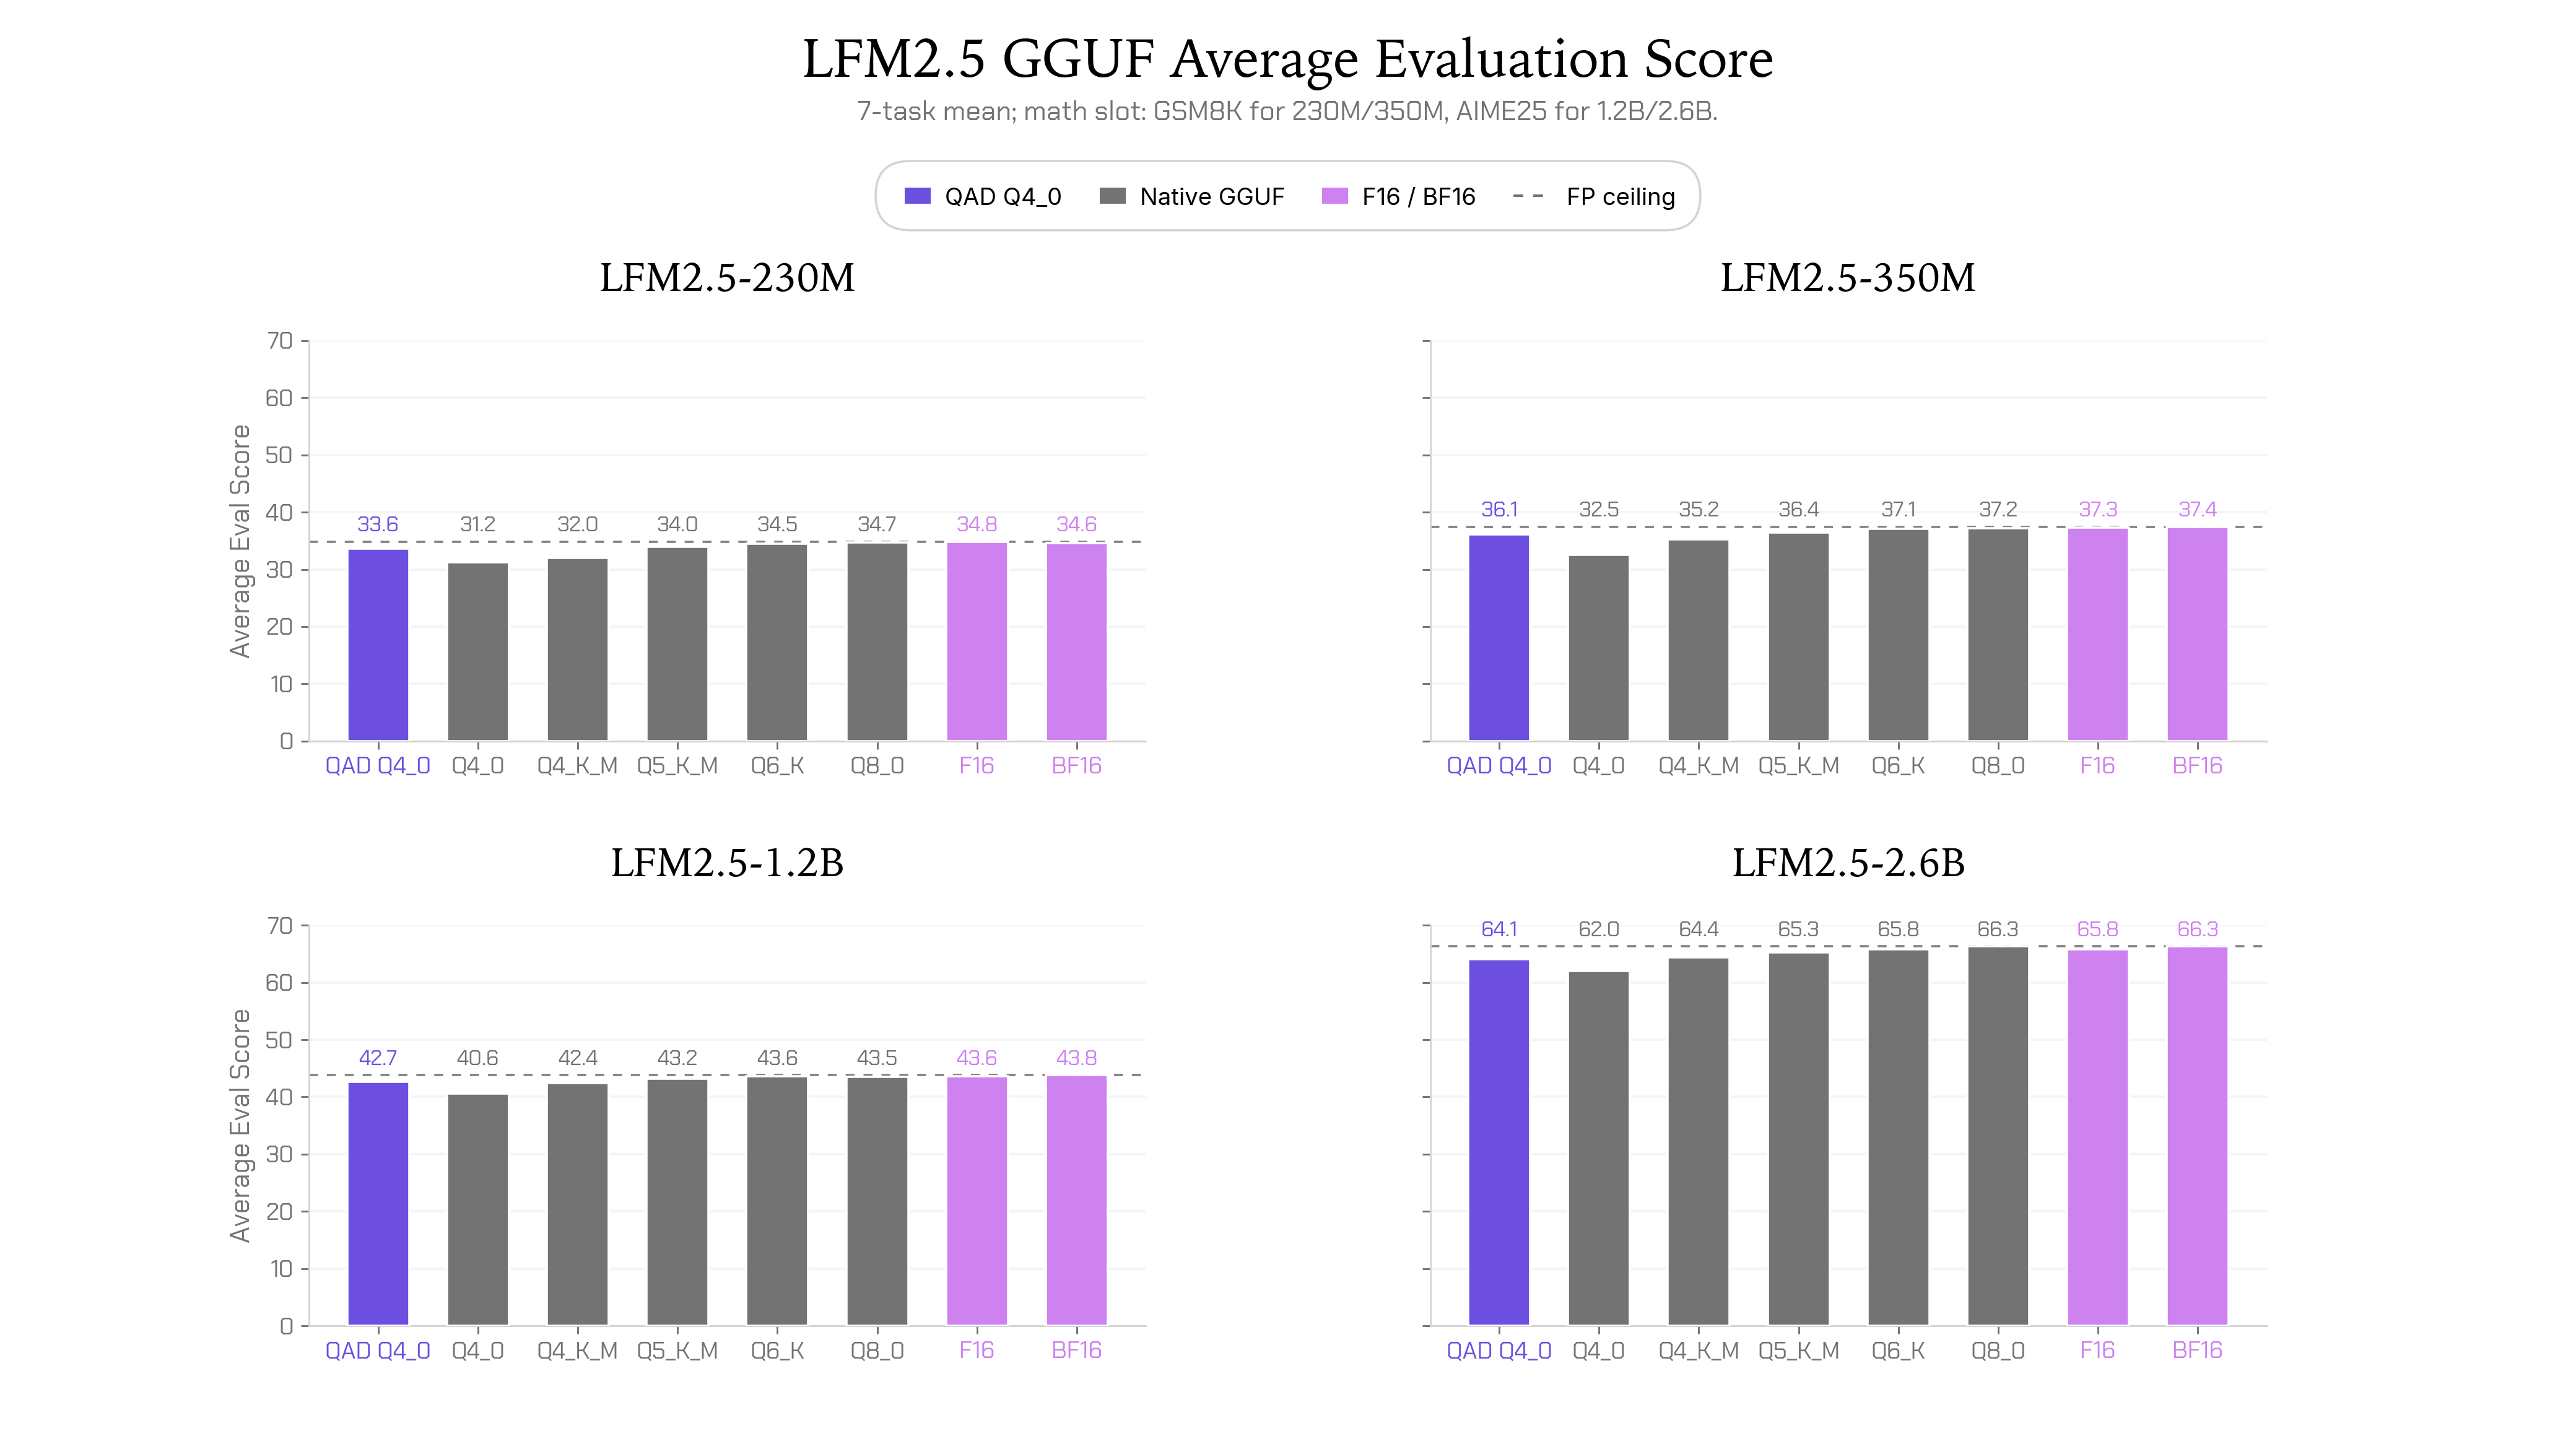
For Flash 3.1 at 3.5-bit precision, Reka reports an average reasoning- decline of 1.6 points, compared with 6.7 points for llama.cpp's own -based method at the same precision. The result concerns that compression setup, rather than lossless compression in general.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- calibration — How well a model's confidence matches reality — a calibrated model saying "90% sure" is right about 90% of the time.
- quantization — Shrinking a model by storing its numbers less precisely — like rounding — so it runs faster and fits on smaller hardware, at a small quality cost.
- distillation — Training a small, cheap model to imitate a big one's outputs, keeping much of the capability at a fraction of the cost.
Checking sign-in…
Loading comments…