Understanding LLM Architectures Workflow
- Source
- magazine.sebastianraschka.com
- Author
- Sebastian Raschka, PhD
- Date
Context
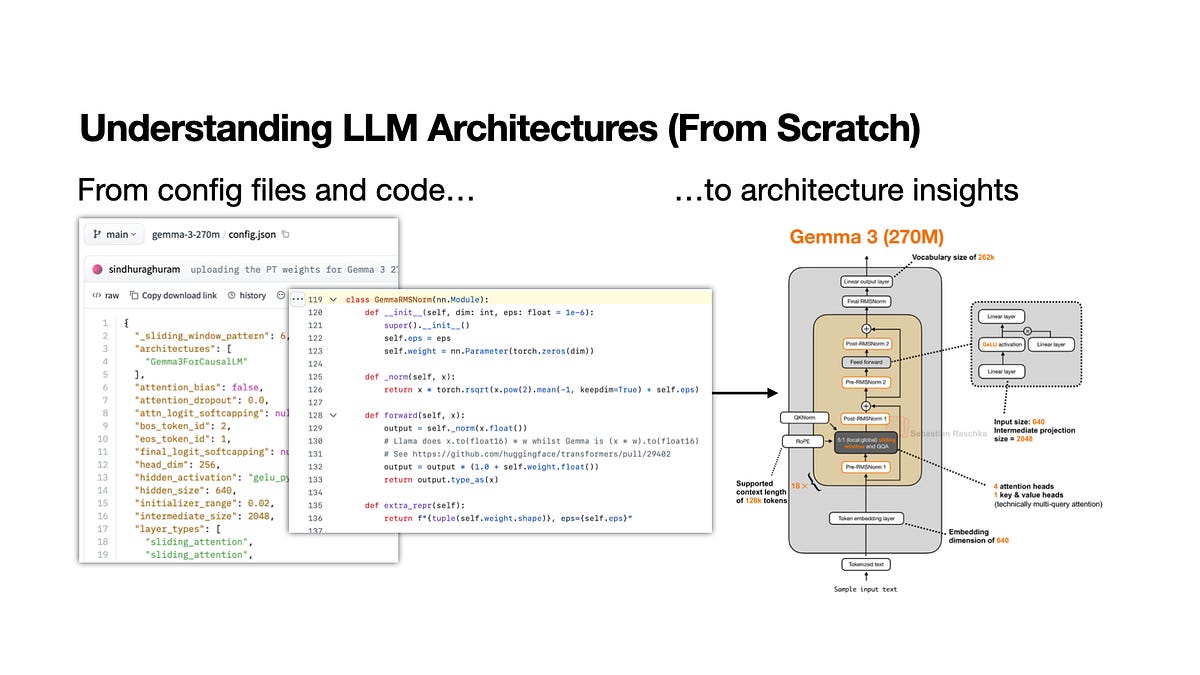
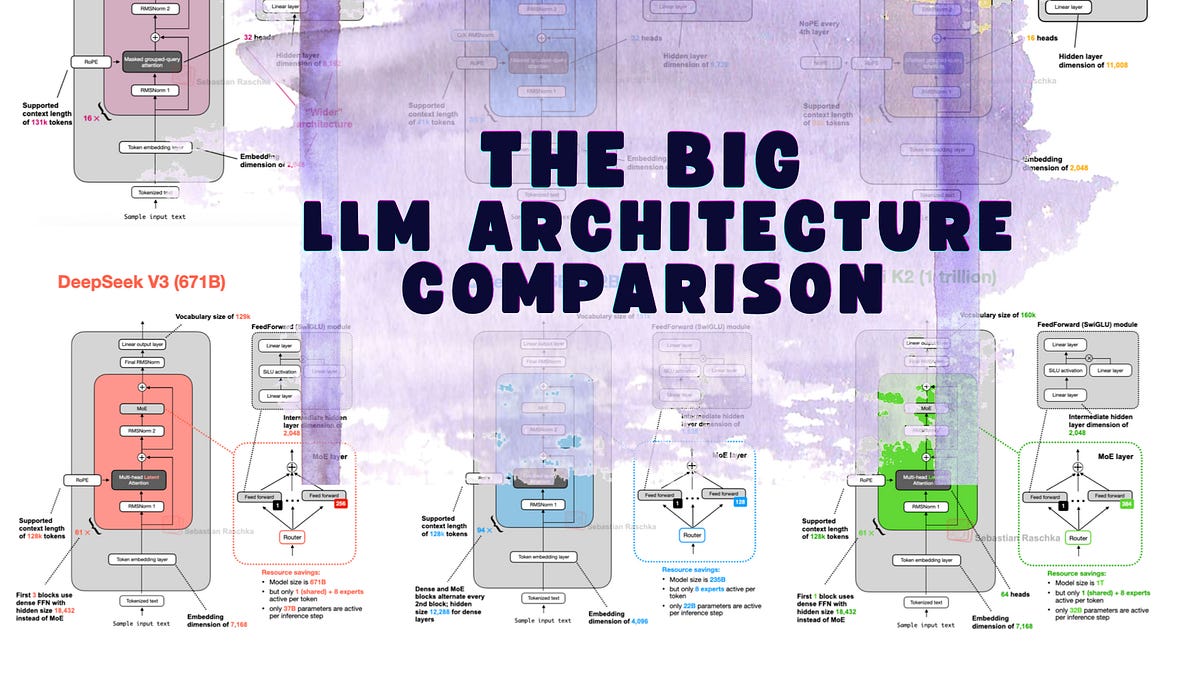
An model's configuration and reference code can fill architectural gaps left by its technical report. Sebastian Raschka describes a learning workflow that starts with the report, then checks those implementation materials to understand how the model is assembled.
The value is in tracing concrete choices rather than relying entirely on a high-level diagram. Raschka recommends doing some of this manually because the investigation itself teaches the architecture. The approach depends on implementation details being available; it cannot reveal the hidden internals of a proprietary model merely by inspecting its public interface.
- Industry-lab technical reports have thinned out, but when weights ship on the Hugging Face Hub and the model is supported in the transformers library, the config file plus the reference implementation supply the architecture details the paper skipped.
- The method only reaches open-weight models. For ChatGPT, Claude, or Gemini there is no config or reference code to read, so architectural claims about them stay unverifiable from the outside.
- Keep the process manual on purpose. Parts of the config-to-diagram walk could be scripted, but doing a handful of architectures by hand is what actually builds the understanding you were after.
- open weights — A model whose trained parameters are published for anyone to download and run — unlike API-only models you can access but never possess.
- LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
“But if the goal is to learn how these architectures work, then doing a few of these by hand is, in my opinion, still one of the best exercises.”
Checking sign-in…
Loading comments…