Meta previews WildArtifactBench and releases ten of its tasks
- Source
- x.com
- Date

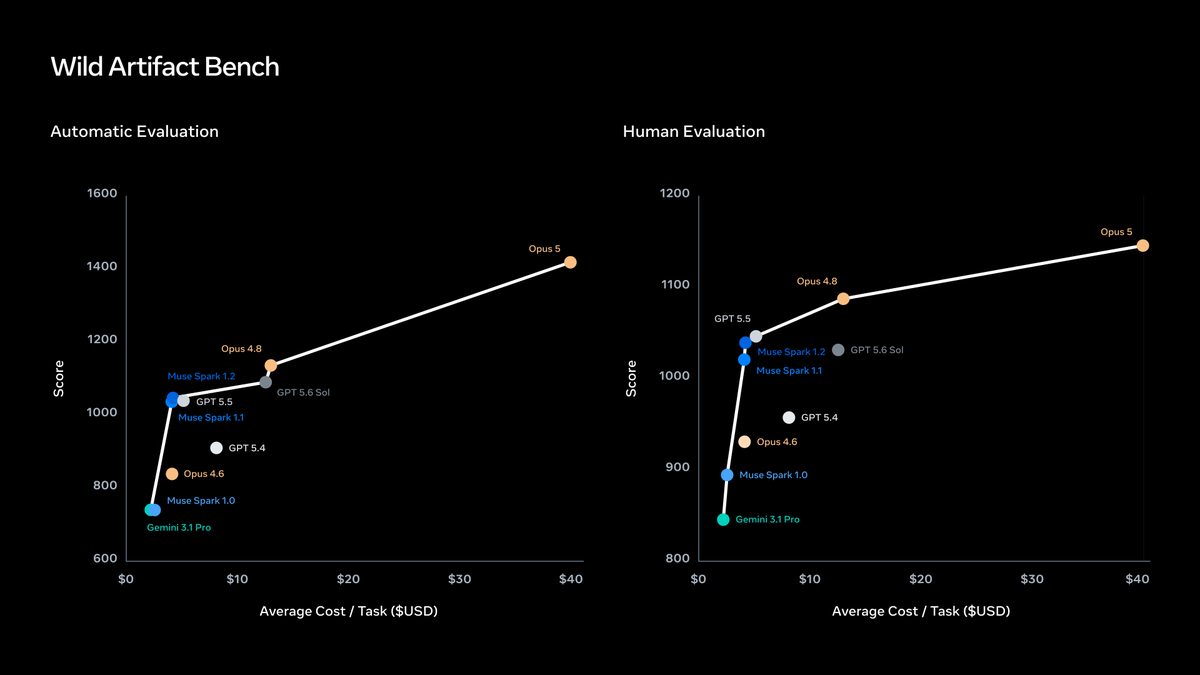
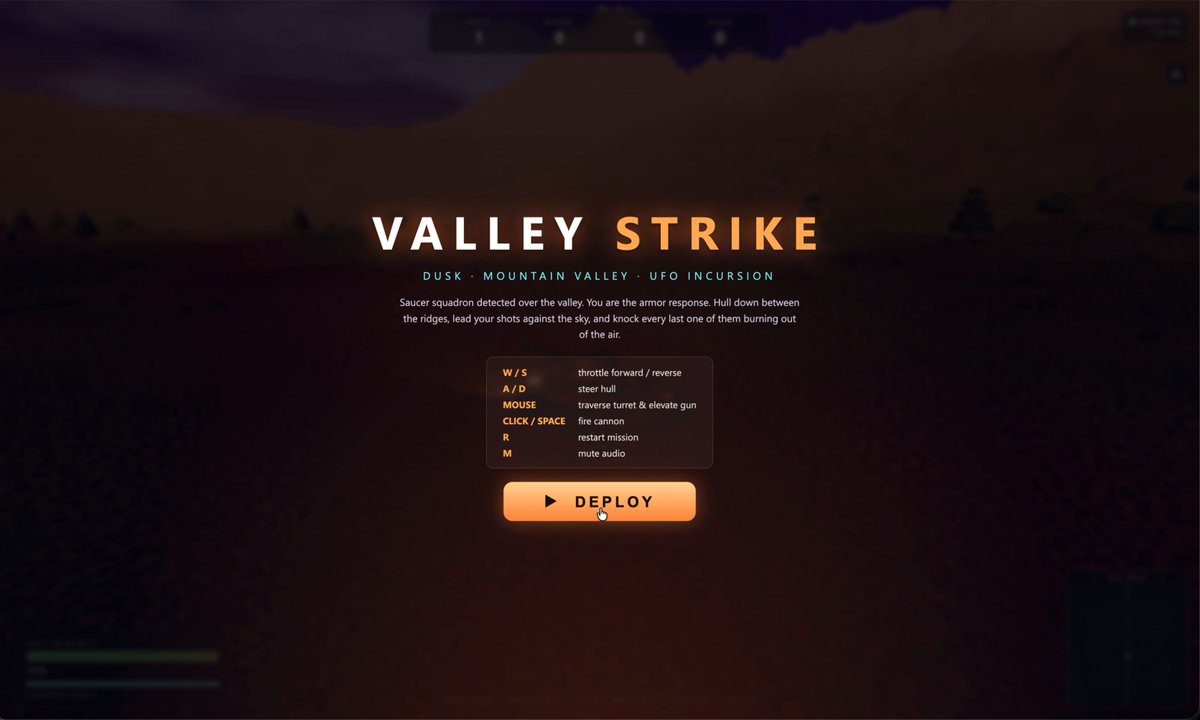
Today we’re also previewing WildArtifactBench, an internal evaluation framework designed to assess agents on complex, real-world tasks across diverse deliverable formats. By using win rates and Elo scores from human and agentic preference judges rather than strict ground-truth rubrics, it expands task coverage across practical multimodal workflows. We’re releasing 10 tasks from WildArtifactBench as a step forward in our ability to measure the real practical utility delivered by multimodal agents:


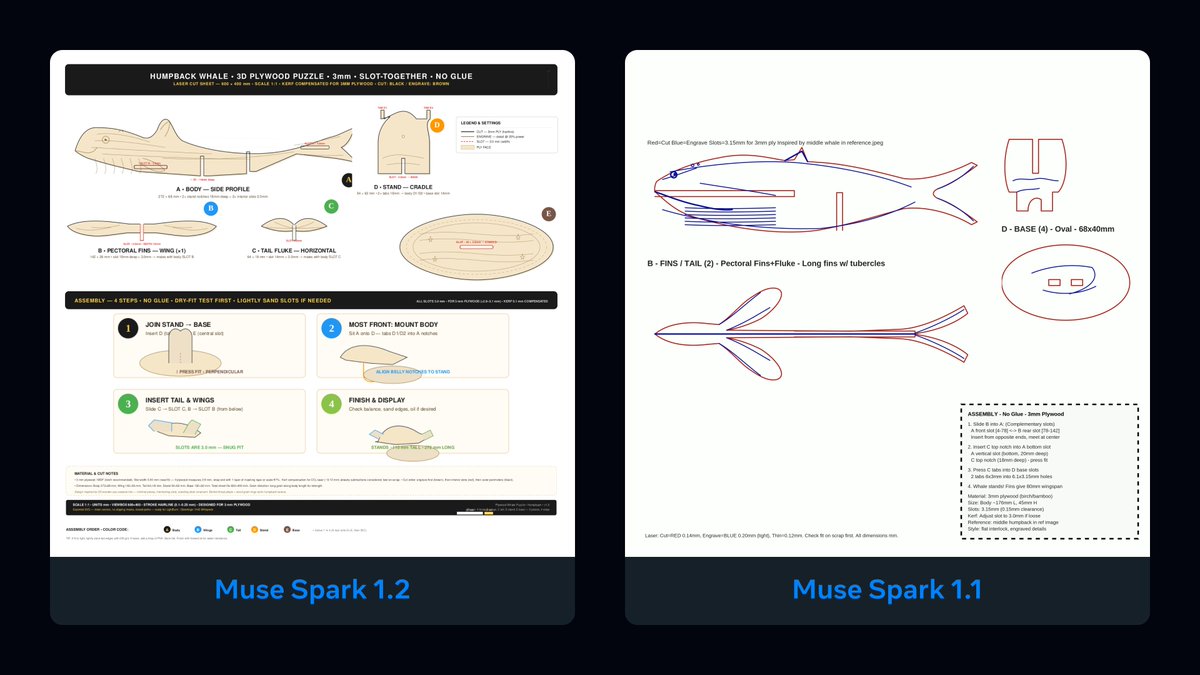
Here are the generated artifacts of Muse Spark 1.1 and 1.2 on the Plywood Whale: https://t.co/q5dATHjPGZ
A frontier lab publishing preference judged tasks gives the field an alternative to rubric bound benchmarks.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
Checking sign-in…
Loading comments…