Parallel Search ties for first on the AA Search Index at $0.014 per task
- Source
- x.com
- Date

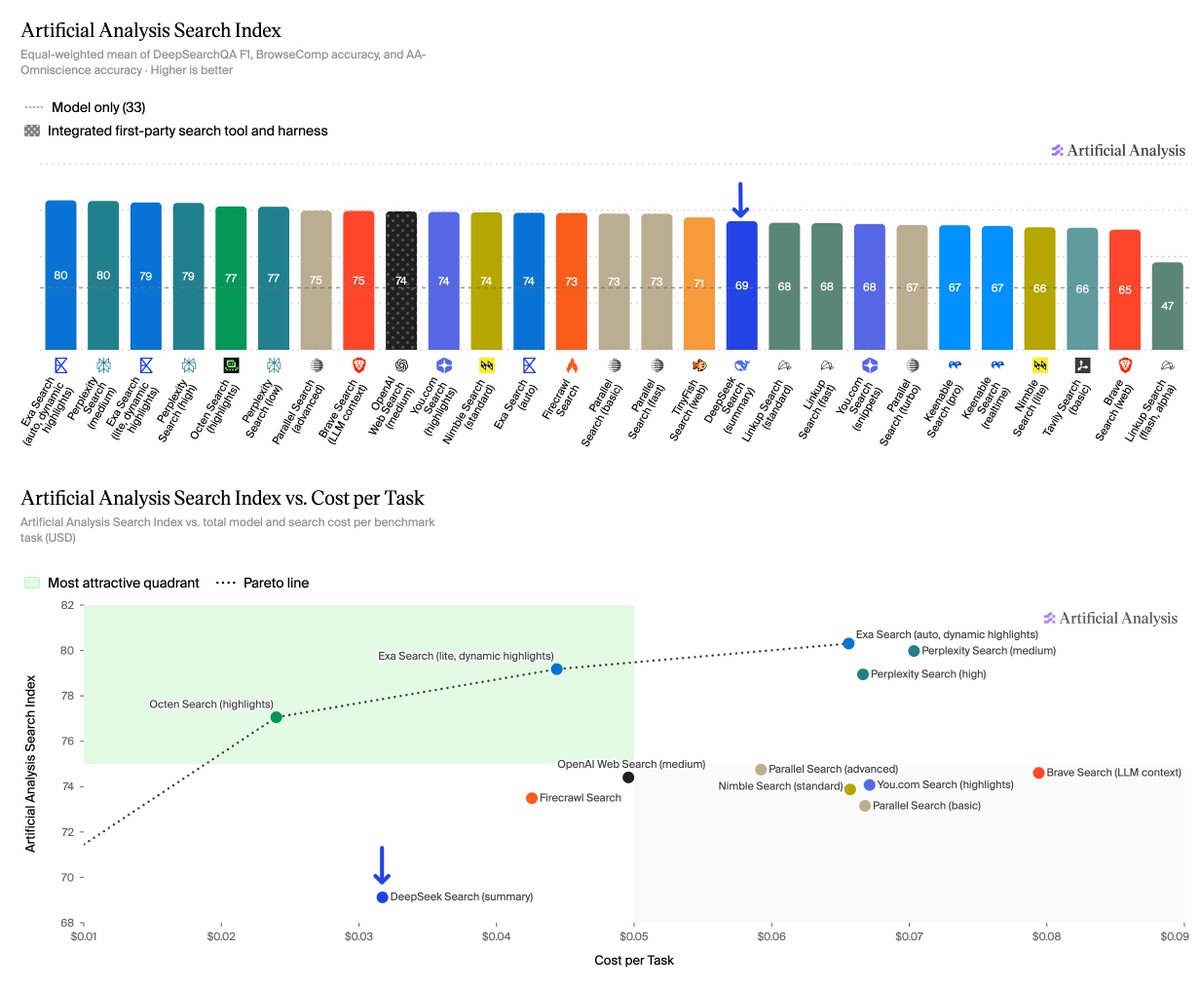
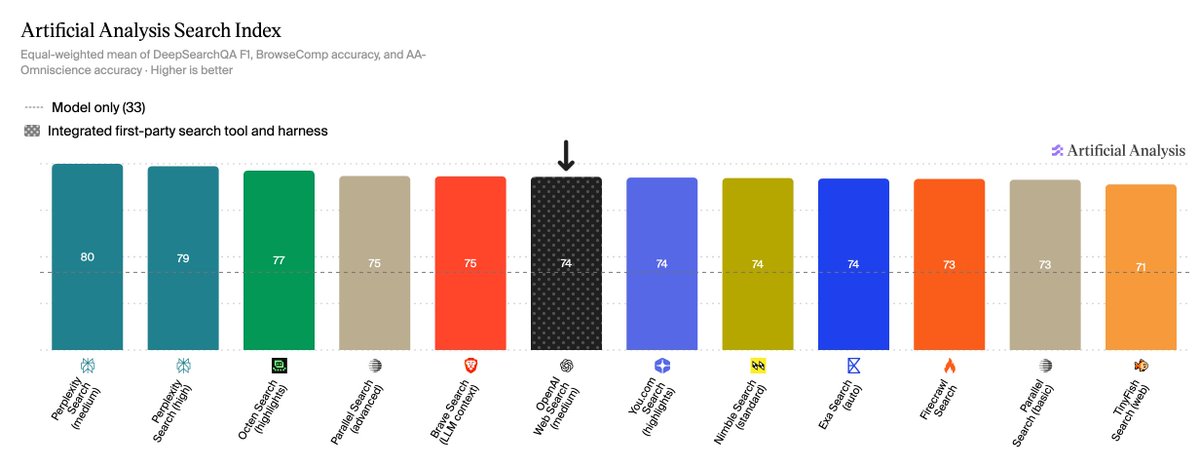
Parallel Search scores 83 on the Artificial Analysis Search Index, level with Keenable Search (pro) at the top of the board, with a fast mode at 82 for $0.014 per task We benchmarked two modes of @p0's Parallel Search API, fast and advanced, in our Stirrup agent harness with Parallel Search as its web_search tool to complete 1700 search-focused tasks. In our August runs, advanced scored 75 and fast scored 73. In these November runs, advanced scores 83 and fast scores 82. Key benchmarking results for Parallel Search: ➤ Artificial Analysis Search Index: Parallel Search (advanced, objective) scores 83, 1st of 26, and Parallel Search (fast, objective) 82, 4th. That is a ~50-point lift over the same model with no search (33). Advanced is level with Keenable Search (pro) at 83 and 3 points ahead of Exa (auto, dynamic highlights) and Perplexity (medium) at 80. Fast is slightly ahead of both ➤ DeepSearchQA is Parallel's strongest benchmark: both modes score 89 F1, 1st and 2nd of 26, comparable to Keenable Search (pro) at 88. Advanced also ranks 1st on AA-Omniscience (74%), just ahead of Keenable Search (pro) (73%), and 3rd on BrowseComp (87%, level with Keenable Search (pro) and…

Context
Parallel's search API now shares the top score on the Artificial Analysis Search Index, and its cheaper fast mode trails by one point. Search APIs are the services an calls to look things up on the web. To compare them, Artificial Analysis, an independent benchmarking firm, holds everything else fixed: the same model, OpenAI's GPT-5.6 Luna at medium reasoning, works in the same , Stirrup, with up to 25 turns per task, and only the provider behind its web search tool changes. The index averages three benchmarks totalling 1,700 tasks: 900 deep-research questions, 200 hard web-search questions and 600 private factual questions. Without any search, the model scores 33.
In its November runs, Artificial Analysis found Parallel's advanced mode scoring 83, level with Keenable Search's pro mode, which took first place earlier this month, and 3 points ahead of Exa and Perplexity at 80. Fast mode scored 82. Both modes improved since Artificial Analysis first tested them in August, when advanced scored 75 and fast 73.
The practical difference between the two modes is cost. Artificial Analysis counts a task's cost as the model's own use plus the search provider's fees for the searches the model chose to run. Fast mode, priced at $1 per 1,000 requests, comes to about $0.014 per task, second lowest of the 26 search products tested and well below the board median of $0.063. Advanced mode, at $5 per 1,000 requests, comes to about $0.030, and Keenable's pro mode to about $0.040. The leaderboard also shows fast mode completing a task in about 15.5 seconds, against about 24 seconds for advanced. For an agent that searches constantly, fast mode gives up one point of score for less than half the cost and quicker answers.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- agent harness — The scaffolding around a model that turns it into a working agent — the loop, the tools it can call, and the rules for when to stop.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.

Checking sign-in…
Loading comments…