ElevenLabs Scribe v3 ranks second on AA-WER at $0.20 per hour
- Source
- x.com
- Date

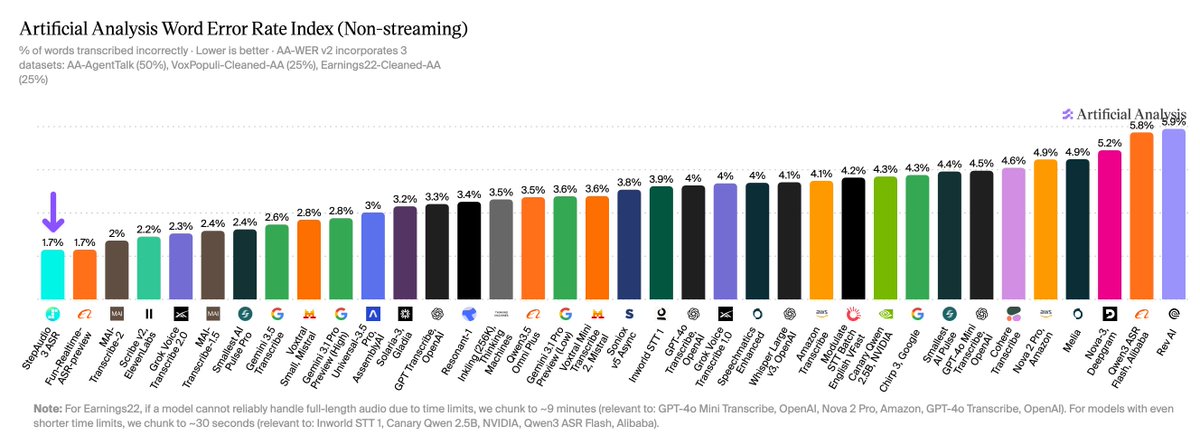
ElevenLabs' Scribe v3 ranks #2 on the AA-WER Index for non-streaming speech-to-text at 1.95% WER, improving on Scribe v2 (2.18%) In our independent benchmarks, it sits behind Alibaba's Fun-Realtime-ASR-preview (1.73%) and just ahead of Microsoft AI's MAI-Transcribe-2 (2.04%). Congratulations to @ElevenLabs on the launch! 🧵

Context
ElevenLabs' new Scribe v3 speech-to-text model gets about two words in every hundred wrong on the transcription run by Artificial Analysis, an independent firm that tests AI models, which ranks it second among models that transcribe recorded audio. The firm scores models by word error rate (WER): it compares each transcript with a human-checked reference and counts every word the model swapped, dropped or added, as a share of the words in the reference. Its AA-WER Index covers about eight hours of audio, half from a private set of speech typical of voice agents and the rest from European Parliament speeches and company earnings calls. Artificial Analysis reports that Scribe v3 scores 1.95%, behind Alibaba's Fun-Realtime-ASR-preview at 1.73% and just ahead of Microsoft AI's MAI-Transcribe-2 at 2.04%.
The independent result confirms that Scribe v3 improves on its predecessor, though by less than ElevenLabs' own figure. Scribe v2 scored 2.18% on the same index, so the new model makes roughly a tenth fewer errors there. In its launch post, ElevenLabs says Scribe v3 makes 27% fewer word errors than Scribe v2, but that figure comes from its own test of short, clean read speech in 102 languages. The two numbers measure different recordings, so they are not directly comparable.
Near the top of the index the accuracy gaps are fractions of a point, which makes price matter more. Artificial Analysis estimates that Scribe v3 costs $3.33 to transcribe 1,000 minutes of audio, about 20 cents an hour, against $2.82 for Alibaba's model and $1.67 for MAI-Transcribe-2. On this index, Alibaba's model is both more accurate and cheaper, and Microsoft's costs half as much for about one extra error per thousand words. The case for Scribe v3 rests less on its score here than on the additions ElevenLabs describes, such as more accurate speaker labels and lists of up to 1,000 expected terms like product names.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- streaming — Sending a model's response token by token as it is generated, so the reader sees text immediately instead of waiting for the whole answer.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
Checking sign-in…
Loading comments…