Thinking Machines' Inkling 2 Mini matches 27B models with 5.4B active parameters
- Source
- x.com
- Date

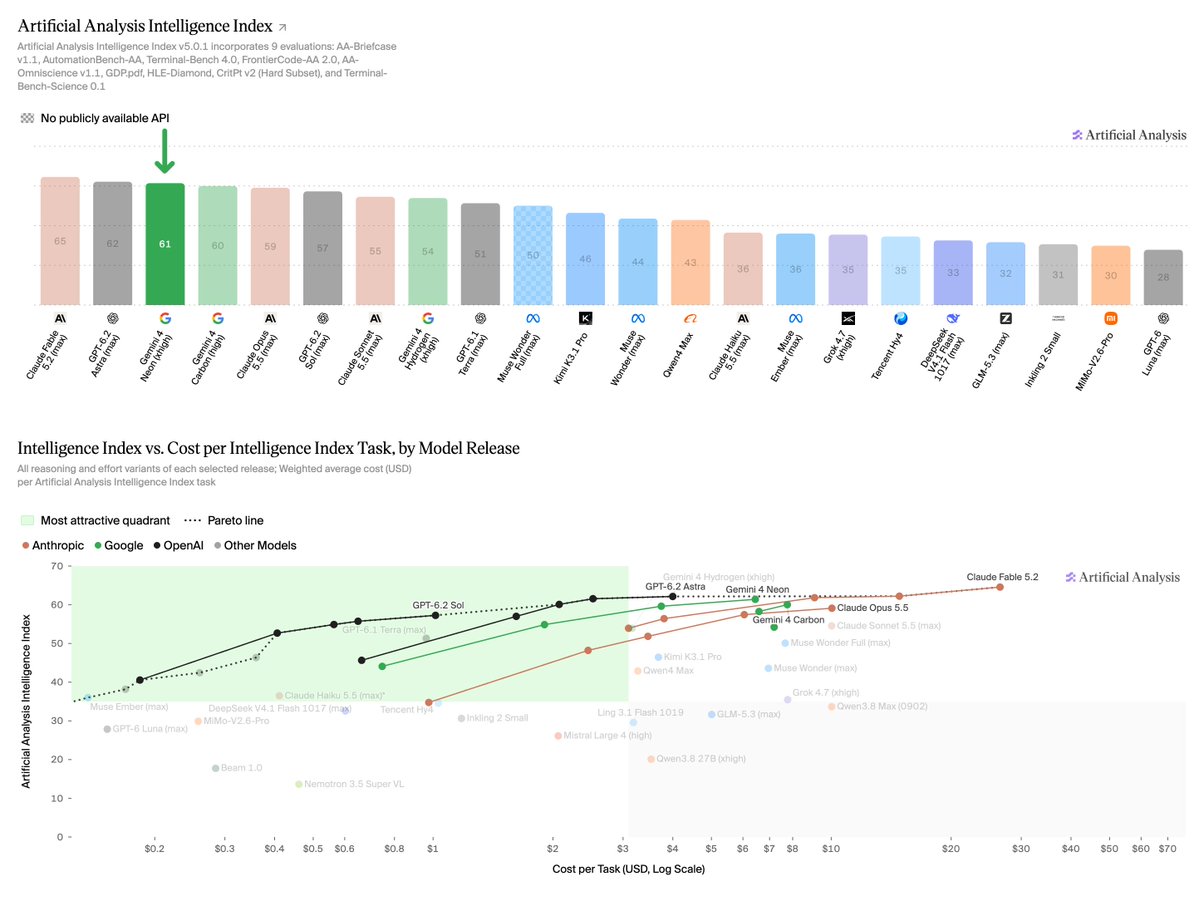
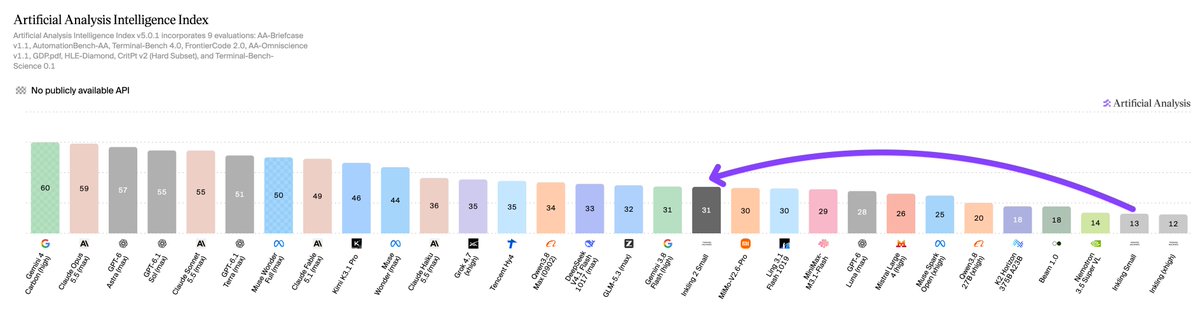
Thinking Machines has released Inkling 2 Mini at 20 on the Artificial Analysis Intelligence Index, an open weights looped transformer on the Pareto frontier for Intelligence vs. Active Parameters Inkling 2 Mini is a 26B total, 5.4B active parameter mixture-of-experts model. The 5.4B active parameter count includes three passes through its looped layers; it uses 3.1B unique weights per text token, and it is small enough to run on a MacBook or DGX Spark. It is released under an Apache 2.0 license, with text and image input and a 1M token context window. Congratulations to @thinkymachines on the release! 🧵

Context
Thinking Machines' new open-weights model, Inkling 2 Mini, scores 20 on the Artificial Analysis Intelligence Index, the same as Qwen's Qwen3.8 27B, according to the independent benchmarking firm's model page. The index combines nine evaluations that Artificial Analysis runs itself, mostly agentic coding and office tasks plus hard knowledge and reasoning questions. Among open models of similar size, the median score is 10. Inkling 2 Mini is a model: each layer holds many small expert networks and sends each , roughly a word fragment, to only a few of them, so the model stores 26 billion parameters but uses only a small share of them for any one token.
Artificial Analysis puts that share at 5.4 billion active parameters per token, while Hugging Face's launch post gives about 3 billion. Both describe the same model. Inkling 2 Mini is a looped : twelve of its 24 layers run three times in a row with the same weights, and each pass refines what the previous one computed. As Artificial Analysis explains, its 5.4 billion counts all three passes through those layers, which reflects how much computation each token takes, while the model uses 3.1 billion unique weights per token, close to Hugging Face's figure. On a chart of index score against active parameters, Artificial Analysis places the model on the Pareto frontier, meaning no model it has tested scores higher with fewer active parameters.
The appeal is a capable model that fits on a desk. Artificial Analysis says Inkling 2 Mini is small enough to run on a MacBook or a DGX Spark, and it is released under the Apache 2.0 license, accepts text and images, and handles a of one million tokens. Artificial Analysis also rates it very verbose: it produced 161 million output tokens while running the index, against a median of 85.7 million for comparable models.
- mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- transformer — The neural network architecture behind modern AI models, built on attention — letting every word directly consider every other word in parallel.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
Checking sign-in…
Loading comments…