Epoch AI's furniture benchmark exposes opposite failure modes in vision models
- Source
- x.com
- Date
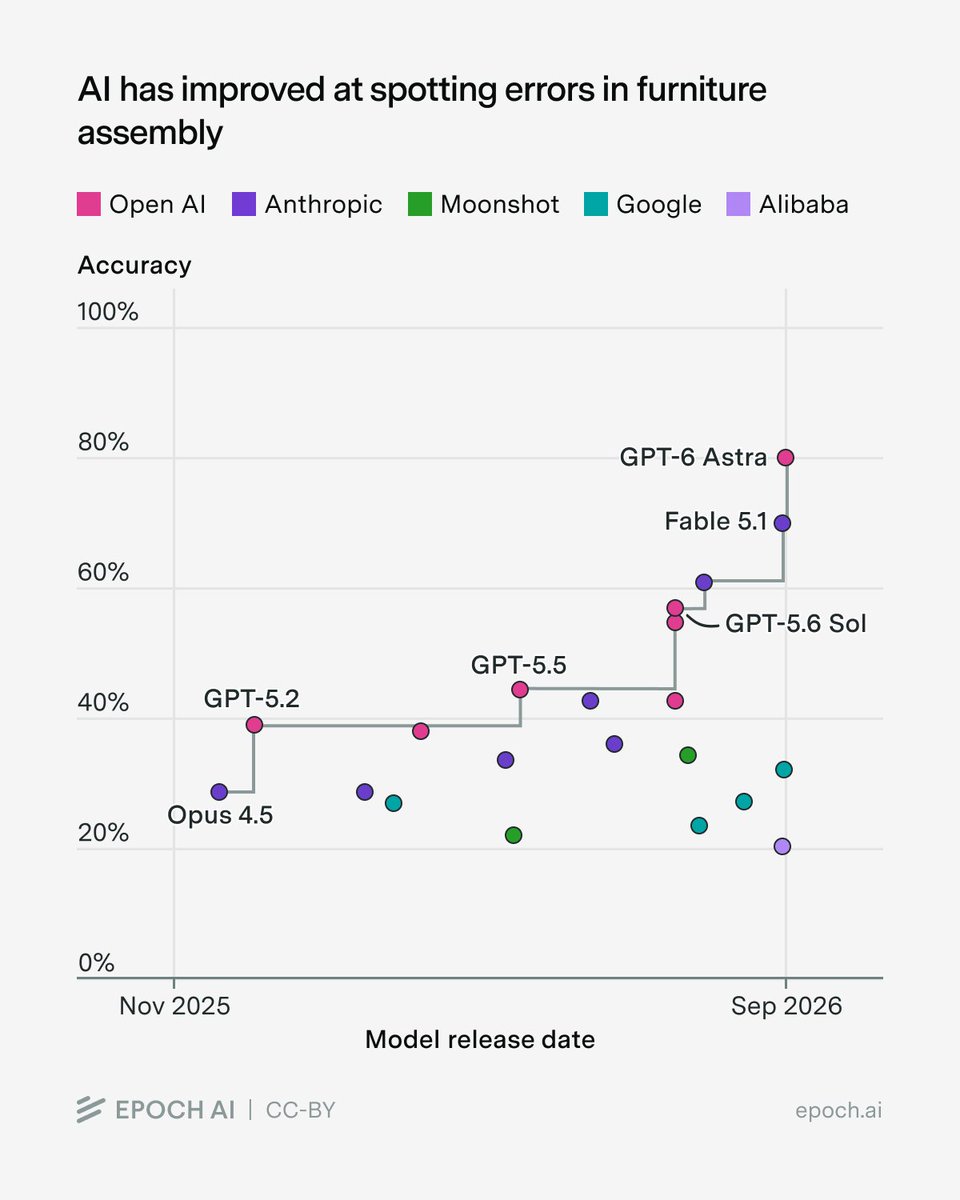
Epoch AI released the Furniture Assembly Benchmark, or FAB, which gives a model the assembly manual and a photo of a partly built piece of furniture and asks it to spot the error. The set is small, 60 photos across three builds, but the trend is steep: the best score went from 28% to 80% in ten months. Epoch notes two ways to fail, missing a real mistake or flagging a correct build, and says frontier models tend to lean one way. Gemini 3.1 Pro passes almost no correct builds, while GPT-5.4 catches almost no mistakes. GPT-6 Astra was both the most accurate and the fastest model tested. Epoch argues the task stands in for economically useful visual reasoning such as car or appliance repair, so the split in failure modes is worth checking before trusting any model as an inspector.

Can AI tell if you've built your IKEA furniture wrong? Our new benchmark, the Furniture Assembly Benchmark (FAB), gives models the manual and a photo of a half-completed piece of furniture and asks them to spot the mistake. The top score has gone from 28% to 80% in just 10 months.
Context
Epoch AI built the Furniture Assembly , or FAB, to test whether an AI model can check physical work against written instructions. Each question gives a model the assembly manual and a photo of a half-completed piece of furniture, and asks it to spot the mistake in the build. To answer, the model has to work out which step the photo shows, compare it with what the manual says should be there, and find where the two differ.
Epoch reports that the top score on FAB has gone from 28% to 80% in ten months. The best model went from answering fewer than three in ten questions correctly to answering eight in ten, which is a large change on a task that combines reading diagrams with looking at real photos. The announcement post does not say which models set either score, how many questions the benchmark has, or how answers are graded, and the chart attached to it was not part of the text reviewed here. Epoch later published a longer write-up of the benchmark.
What the post supports is a fast improvement at the top of the field on one specific visual checking task. It does not establish how any particular model performs, or how often a model would catch a given error outside the benchmark's set of photos.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
Checking sign-in…
Loading comments…