Reshaping the SDK lifted agent execution reliability to 92.6%
- Source
- x.com
- Date

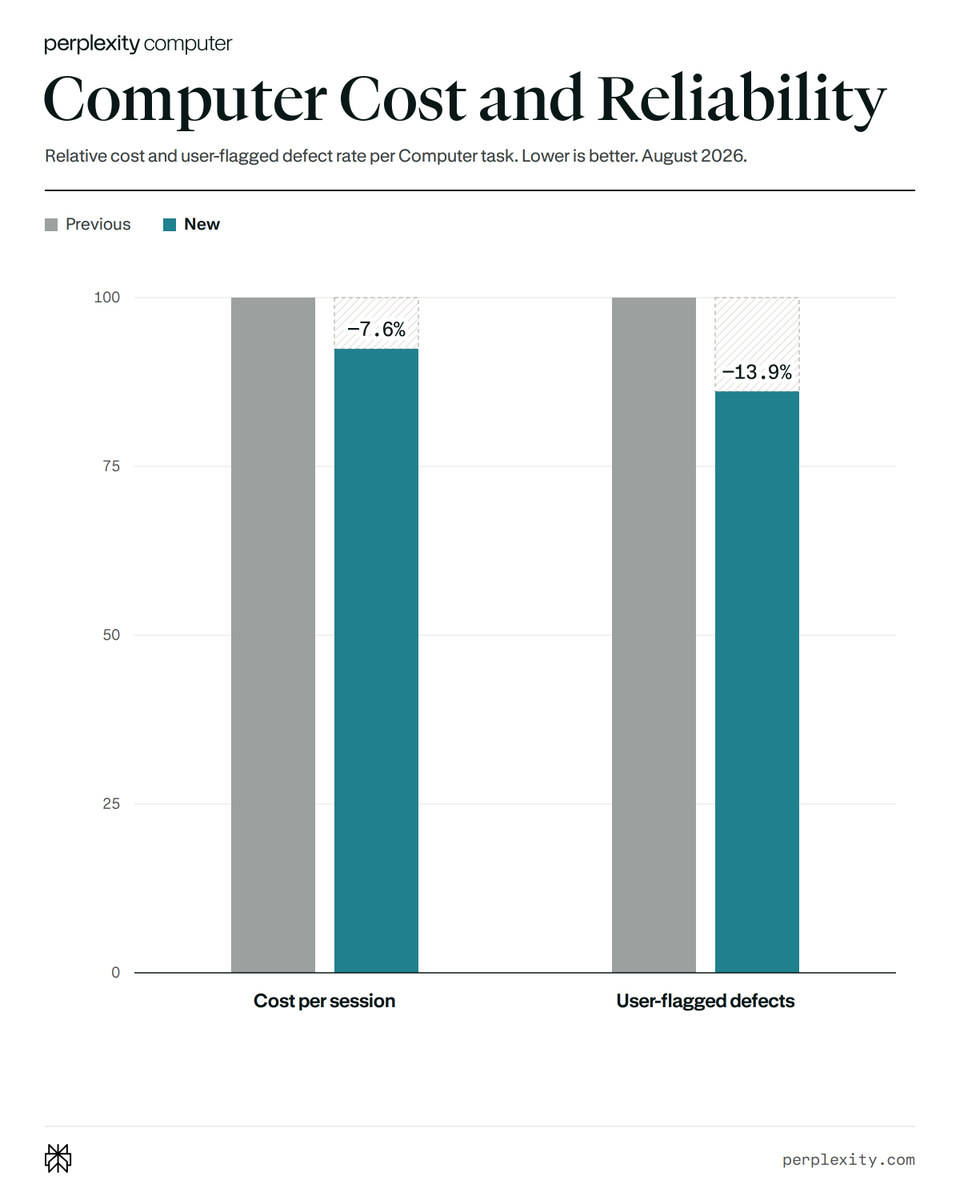
We released Search as Code (SaC) in June, achieving state-of-the-art performance on wide and deep research. This week, we’re rolling out optimizations to SaC that further improve performance while cutting cost per task by nearly 10%.

How an SDK is shaped determines how well models can use it. We’ve rolled out two batches of Search SDK updates within Computer, raising execution reliability from 81.9% to 92.6%. More reliable action execution enables more capable orchestration.

These improvements show up across a wide range of real-world user workflows. In Computer, SaC optimizations delivered higher user satisfaction at an 8% lower per-task cost.
Context
Perplexity reports that changing the software interface used by its research increased successful code execution from 81.9% to 92.6%. Its August chart shows two update steps, with an intermediate rate of 86.2%. This measures whether generated code executes successfully, a narrower outcome than whether the final research answer is correct. The update thread and chart identify that measurement.
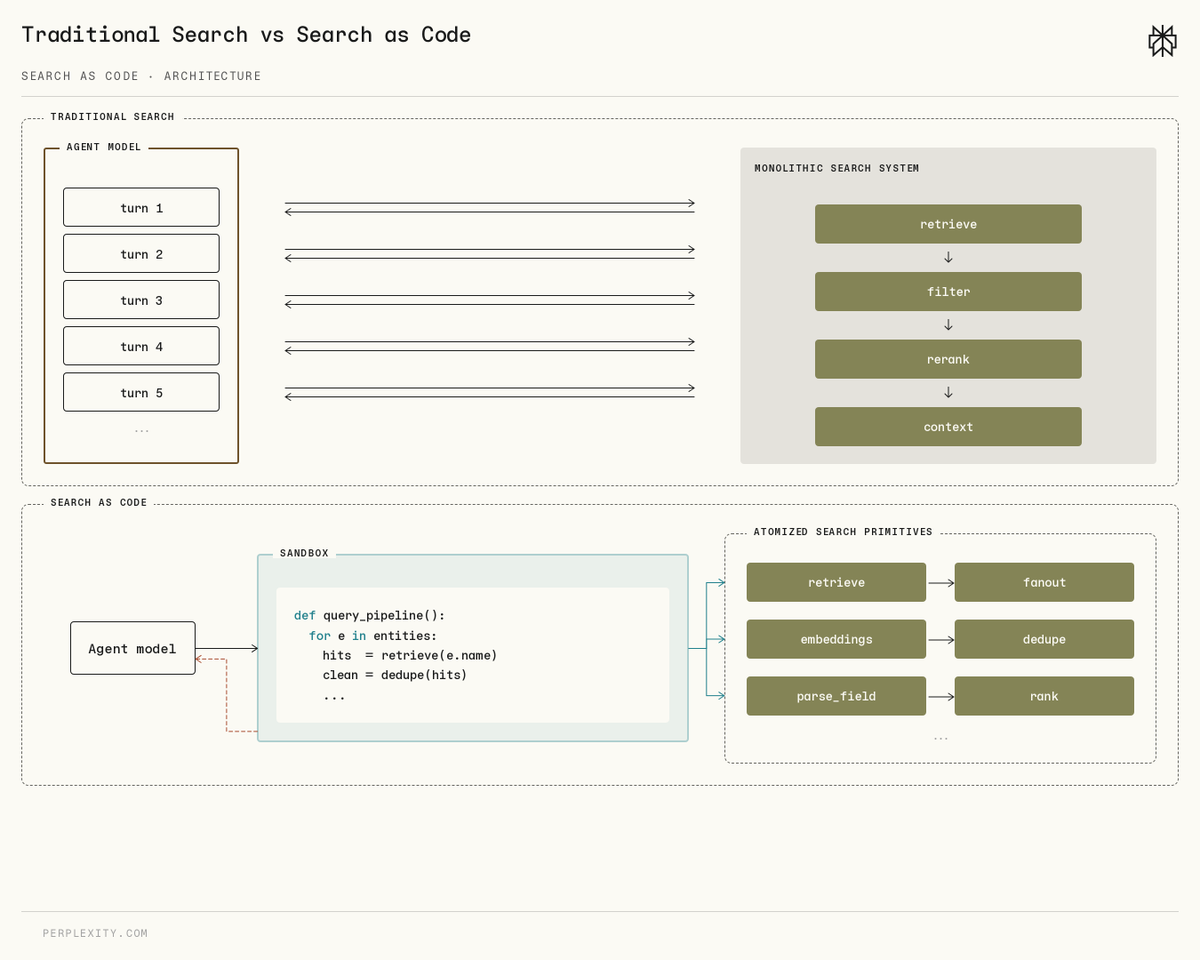
The interface matters because of Search as Code's design: the model writes programs that call a search library, so that library has to be one the model can use correctly. The thread puts it as "How an SDK is shaped determines how well models can use it." The architecture article describes the model-written Python and the SDK it calls.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
Checking sign-in…
Loading comments…