GPT-6.2 Astra and Sol land in Perplexity with WANDR cost-per-task numbers
- Source
- x.com
- Date

GPT-6.2 Astra and GPT-6.2 Sol are now available in Perplexity Search and Computer. On our WANDR benchmark, GPT-6.2 Astra scored 0.783 at about $12.54 per task, up 0.095 from GPT-6 Astra. GPT-6.2 Sol hit 0.746 at about $2.65, up 0.065 from GPT-6.1 Sol.

Context
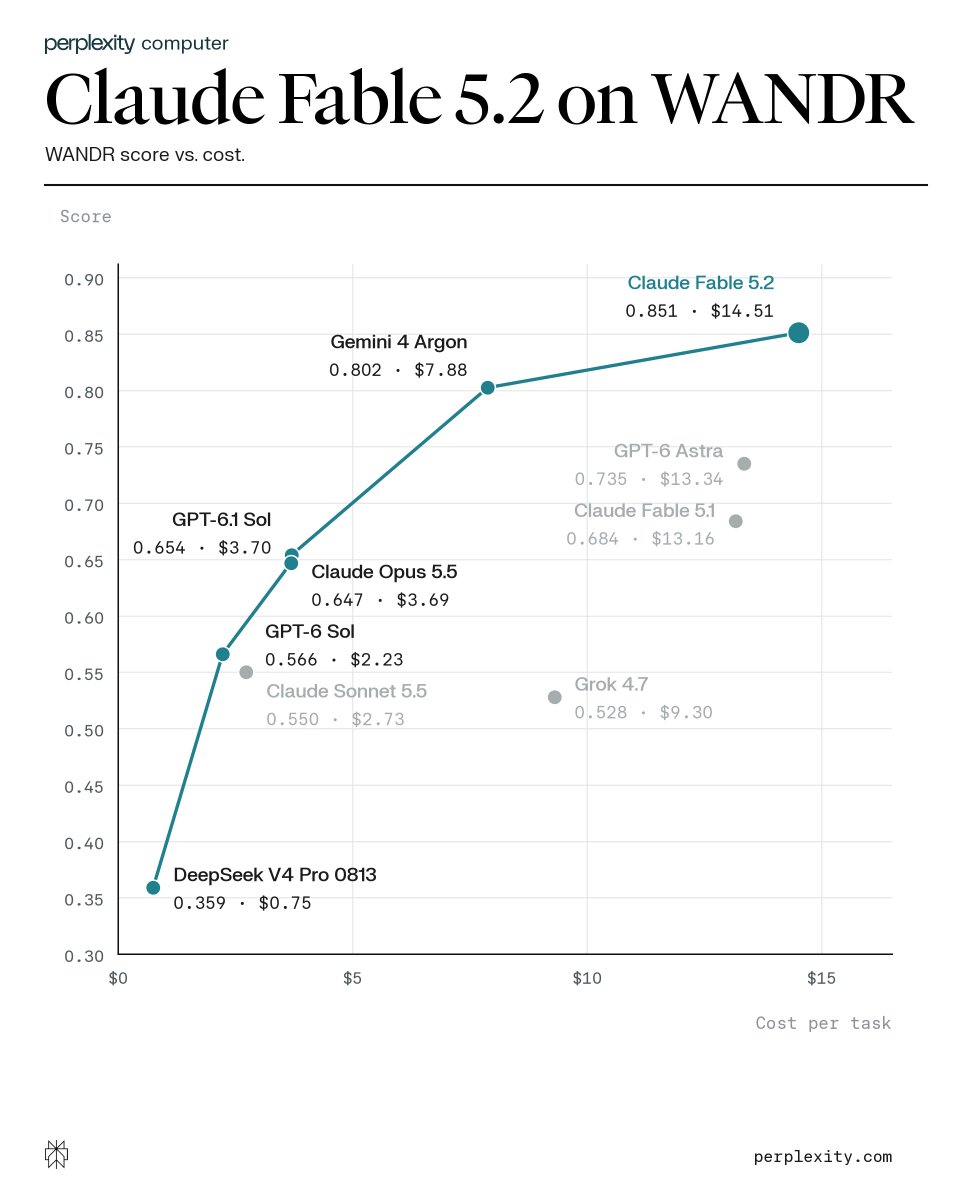
Perplexity has added OpenAI's GPT-6.2 Astra and GPT-6.2 Sol to Perplexity Search and Computer, and reports that both beat their predecessors on WANDR, its for research agents. Astra scored 0.783 at about $12.54 per task, 0.095 above GPT-6 Astra, and Sol scored 0.746 at about $2.65, 0.065 above GPT-6.1 Sol. The chart attached to the post shows that neither new model leads: Google's Gemini 4 Carbon scored 0.857 at $5.86 per task, and Anthropic's Claude Fable 5.2 scored 0.807 at $15.82.
WANDR tests wide research. According to Perplexity's launch post, it has 500 data-collection tasks, such as assembling every company that meets a condition along with evidence for each, and its grader re-fetches every page the cites to check that the page is usable and supports the claim. A higher score means a more complete collection whose entries hold up when their sources are checked.
On this chart, Sol is the more useful result. It scores above Gemini 4 Hydrogen (0.698 at $5.41) and Claude Opus 5.5 (0.662 at $5.33) at about half their cost per task, and above GPT-6 Astra at about a fifth of its cost. Astra's gain moves it closer to the top, but it costs more than twice as much per task as Gemini 4 Carbon for a lower score.
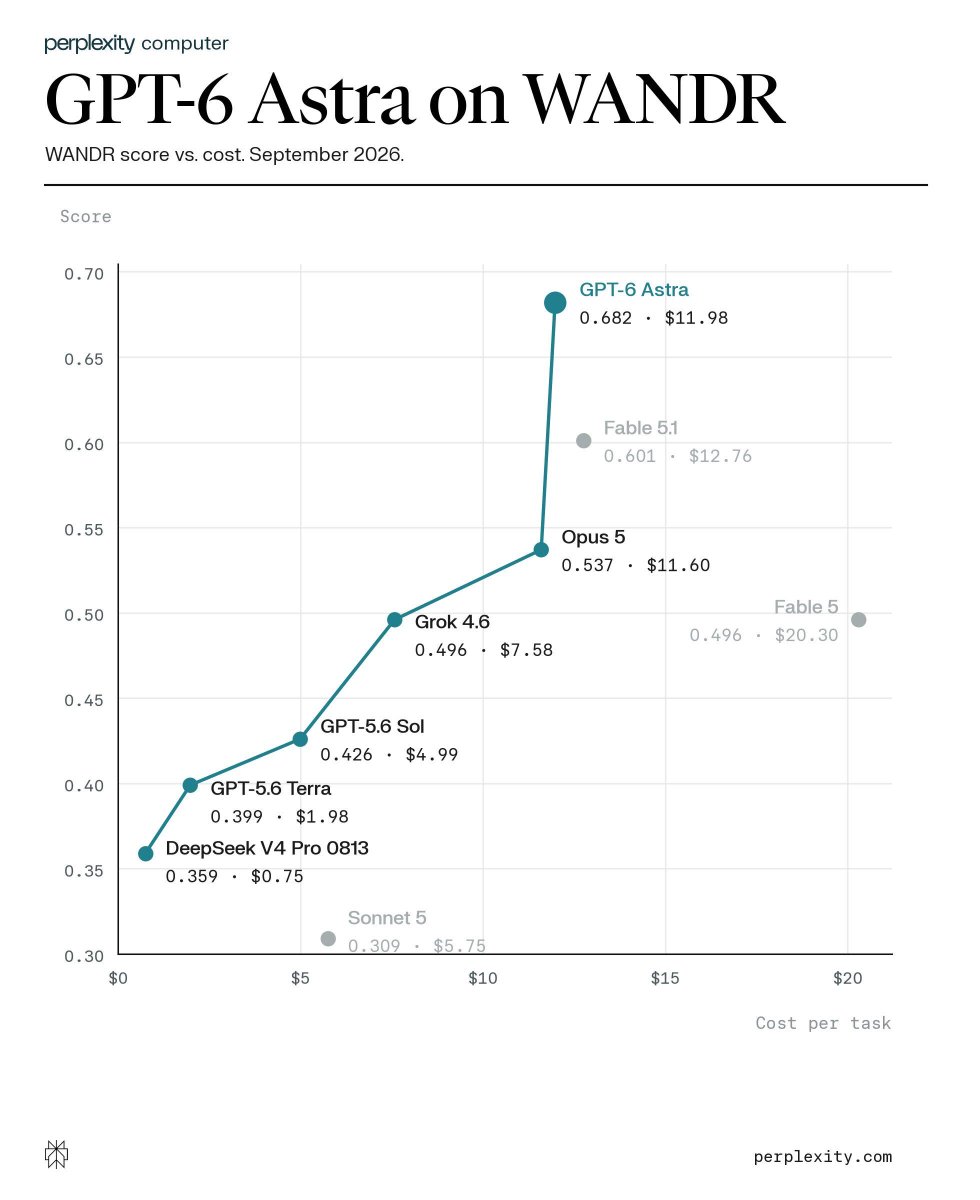
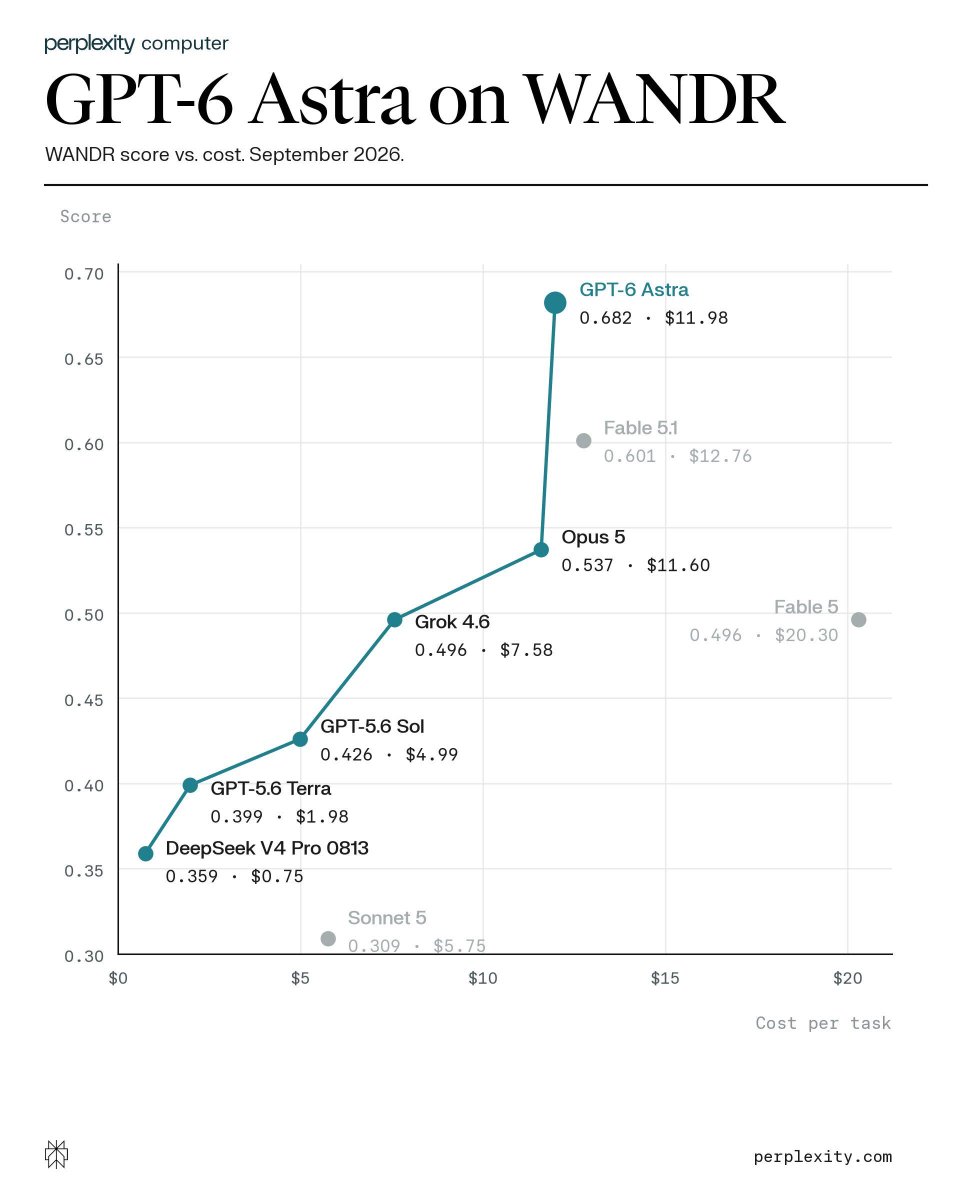
Perplexity built the benchmark, ran the tests and sells access to these models, and the post does not say which of WANDR's scores these are or how cost per task was counted. They should not be read against the launch post, where the best system reached 0.363 soft F1. They also move between Perplexity's own snapshots: in September it reported GPT-6 Astra at 0.682 and $11.98 per task, while this chart puts the same model at 0.688 and $12.73. The ranking is one internal run in Perplexity's product, useful for comparing models on the same chart rather than across charts.
Checking sign-in…
Loading comments…