Search as Code: let the model write retrieval instead of calling tools
- Source
- x.com
- Date

Introducing Search as Code, our new search architecture for AI agents. It writes Python that calls our search stack directly, instead of looping through function calls one at a time. Available in the Perplexity Agent API, and now default in Computer. https://t.co/ut6GGWQTVO
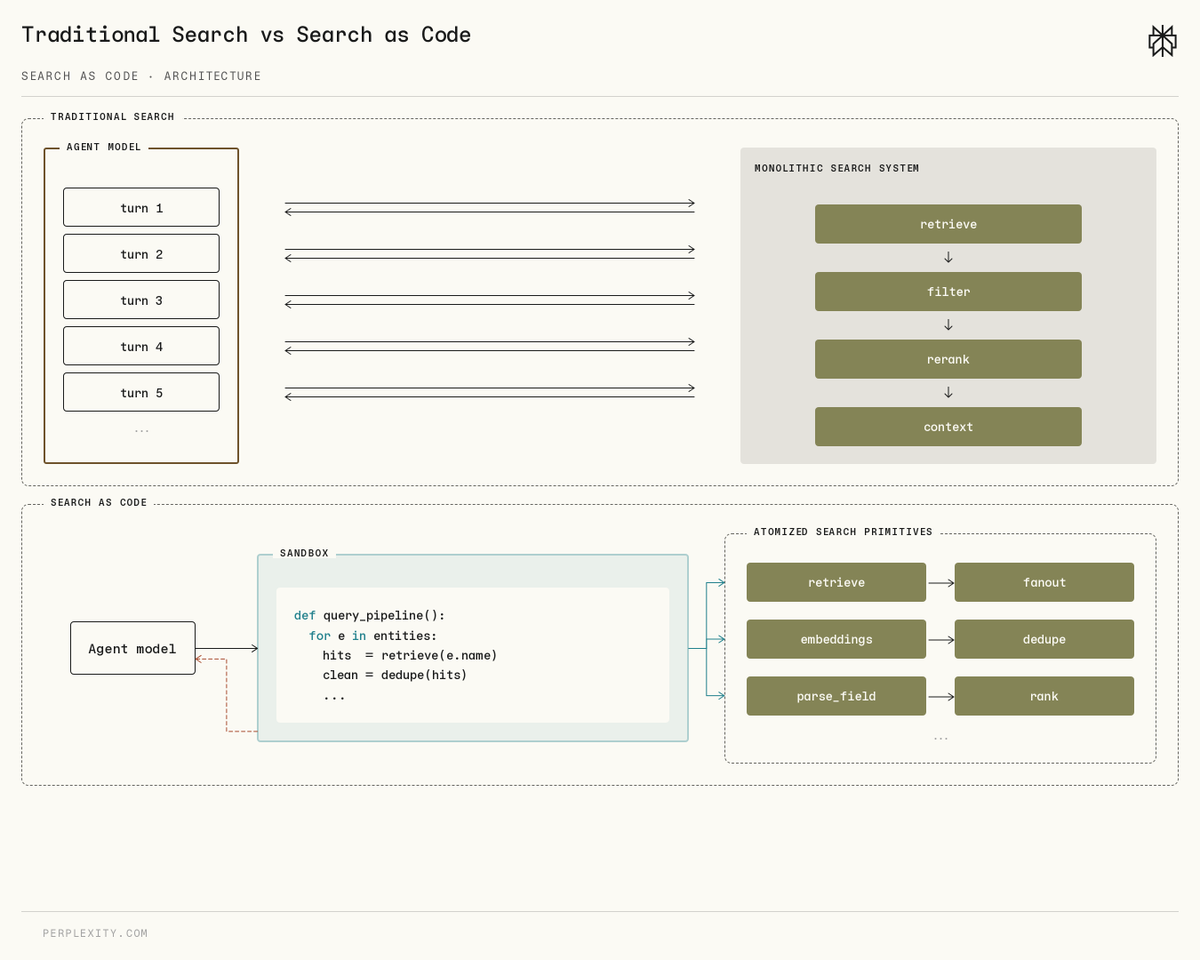
@PPLXDevs The traditional tool-calling approach suffers from high latency, manual control flow, and context pollution. With Search as Code, the model composes search primitives: fanning out queries asynchronously, deduping, filtering, joining, and ranking before results hits its context.

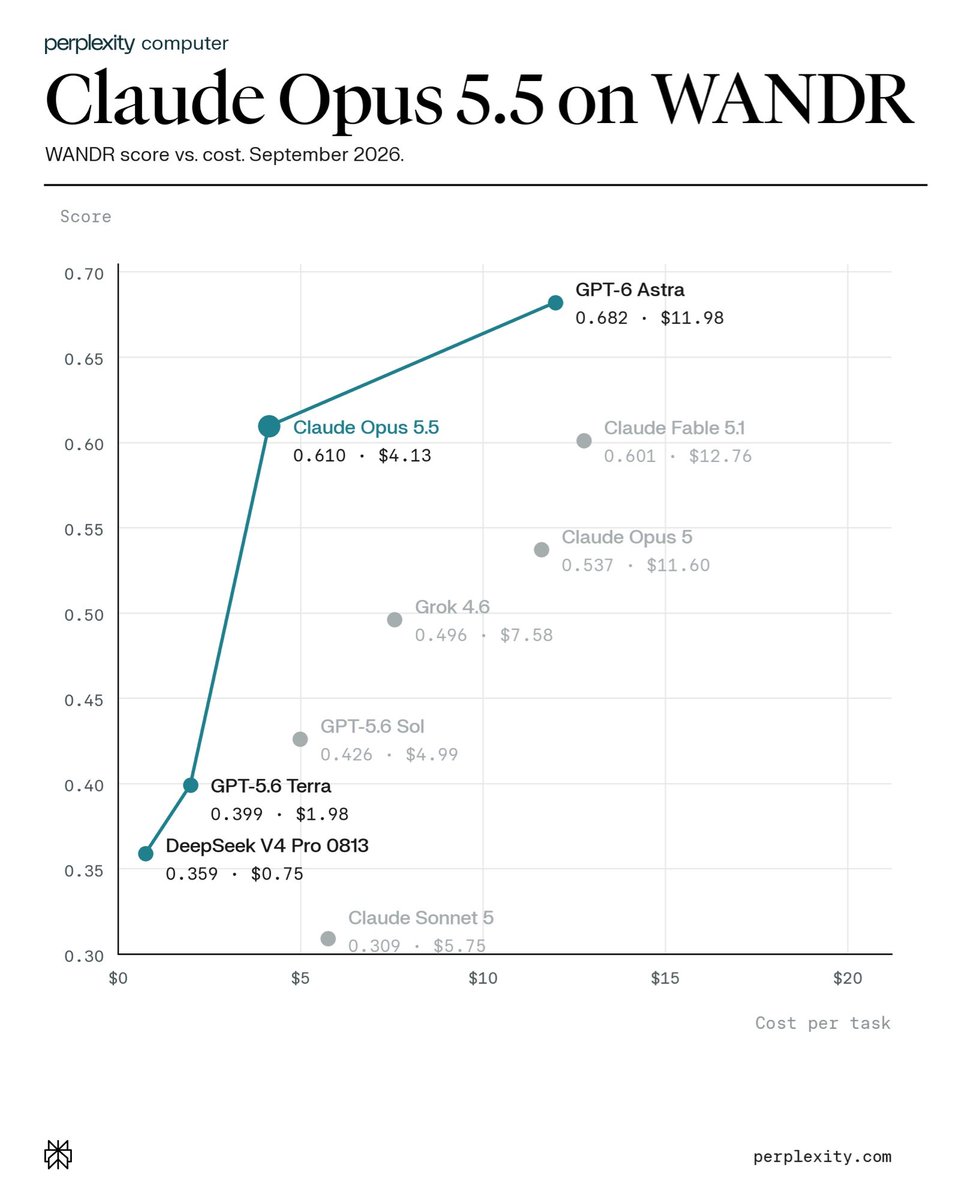
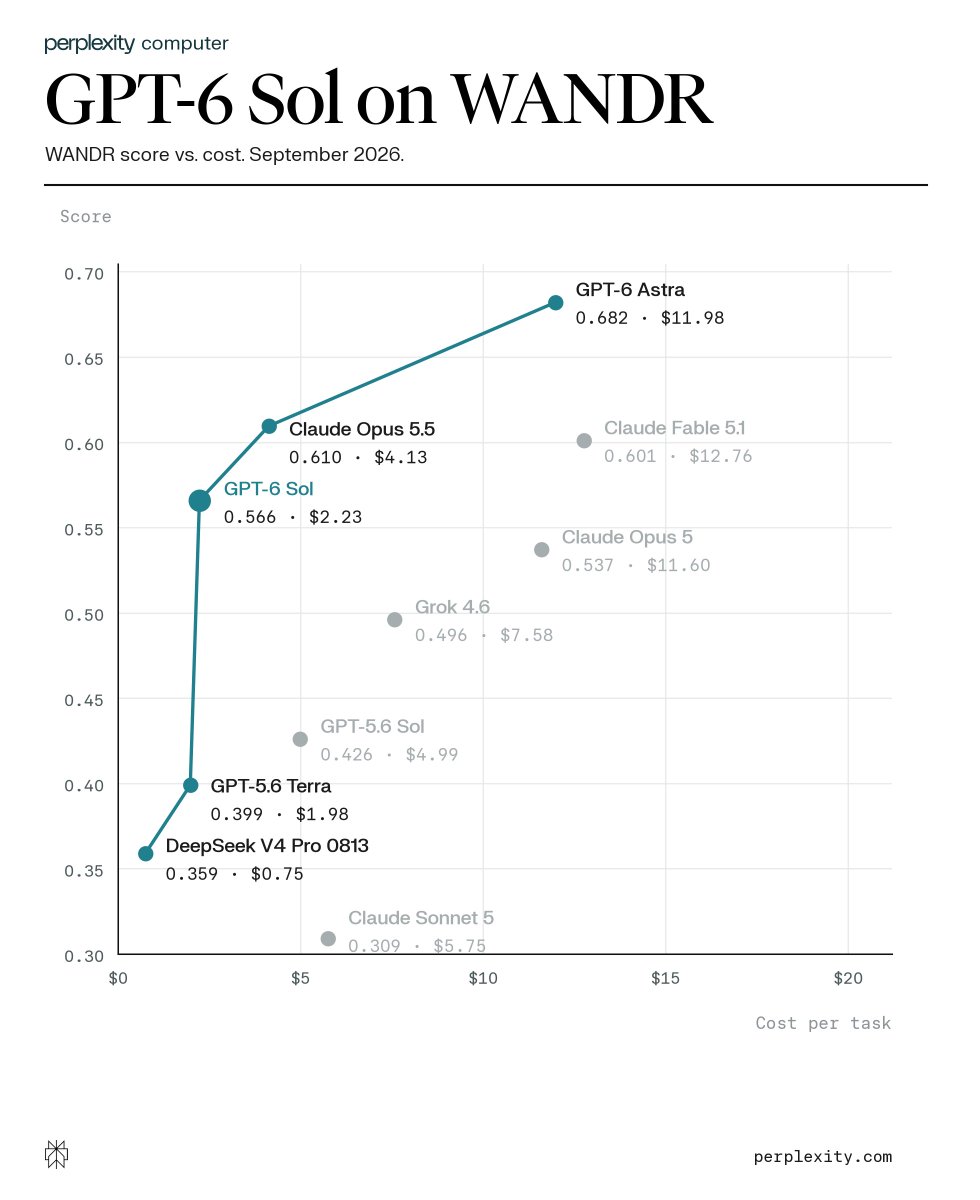
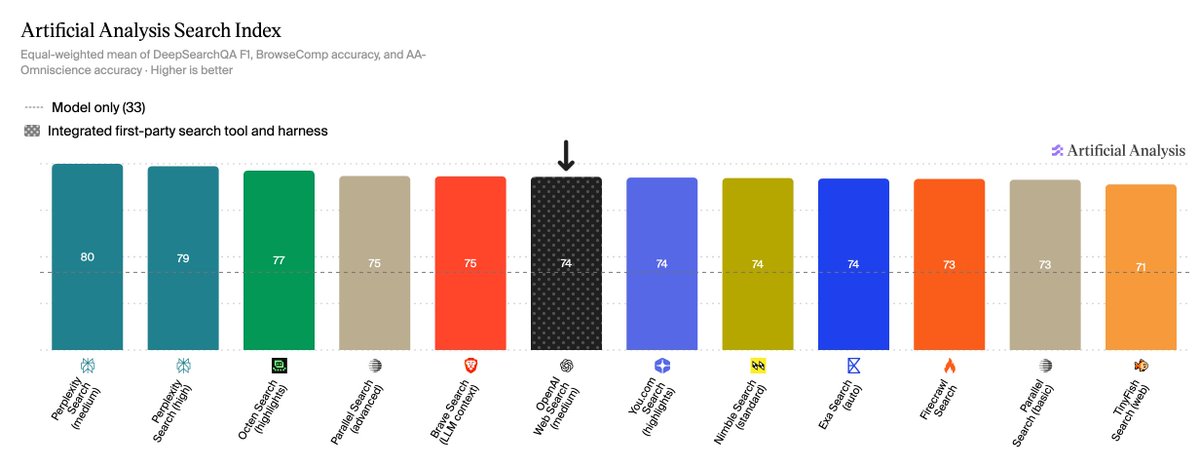
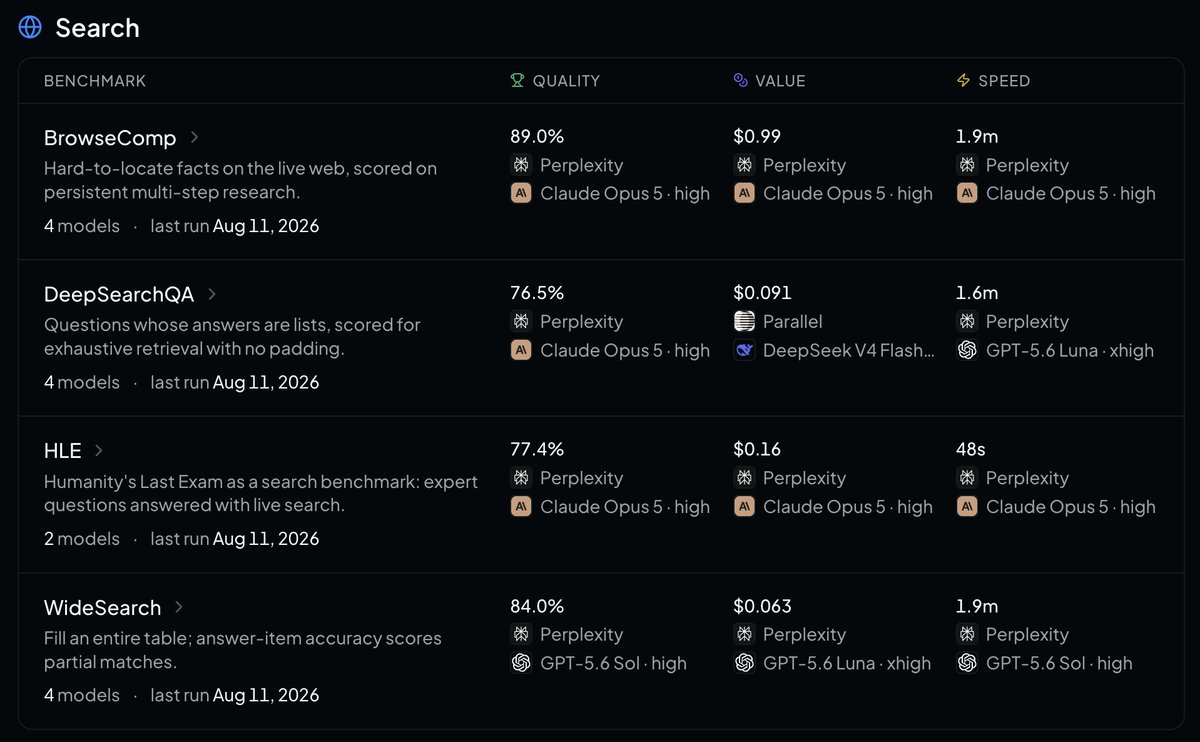
We tested Search as Code on deep research (DSQA, BrowseComp, HLE) and wide research benchmarks (WideSearch, WANDR). It matches or beats every competing system across all five.
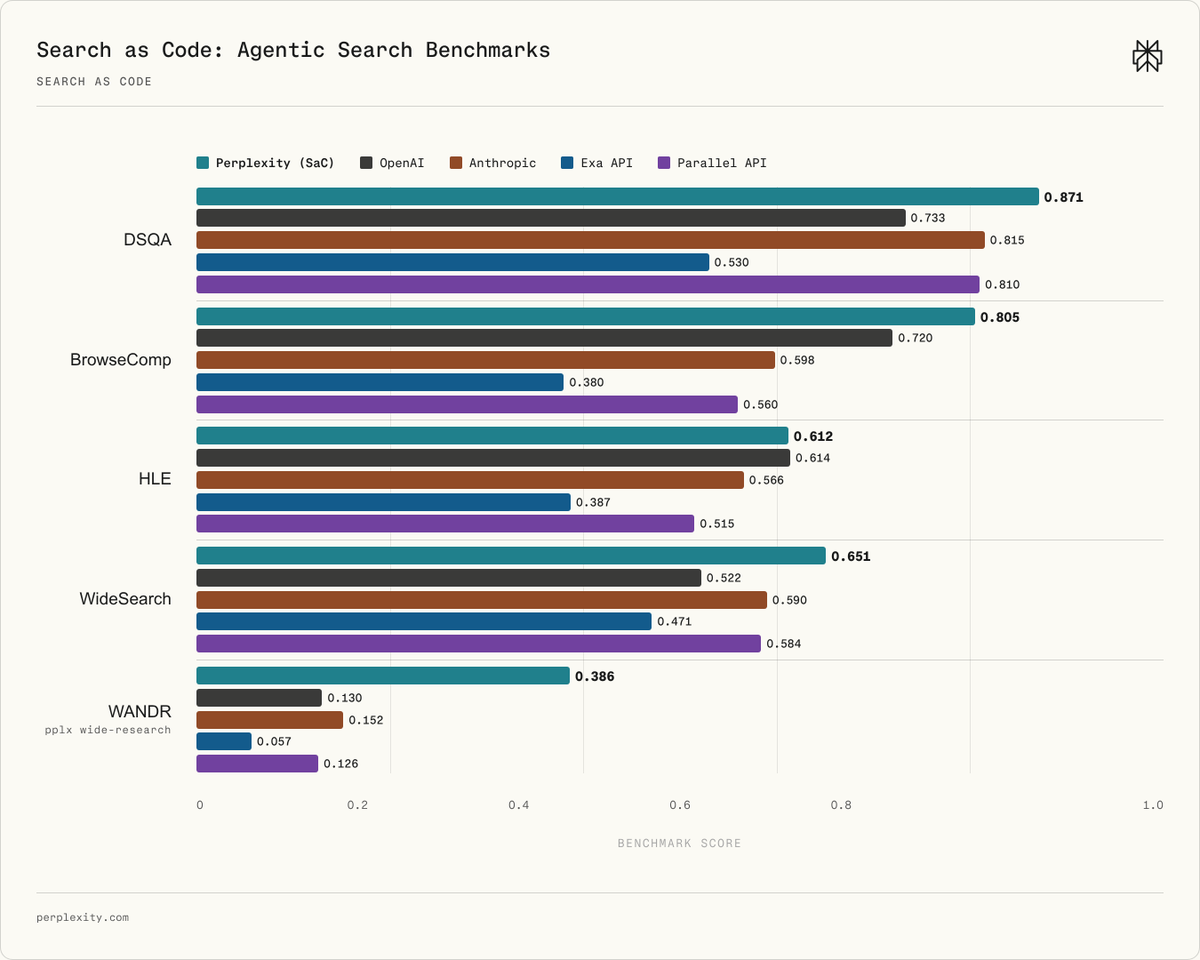
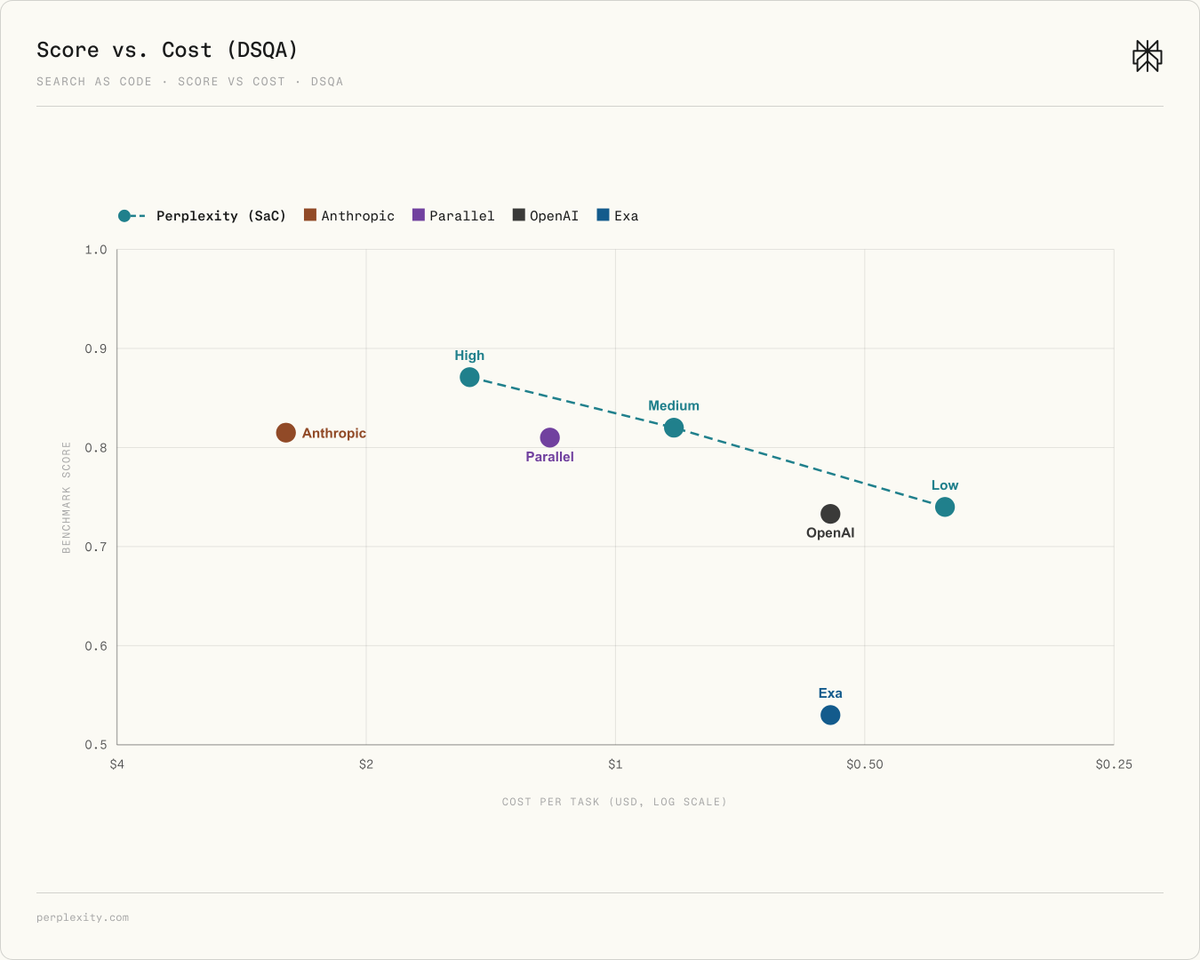
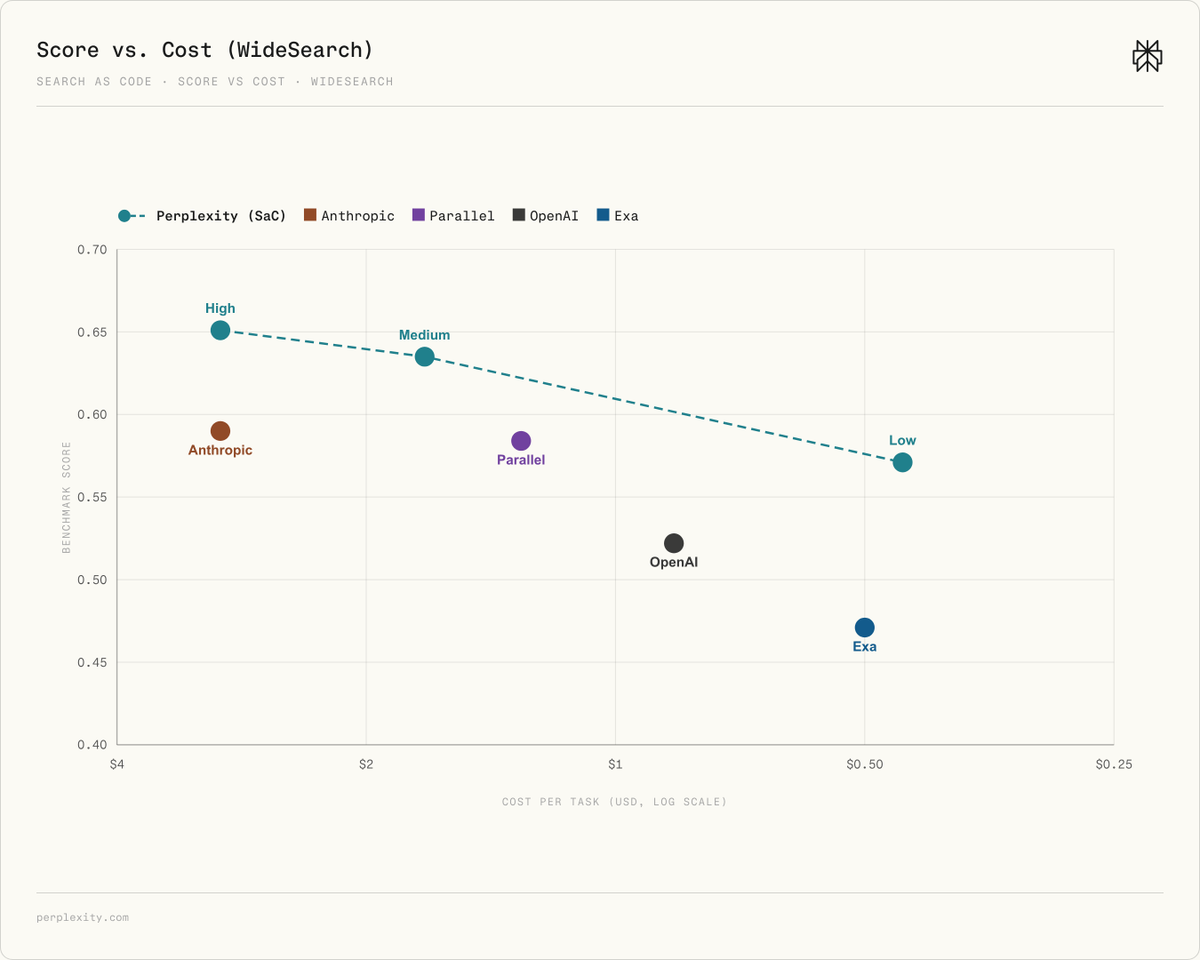
It also sets a new cost-performance frontier. On DSQA it scores 0.871, ahead of Anthropic's 0.815, at nearly half the cost per task. On WideSearch it leads on score while running cheaper.
Context
Perplexity's Search as Code lets an write a small Python program that controls how information is retrieved and prepared. The program can run searches concurrently and remove duplicate results before passing selected material back to the model. Intermediate processing happens in code, so the model need not read every result from every individual search. This gives the agent control over the retrieval process as well as the final answer. The architecture article explains the search library and execution environment that make this possible.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- tool use — A model's ability to call external functions — run code, search the web, edit files — instead of only generating text.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
Checking sign-in…
Loading comments…