Scaling Ai Ml Infrastructure At Uber
- Source
- uber.com
- Author
- Uber Engineering 1
- Date
Context
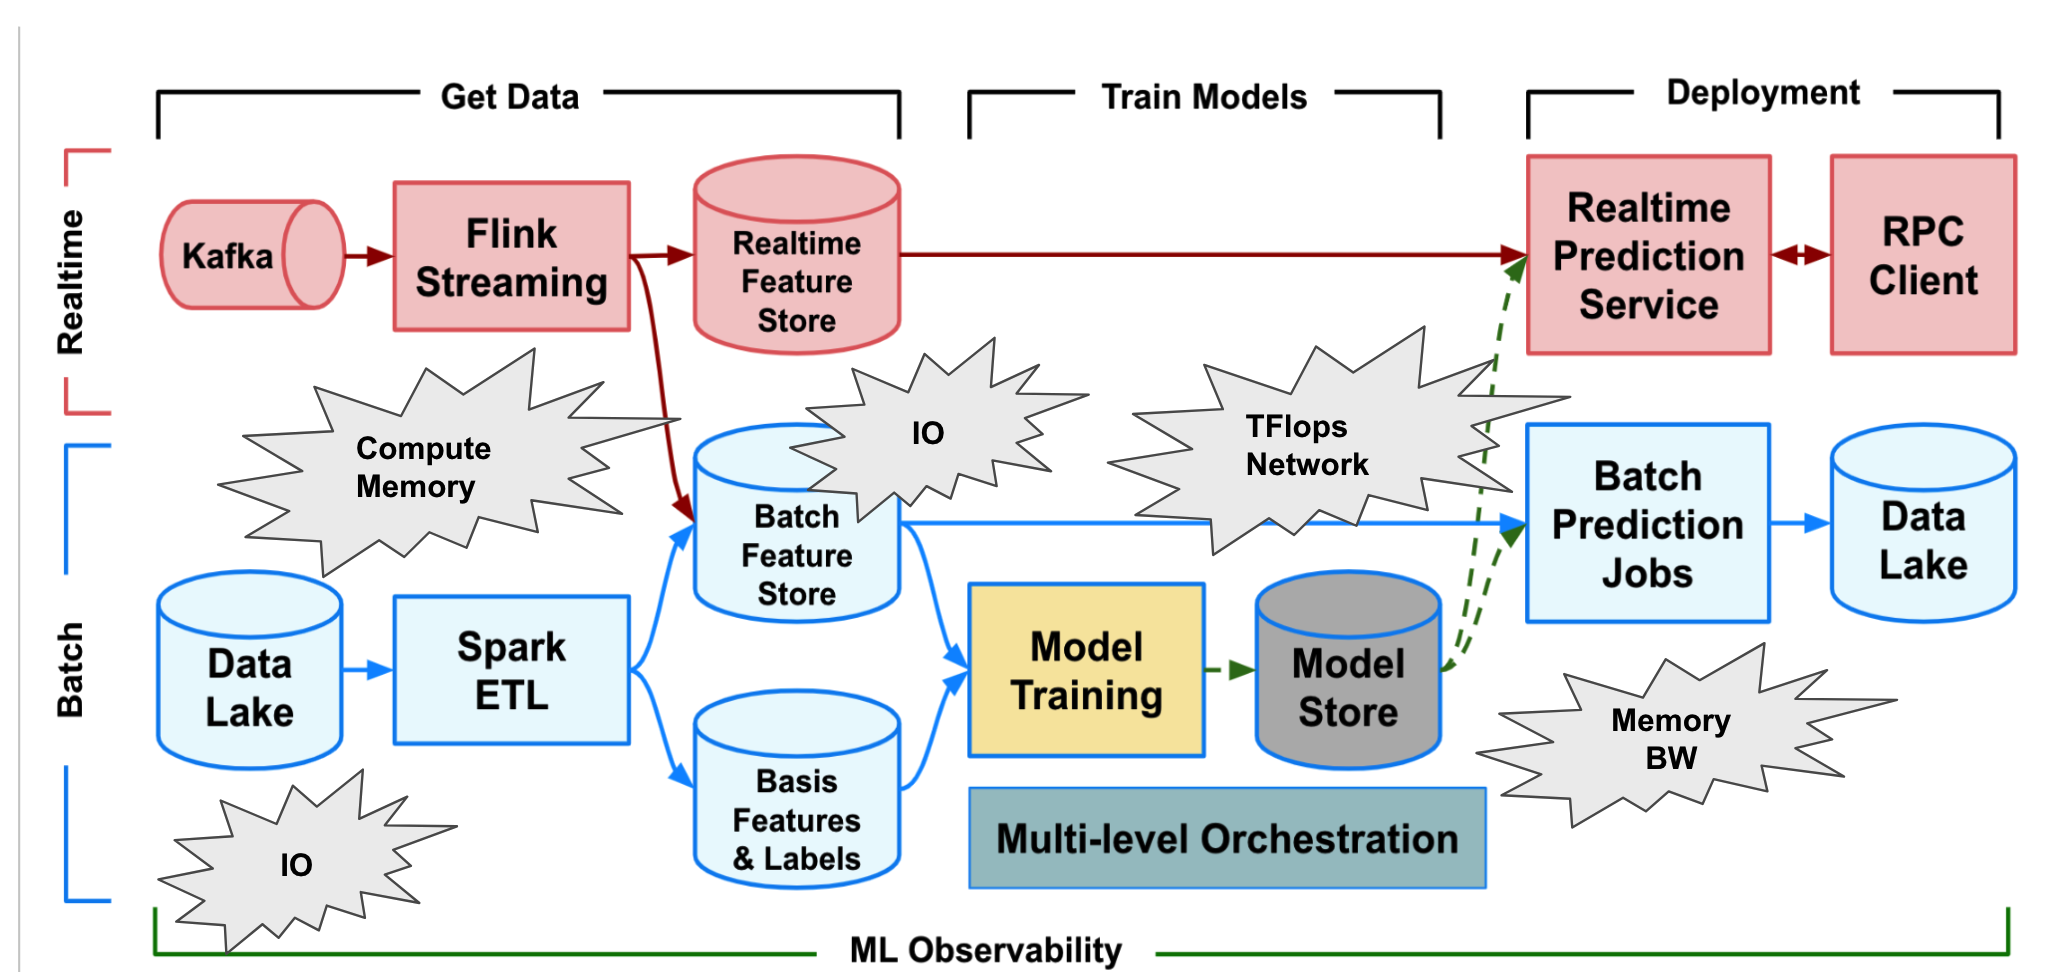
Training a large model across several GPU servers makes the network part of the computing system, because the servers must exchange data constantly. In an infrastructure overview, Uber Engineering reports that a large-language-model case study showed nearly twofold faster training with higher network bandwidth and better congestion control than its existing interconnect. It recommends raising each GPU server's link capacity fourfold, from 25GB/s to 100GB/s, which it says could potentially double the available training capacity.
The same section adds that the very large data flows produced by training runs must be isolated, with quality-of-service controls, so they do not harm other high-priority services. Uber's account presents the speedup as one case-study finding and a capacity recommendation, so it supports the point that network capacity can limit distributed training, not a fleet-wide result.
Checking sign-in…
Loading comments…