Rise Of Realtime Subagents
- Source
- inceptionlabs.ai
- Author
- Inception
- Date
Context
A coding assistant can spend substantial time summarizing its own history when a session grows too long. Inception describes assigning that job to Mercury 2, a diffusion-based : a separate model compresses the conversation into decisions, relevant files, unresolved issues and next steps that the main assistant can continue using.
In the company's customer account, Augment Code engineers say that moving summarization from the user's primary model (they name Opus 4.7) to Mercury 2 cut summarization latency by 82%, down from about 150 seconds, and cost by 90%. This is one customer's reported experience. It illustrates why a supporting task can be given its own model, without showing that the same change suits every coding product.
- LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
- context compaction — Summarizing an agent's earlier conversation to free room in the context window so a long session can keep going.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
 postInception ships Mercury Decide update with ZDR and 66k context
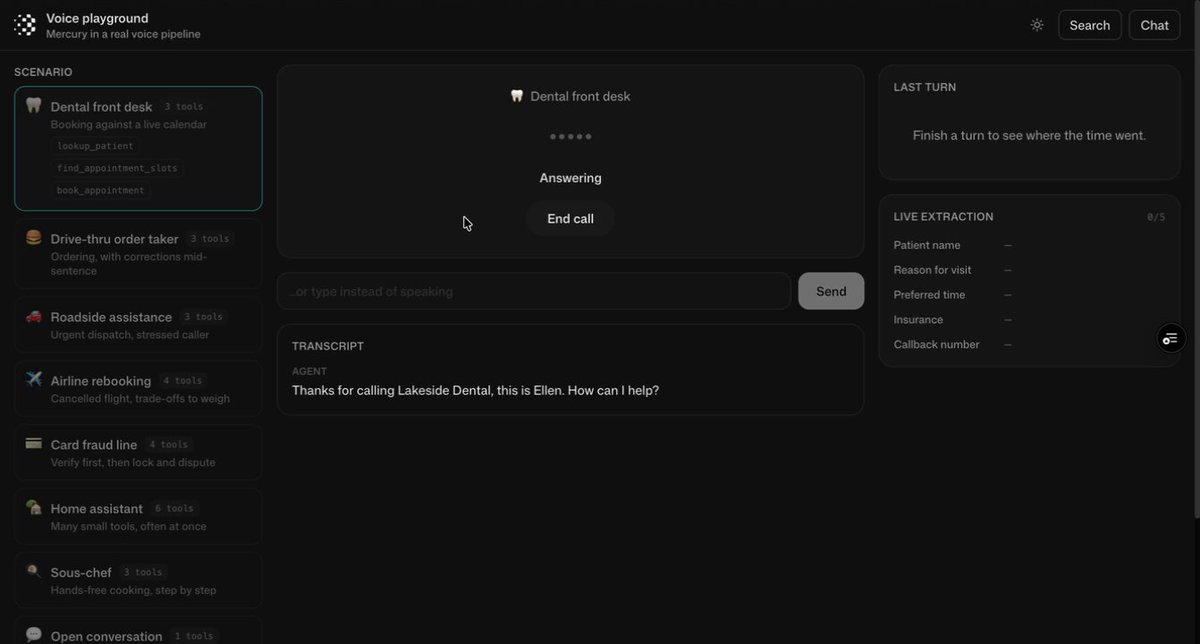 postInception launches Mercury Voice, a diffusion LLM for low-latency voice agents
 postToday, we’re introducing Mercury 2.5, the most capable diffusion LLM on the…
 postInception ships Mercury 2.5 Preview at roughly 1,100 tokens per second
Checking sign-in…
Loading comments…