Inception launches Mercury Voice, a diffusion LLM for voice agents
- Source
- x.com
- Date

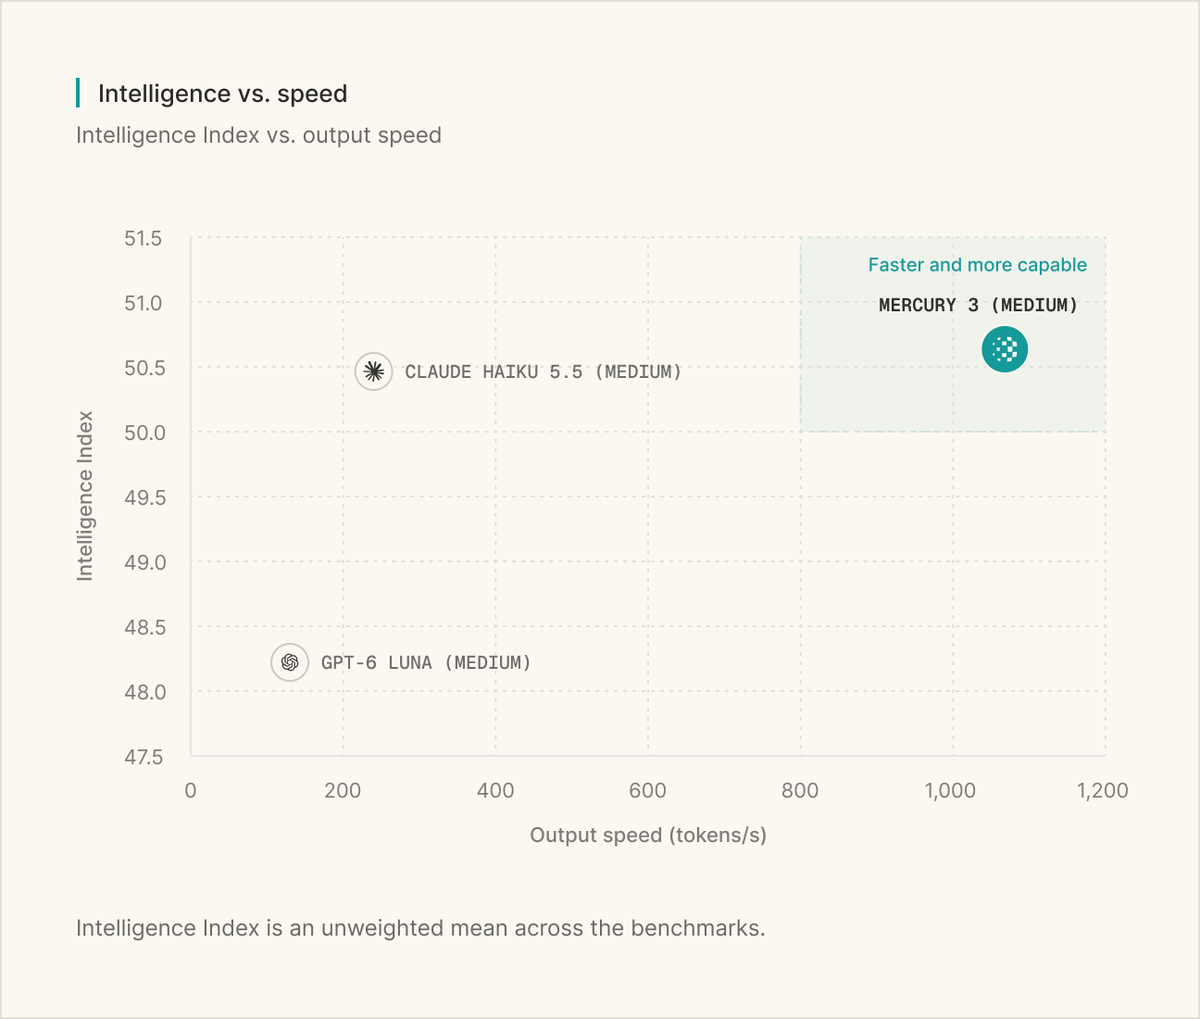
This week we launched Mercury Voice, a dLLM optimized for voice agents with 2x+ lower latency than models like GPT-6 Luna. In this dental clinic receptionist demo, median end-to-end latency stays under 300ms, tool calls included. See (or hear?) it yourself in the model playground: https://t.co/NaT8trzyD4 Enterprise customers interested in Mercury Voice can contact us at sales@inceptionlabs.ai to get access.

Context
Mercury Voice is a diffusion from Inception tuned for voice agents, where the pause before a spoken reply is the delay a caller notices most. Inception's launch post makes two speed claims: latency more than two times lower than models like GPT-6 Luna, and a median end-to-end latency under 300 milliseconds in a dental-clinic receptionist demo, with tool calls included. A median describes the typical response in that demo, not the slowest ones.
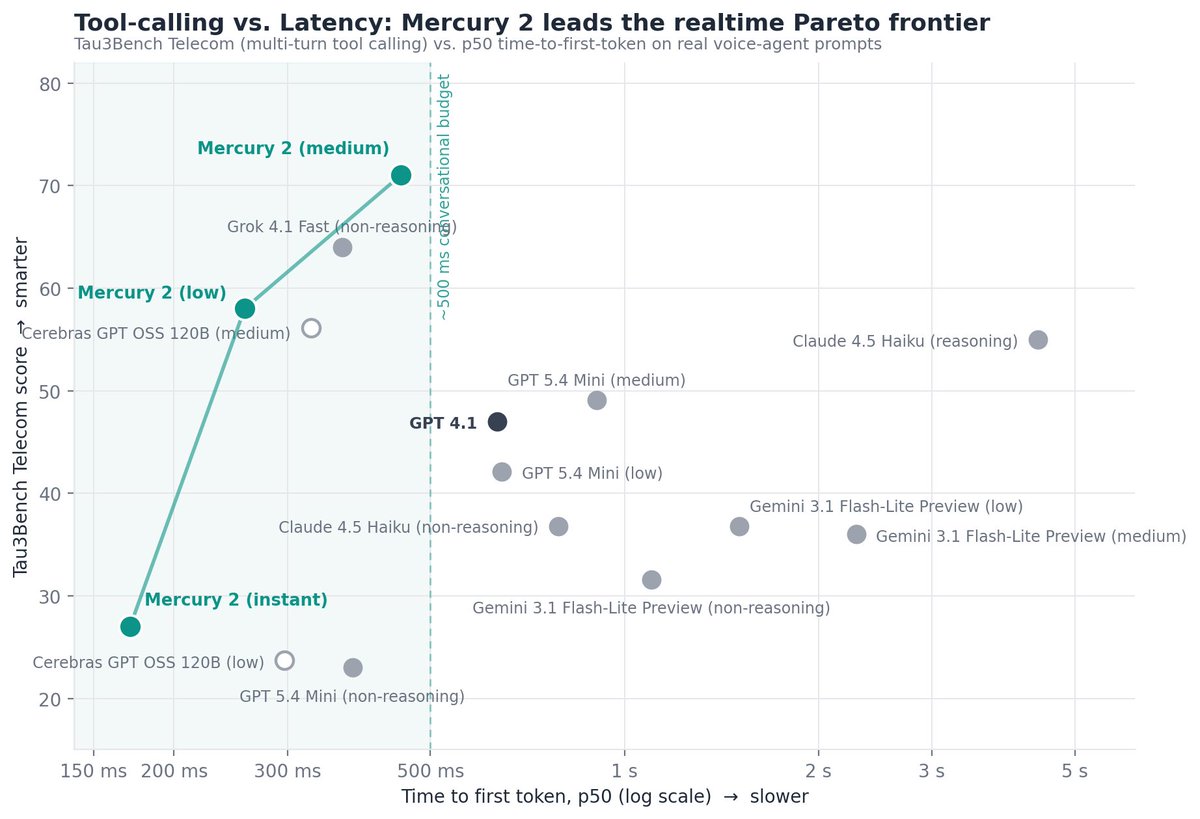
Inception's launch article, also collected as separate Intel, measures something different: time to first answer , meaning how long until the model starts producing the words the caller hears. On a test set of real customer-service prompts it reports 320 milliseconds at the median and 750 at the 95th percentile, and calls the model 5.9 times faster than GPT-6 Luna without reasoning. The post's and the article's figures therefore come from different tests and metrics, and neither source explains how the twofold and 5.9-fold comparisons were measured.
A speech transcript of the demo video shows the answering questions, catching an impossible date of November 31 and booking two matching appointments, but the transcript records no timings, and the video's visuals and the playground page were not reviewed, so the demo's latency was not independently checked. The article says the model is available to enterprise customers through Inception's API.
- LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
Checking sign-in…
Loading comments…