Introducing Limite 1B - Violetto.
A model for high-frequency mathematical intelligence.
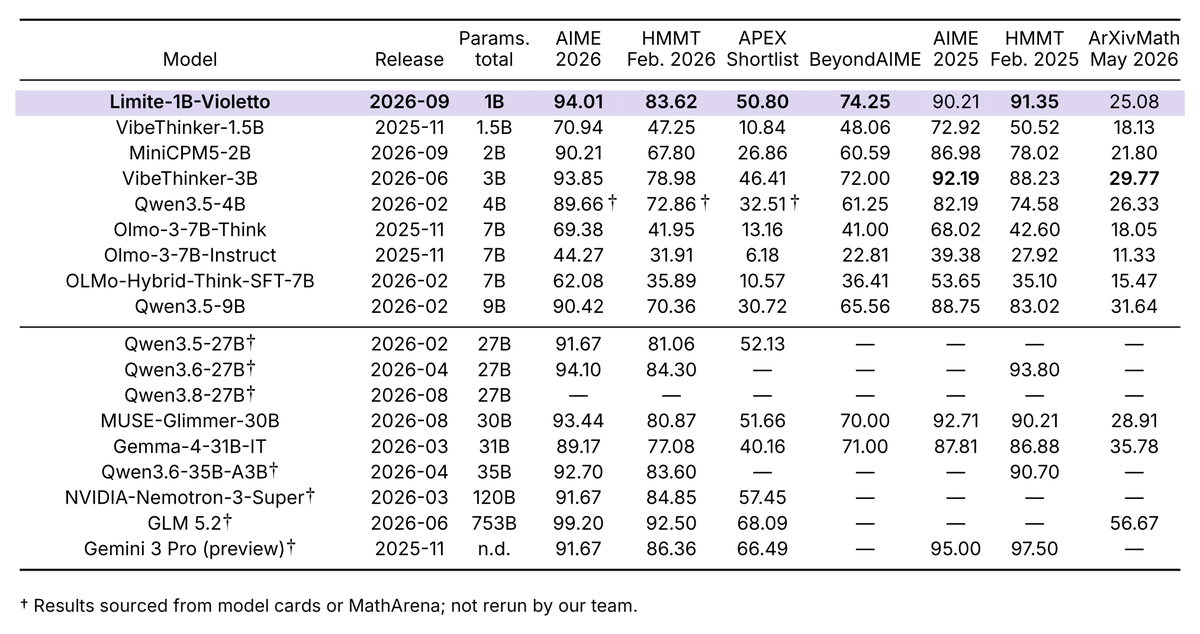
Despite its size, Limite can solve hard math problems better than models tens of times larger, and is competitive when compared to recent models with hundreds of billions of parameters.
Limite has been trained from scratch on less than 300B tokens, almost fully on math, and leverages an architecture inspired by recent advancements brought forth by the nanogpt speedrun competitions.
When comparing capability per training FLOPs, Limite is orders of magnitude more efficient than existing models.
Paradigma says Limite 1B was trained from scratch on under 300B tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition →, almost all math, using an architecture inspired by NanoGPT speedrun work, and claims it is orders of magnitude more efficient per training FLOP than existing models.
Limite is deliberately lightly instruction-tuned, to test the assumption that models need an assistant persona to work well, so it is designed for single-turn responses rather than chat.
The Apache 2.0 release includes Limite's base model and the value model used late in post-training, with a 59.80% few-shot MATH-500 score cited in the announcement. A technical report and a multi-agent harnessThe scaffolding around a model that turns it into a working agent — the loop, the tools it can call, and the rules for when to stop.Full definition → called Rainfall are promised but not yet out.
Paradigma says Limite is its first model, trained within six weeks of its first experiments in early August. Its comparisons against much larger models await the promised technical report.
Terms in this piece · Glossary
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
multi-agent — Using several AI agents on one problem — splitting work in parallel, checking each other, or filling different roles like planner and reviewer.
agent harness — The scaffolding around a model that turns it into a working agent — the loop, the tools it can call, and the rules for when to stop.
Why it matters
Paradigma released Limite 1B under Apache 2.0, a math-specialized model claimed to beat much larger models on hard math while trained on far fewer tokens, positioned as a fast solver component for multi-agentUsing several AI agents on one problem — splitting work in parallel, checking each other, or filling different roles like planner and reviewer.Full definition → systems.
 Read the full thread on X