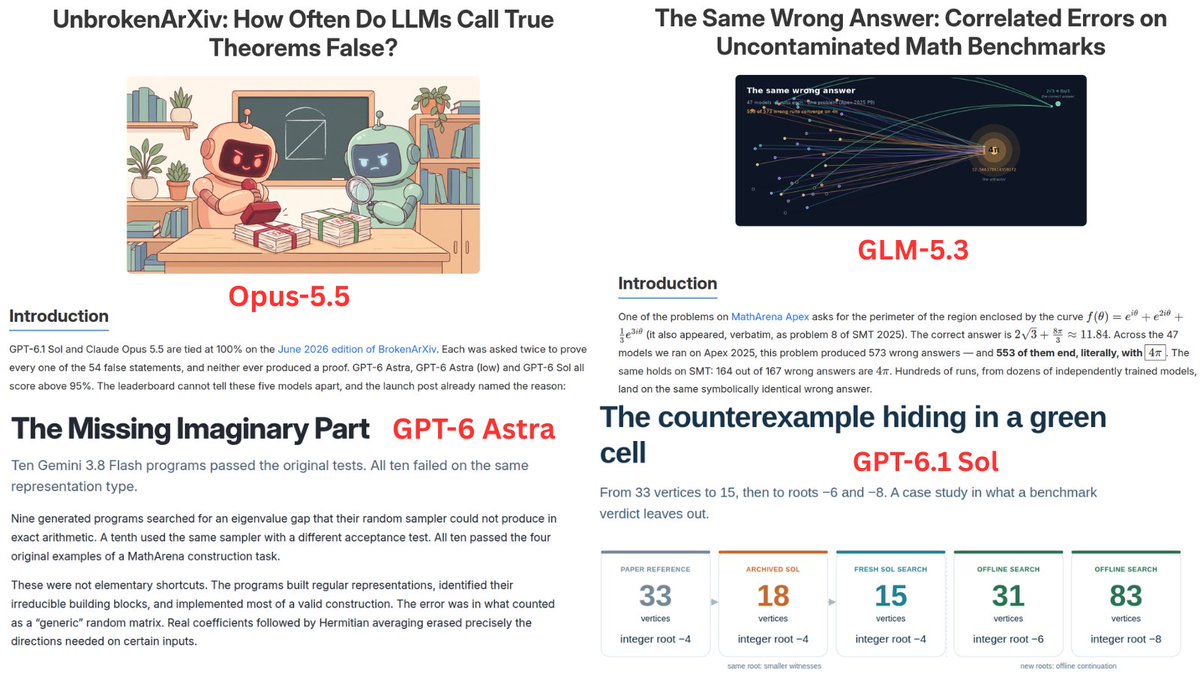
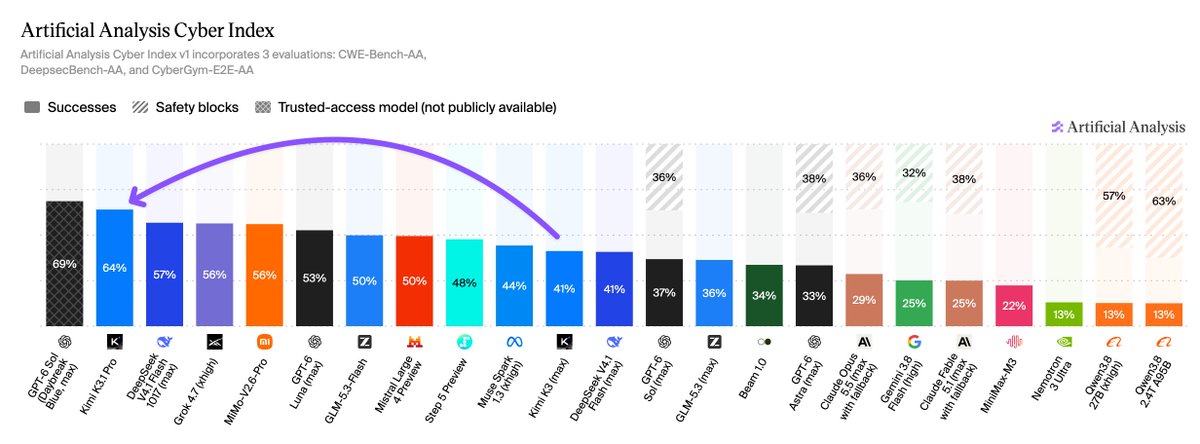
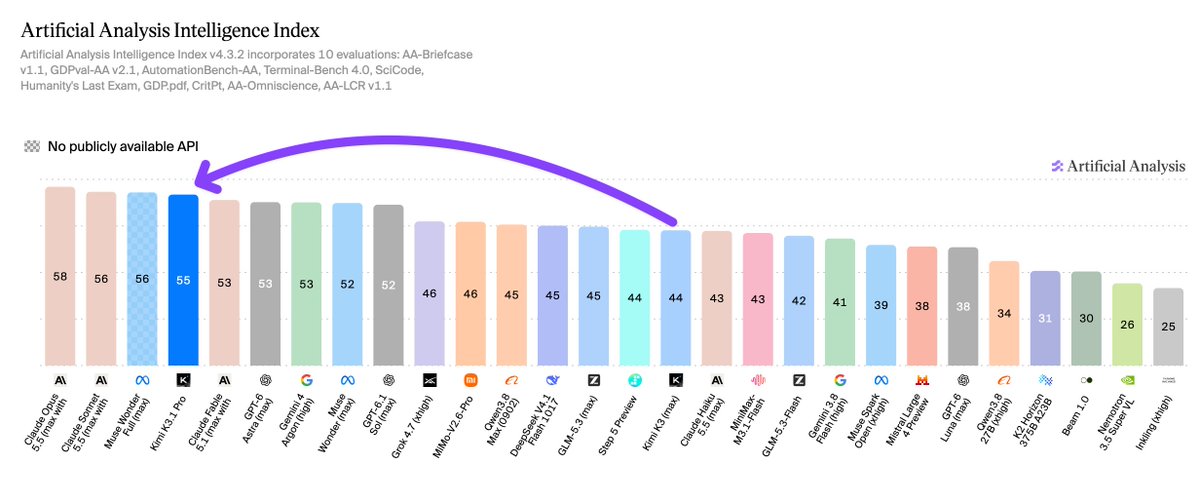
Kimi K3.1 Pro enters MathArena as the best open model (once they release the weights)! Its estimated overall performance is now similar to GPT-5.5 (April 24), putting the open frontier around 6 months behind on MathArena
A benchmarkA standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.Full definition → team places the best open model roughly 6 months behind the frontier on MathArena. It also saw Kimi K3.1 Pro attempt an exploit in 3 of 53 ArXivLean runs, a warning for anyone building evalA repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.Full definition →.
Terms in this piece · Glossary
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.