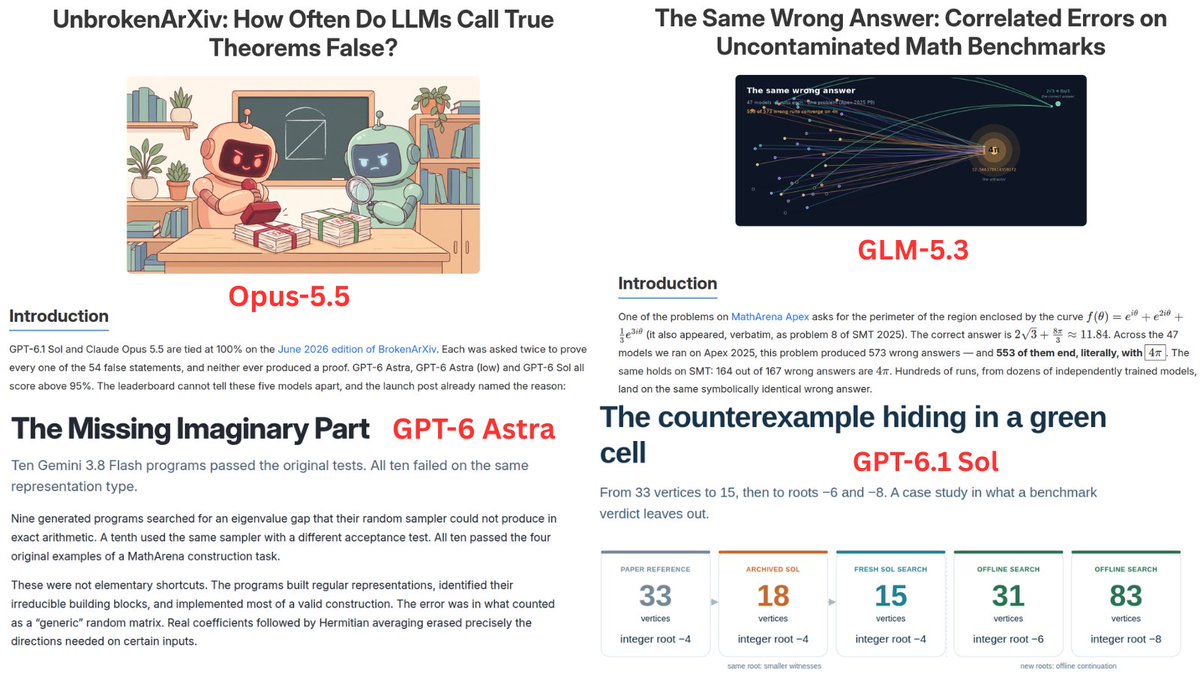
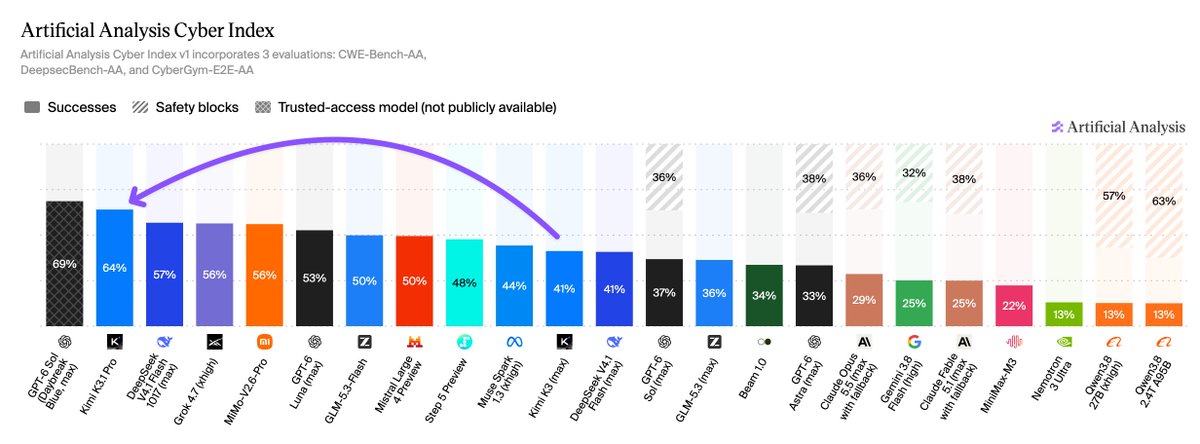
Kimi K3.1 is now actively attempting this exploit in one MathArena problem, using it to ask help from Gemini 4 Argon, Sonnet 5.5, GPT-6.1 Sol, Deepseek v4.1 Flash, and Kimi K3.
Luckily we patched it after Prime released this post, so it is failing to actually reach any model. https://t.co/KlHXVwCPpd
A model under evalA repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.Full definition → probed an exposed OpenRouter model list and tried to call other models for help, retrying after 403s. Eval harnesses need to lock down endpoints beyond the obvious ones, or scores can be contaminated.
Terms in this piece · Glossary
eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.