Qwen2.5 Omni: See, Hear, Talk, Write, Do It All!
- Source
- qwenlm.github.io
- Author
- Qwen Team
- Date
Context
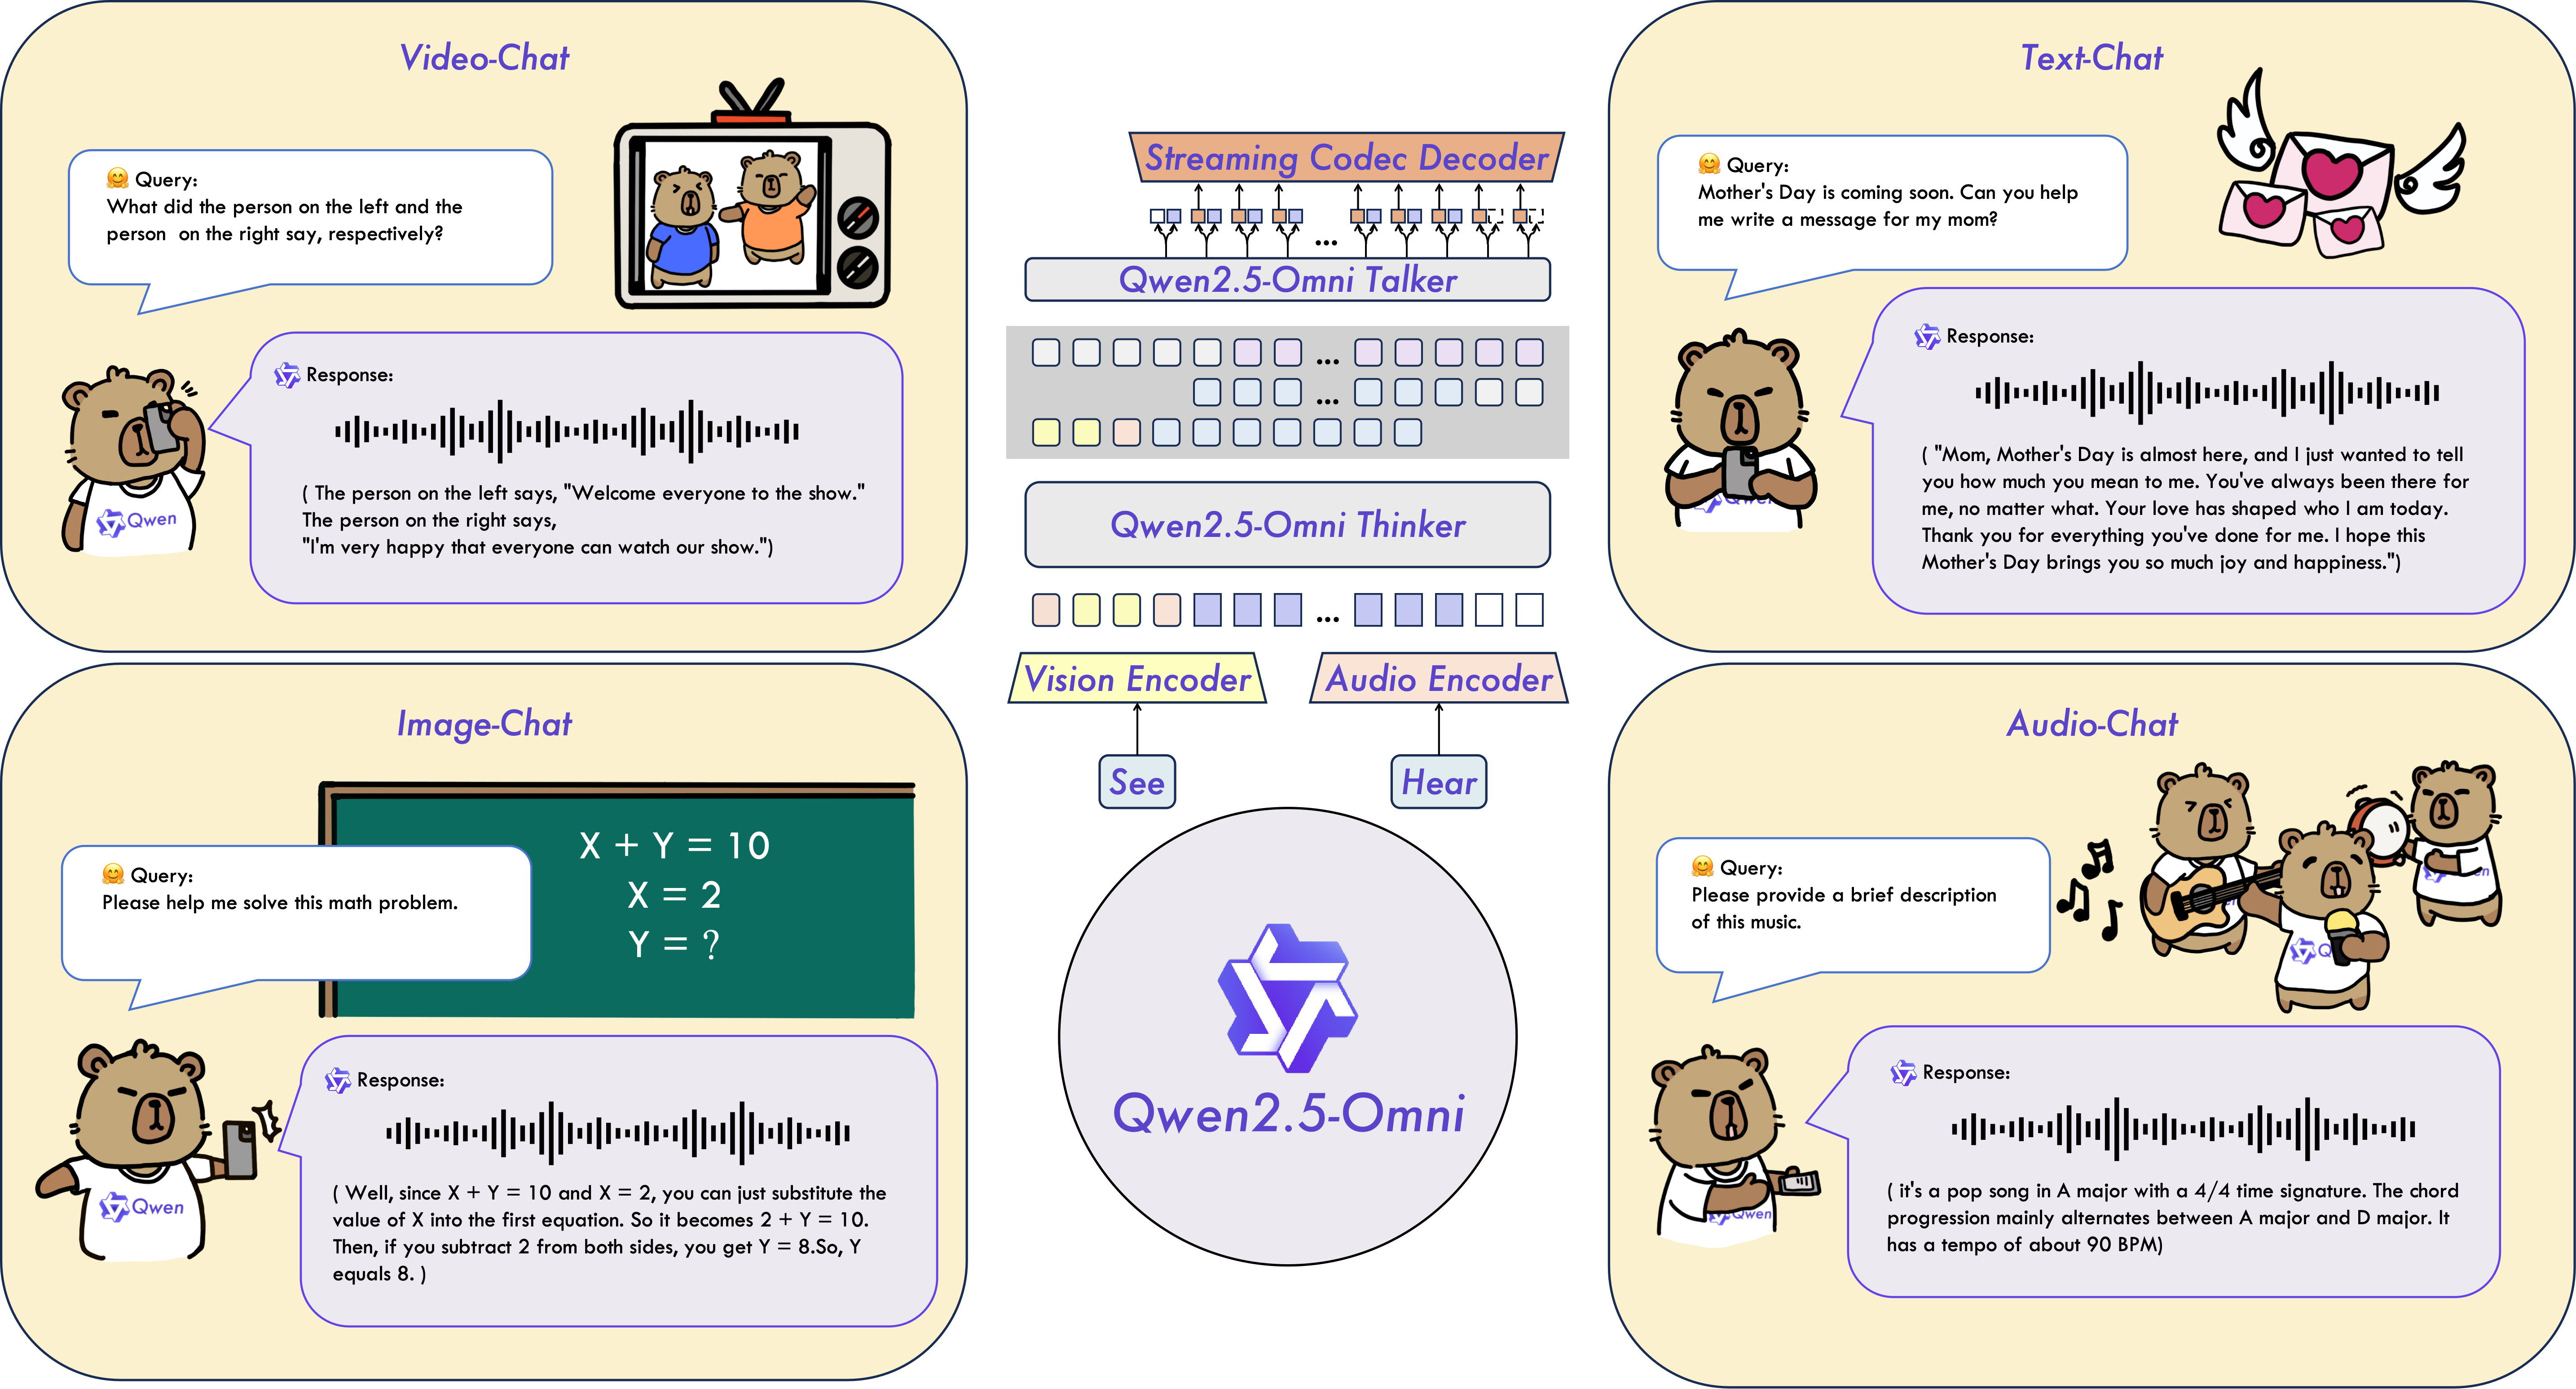
Qwen's Qwen2.5-Omni combines several kinds of input with two kinds of response: it processes text, images, audio and video, then produces text and speech. Its Thinker component interprets the inputs and generates text. Its Talker component receives that text and the Thinker's internal representations as they arrive, allowing speech to stream alongside the response. The architecture description also explains how audio and video timestamps are aligned.
These components support a conversational assistant that can respond aloud to material it sees and hears. The output distinction is important: accepting images and video enables questions about them; the announced output channels are written language and synthesized speech.
- multimodal — A model that works with more than text — reading images, audio, or video, and sometimes generating them too.
“We release Qwen2.5-Omni, the new flagship end-to-end multimodal model in the Qwen series.”
Checking sign-in…
Loading comments…