Can Frontier Models See Past a Decoy? Elorian Tests Visual Reasoning
Source
latent.space
Author
Richard MacManus
Date
Why it matters
Frontier vision models score below 50% on a counting benchmarkA standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.Full definition → built with decoys, showing that stronger general reasoning does not guarantee reliable visual counting. Check this before trusting a model for perception tasks.
Key takeaways · AI-distilled
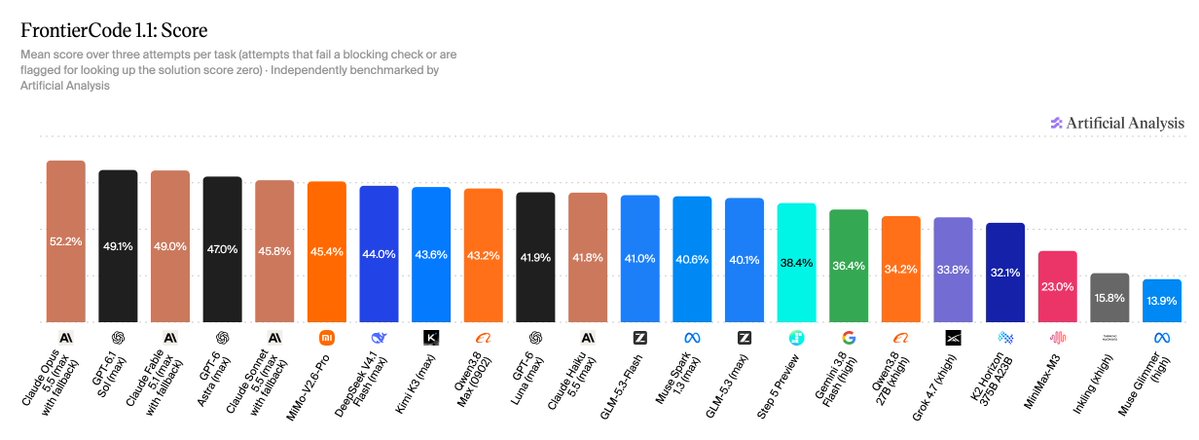
DecoyCount, co-released by Elorian with Mercor, tests whether models really count objects or lean on visual shortcuts, across 1,660 items and seven failure mechanisms. In the paper no frontier model passed 50%; GPT-6 Astra led at 43.17% and Claude Fable 5.1 scored 25.22%.
Elorian CEO Andrew Dai says its Glimpse model scored 50.48%, but that figure is not in the paper: it is a single internal run without an agent harnessThe scaffolding around a model that turns it into a working agent — the loop, the tools it can call, and the rules for when to stop.Full definition →, while the paper's six models were averaged over three runs. Dai says the evalA repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.Full definition → items were withheld from training.
Dai argues most counting benchmarks check only the final number, so missing an object (a vision error) and counting its reflection as a second object (a reasoning error) look the same, which makes the root cause hard to fix.
Elorian's approach, which it calls visual thinking, has the model generate and edit images inside its reasoning trace alongside text, for example mentally crossing people off one by one while counting, rather than treating image generation only as output.
Dai separates this from world models like World Labs' Atlas or Genie 4: those enable direct action in a simulated world, while Elorian targets indirect action, using visual reasoning to inform a decision such as whether a user video breaks a policy.
Terms in this piece · Glossary
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
agent harness — The scaffolding around a model that turns it into a working agent — the loop, the tools it can call, and the rules for when to stop.
eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
 articleCrossing the Threshold: How OpenAI and Anthropic Approach Autonomy and Safety in Financial Agents
 articleHow Anthropic’s Dynamic Workflows Coordinate Claude Agents
 articleCan a Cloud-Native Harness Make Agents Reliable Beyond the Desktop?
 articleInside-Out AI: Rebuilding Airbnb Behind the Scenes and Across the Guest Experience