(Claude、GPT、GLM)
GLM-5.2 Tops Artificial Analysis as the #1 Open-Source Model, Ranking Top 3 Globally
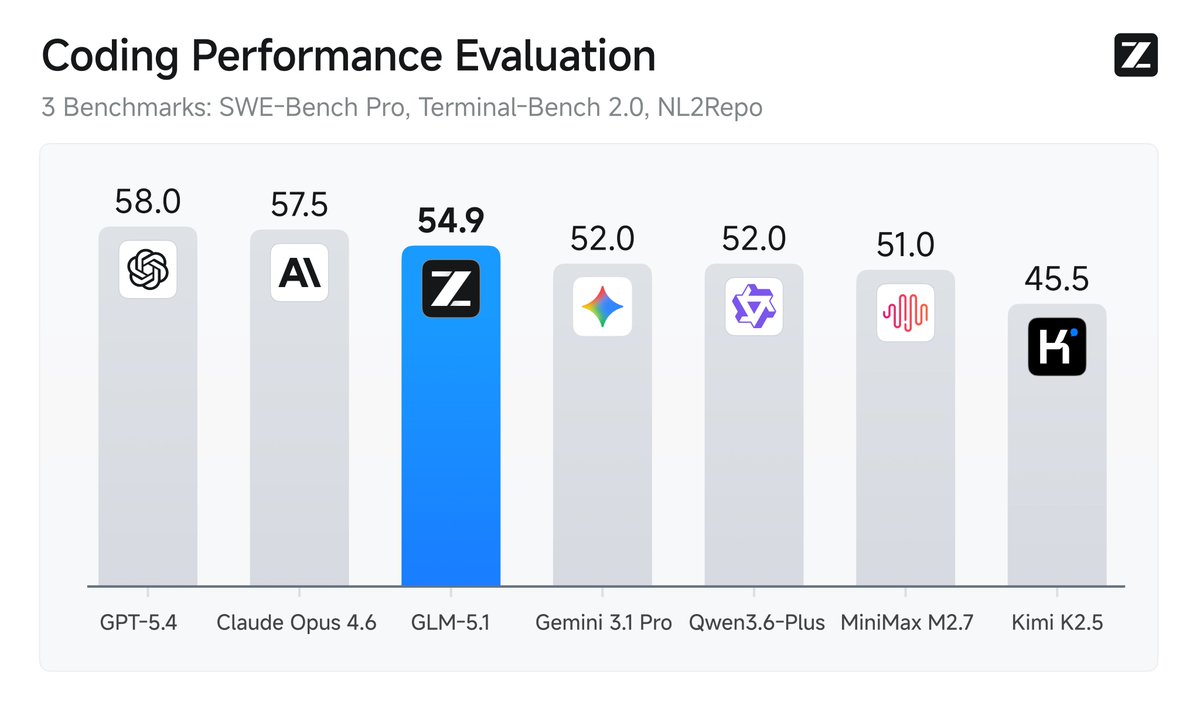
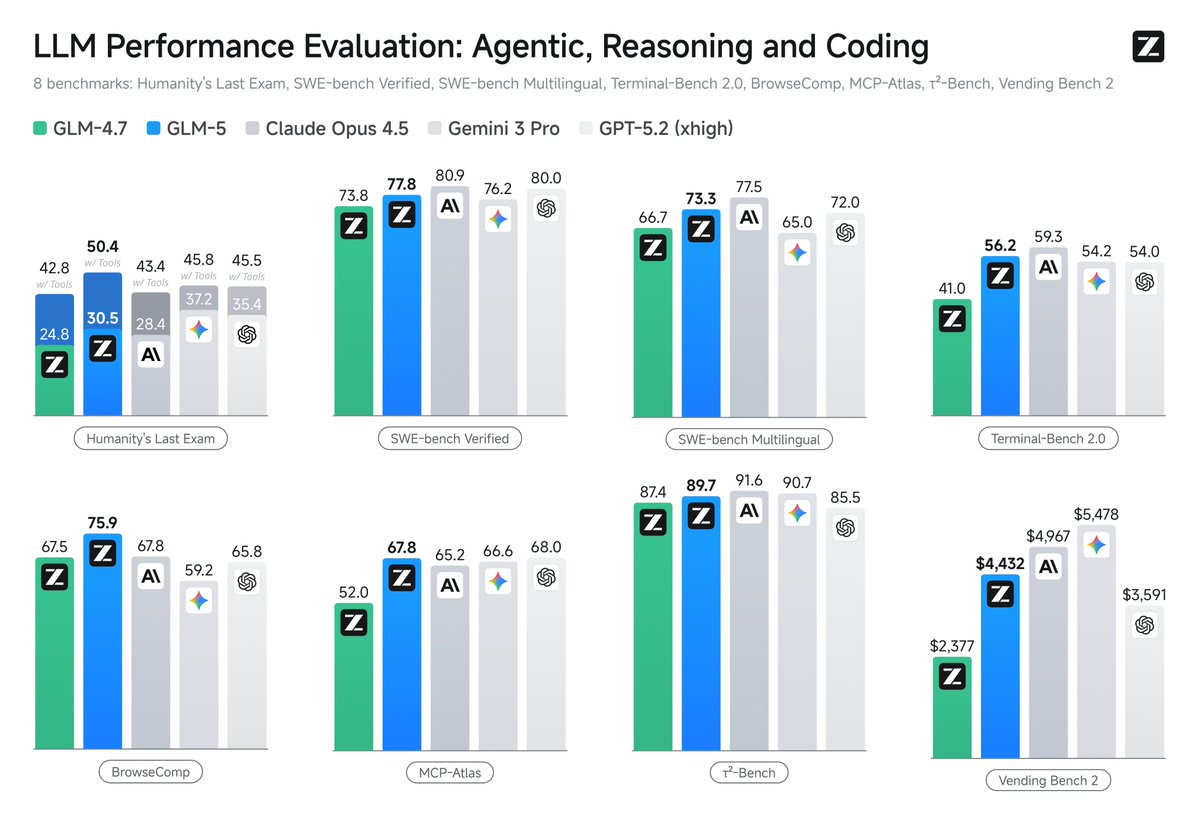
GLM-5.2 launched and went open-source today, delivering a solid scorecard across multiple authoritative third-party benchmarks and arenas.
📊 Artificial Analysis Intelligence Index
A comprehensive evaluation that integrates several authoritative leaderboards spanning coding, reasoning, long context, and more. GLM-5.2 scored 51, ranking among the top of all available models—on par with Claude Opus 4.8—and claiming the #1 spot among open-source models worldwide.
🎨 Code Arena
A real-world head-to-head arena focused on front-end code generation, with Elo rankings produced by blind user voting. GLM-5.2 ranked #2 globally with a score of 1,595.
🏆 DesignArena
A category arena centered on scenarios that combine design and code. GLM-5.2 took the top spot with a score of 1,360.
⚙️ FrontierSWE
A software-engineering benchmark built around the "frontier of human capability," assessing engineering ability across three dimensions: implementation, performance, and research. GLM-5.2 ranked #3 overall.
💪 From front-end development and design-to-code to engineering-grade software tasks,…
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
Why it matters
GLM-5.2 scores 51 on the Artificial Analysis Intelligence Index (matching Claude Opus 4.8) and takes #1 among open models, plus top-3 placements on Code Arena, DesignArena, and the FrontierSWE engineering benchmarkA standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.Full definition →.

 Read the full post on X ↗