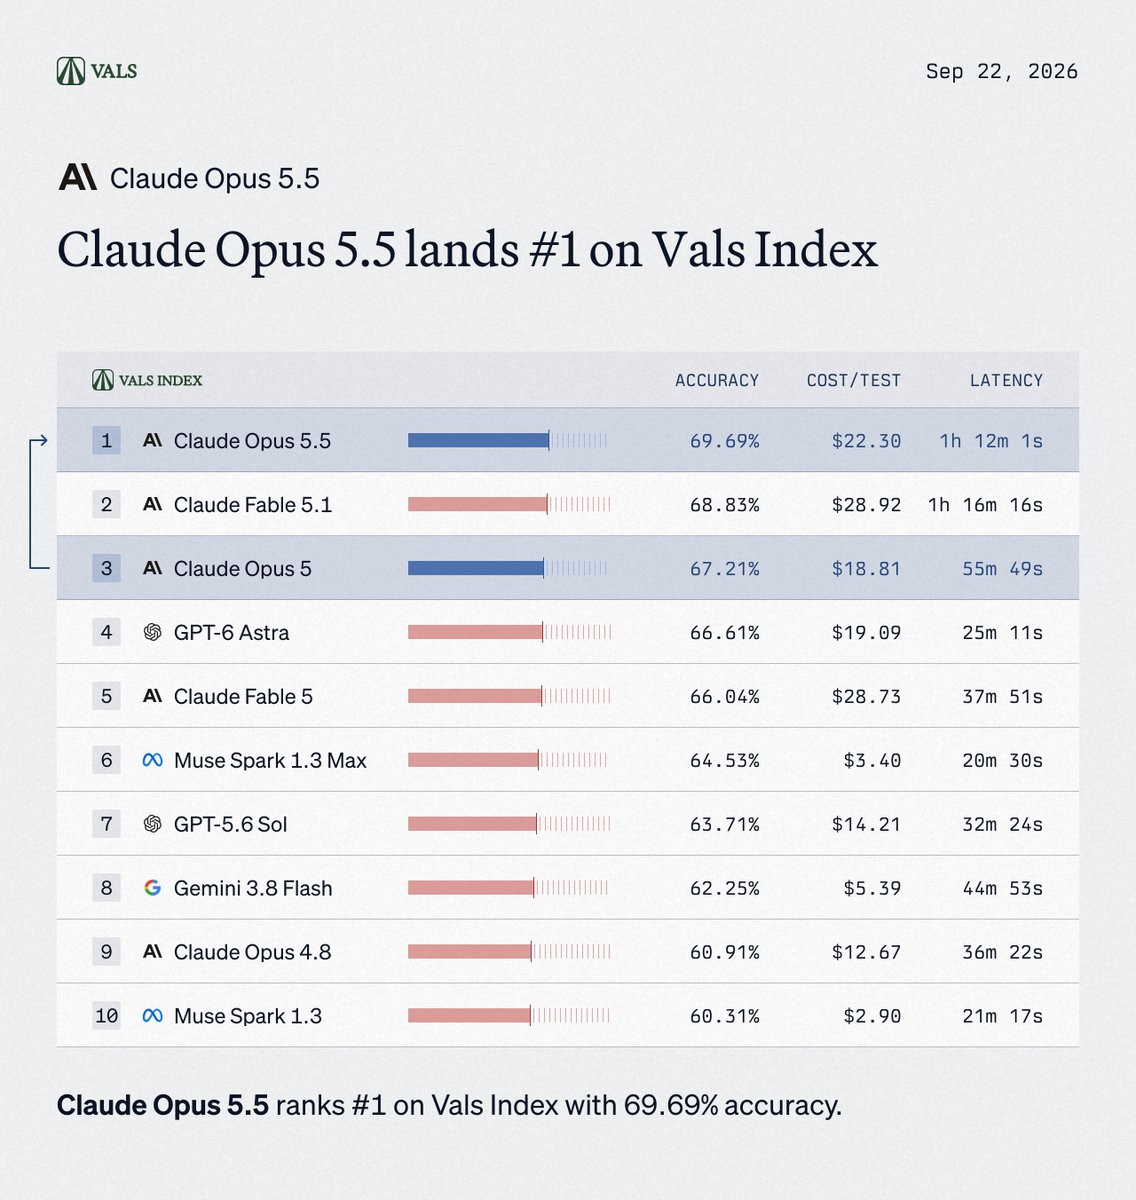
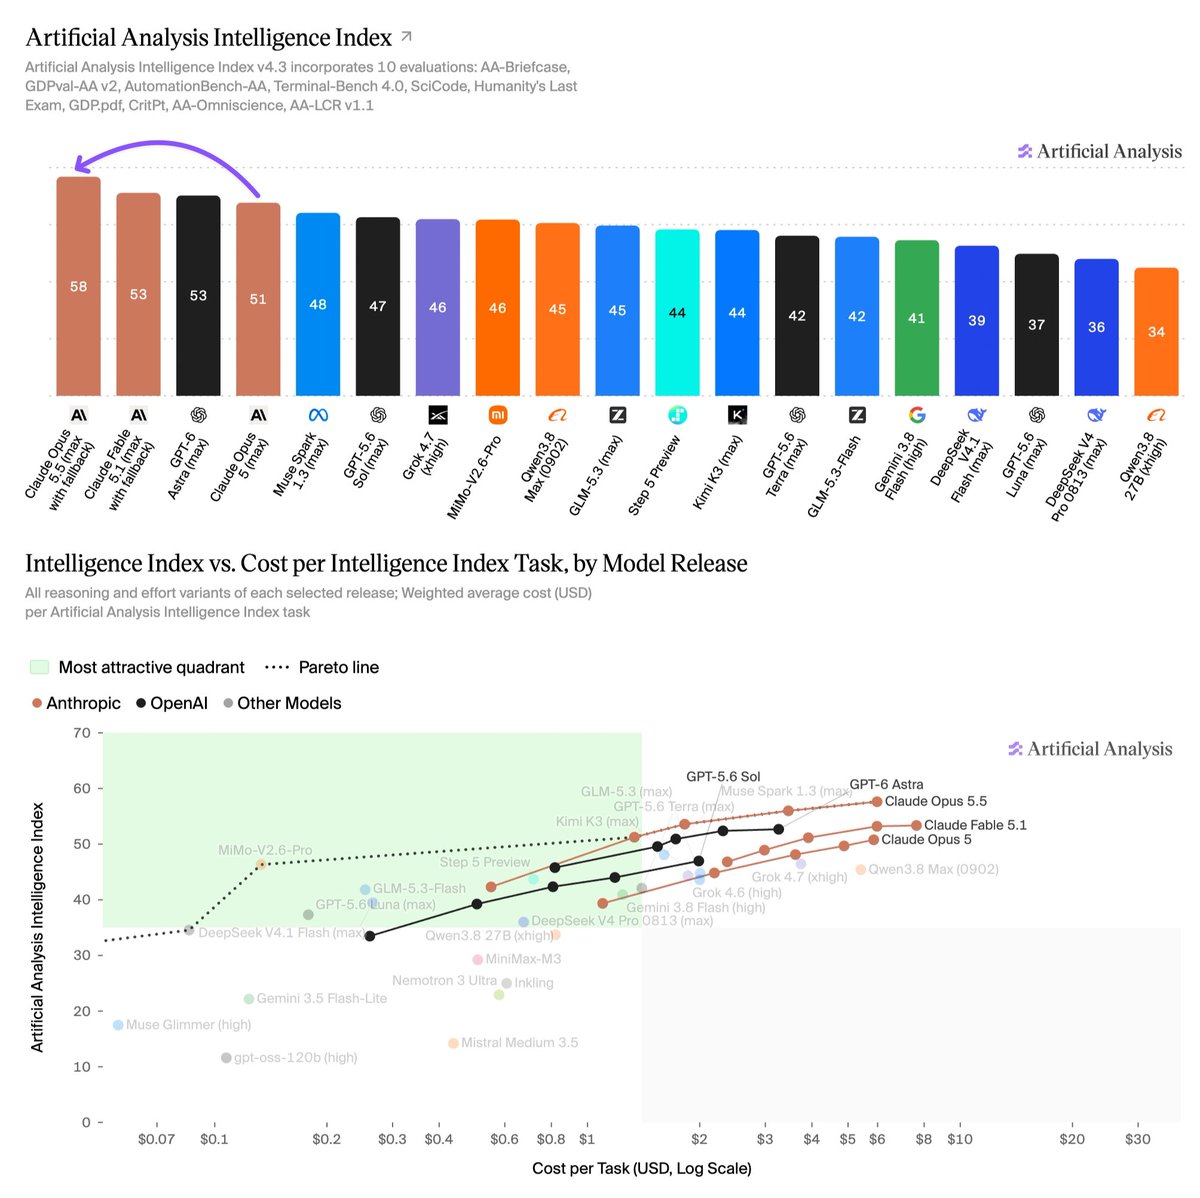
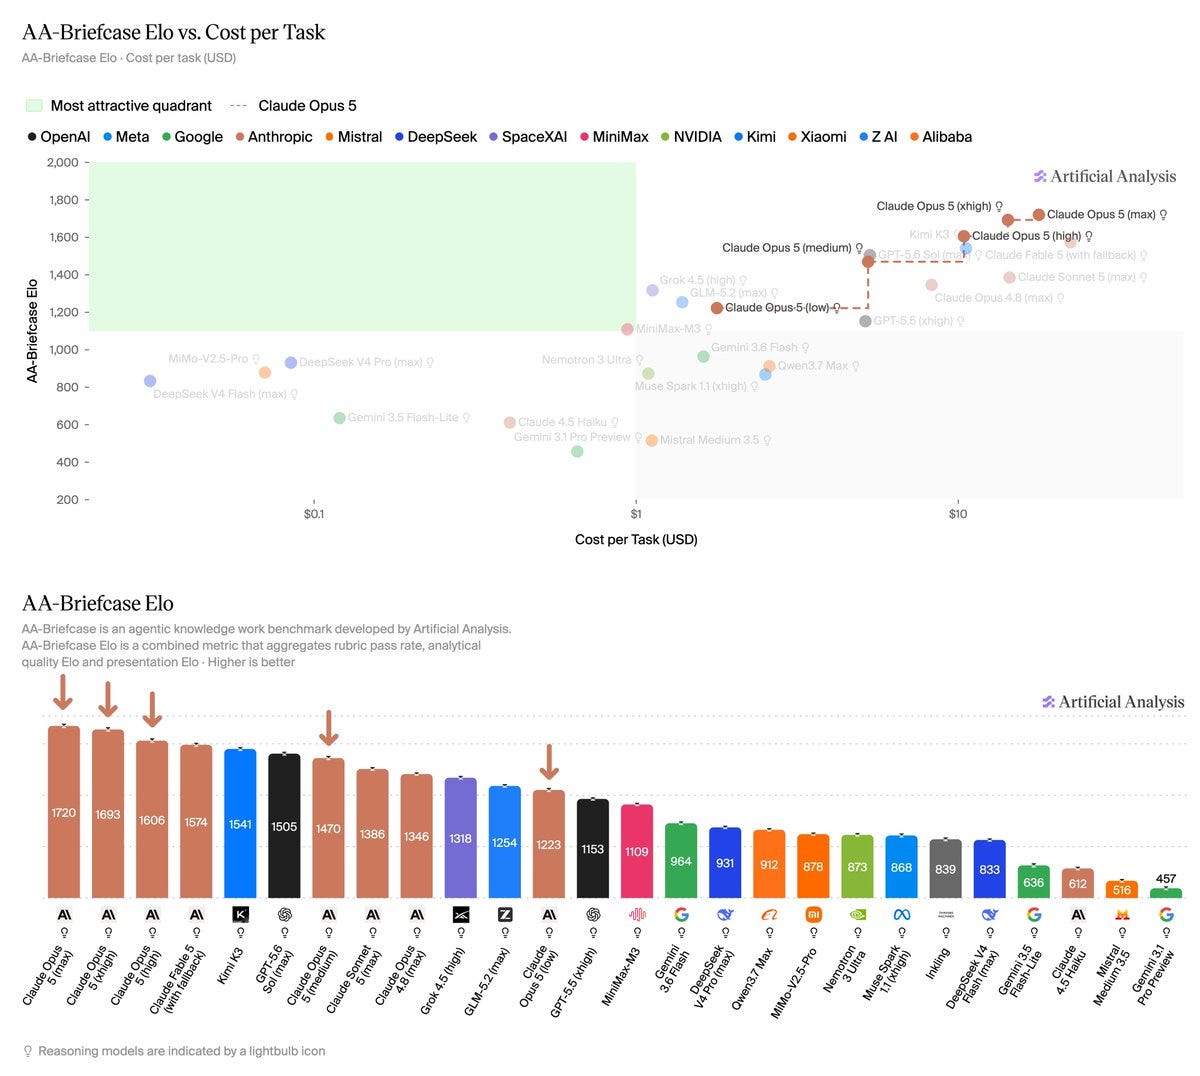
Opus 5.5 is #1 on the Vals Index, up 2 spots and 2 pts from Opus 5. Anthropic regains the top three spots on the Index, but GPT-6 Sol results will be released soon. https://t.co/w3glxLqHgS
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
Why it matters
Gives an independent read on model rankings for agentic and coding-heavy work, including a first-of-its-kind benchmarkA standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.Full definition → result for long-horizon agentic training tasks.