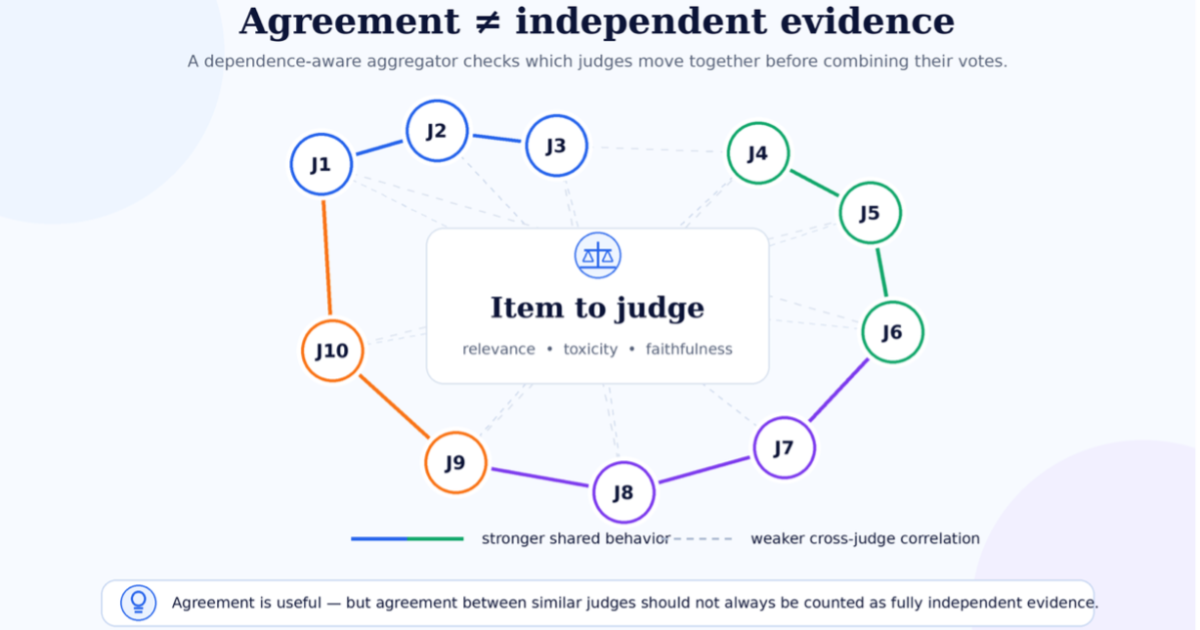
LLMs are better at predicting what other models will say than what’s actually true. When they’re wrong, they’re wrong together; so polling can’t recover the truth. Check out this paper at ICML! 🇰🇷 https://t.co/IMTA2pZqTK
Shows that sampling multiple models and taking a majority vote, a common technique for boosting accuracy, doesn't help and can even reinforce shared errors when there's no ground-truth verifier.