Intel
Page 82
The Next Medium: Why Real-Time Interactive Video Changes Everything — Ahmed Ahres, Reactor
The case that real-time generative video is a change of medium rather than a speedup, with the consequences that follow.
Why it mattersIf you are building on video models, none of the batch serving playbook carries over to interactive generation.

Infra behind Krea 2: How to train and serve at scale — Gabriel Jorge Menezes, Krea.ai
An infrastructure lead on training at cluster scale.
Why it mattersConcrete metrics and failure modes for anyone operating large training clusters, including how to keep a site up while training holds priority.
We're making Git hosting more reliable, performant, and scalable. This post trac
Cursor traces twenty years of Git hosting design and explains why it operates its own storage layer, Origin, as a database rather than a filesystem.
Why it mattersAnyone running agents against many repositories at once hits the same Git scaling limits, and this documents one team's design and operational reasoning in detail.

Anthropic has opened Claude Cowork to mobile and web across every paid plan, taking the agentic workspace beyond the desktop application.
Why it mattersThe agent workspace is now reachable from a phone and browser, which changes where and when work can be handed to it.
Run Massive-Scale UMAP in Minutes Using Multiple GPUs—Without Losing Accuracy
cuML and cuVS 25.06 distribute UMAP's all-neighbors kNN construction across GPUs by partitioning into balanced clusters, computing local graphs, then merging.
Why it mattersEmbedding-space analysis at hundred-million-vector scale drops from an overnight job to minutes, and the partition-and-merge design keeps embedding quality rather than trading accuracy for throughput.
➤ Leaderboard: ➤ Methodology: ➤ Stirrup, our open-source agent harness: Search A
Artificial Analysis benchmarks 15 search APIs from 7 providers inside a fixed agent harness — same model, same tasks, only the search tool varies.
Why it mattersChoosing a search API for an agent has been guesswork. This holds model and harness fixed so quality, blended cost and added latency are comparable — including how much a weaker provider costs you in extra model tokens.

Benchmark results place two search providers on the cost-quality frontier for agent tasks, with one scoring 73 at 7.5 cents per task but the slowest completion time, and another reaching 75 for 12 percent more.
Why it mattersSearch provider choice moves both agent answer quality and total task cost, and this puts numbers on the tradeoff.
Artificial Analysis launched a Search Index scoring seven search API providers inside its open-source Stirrup agent with one fixed model. It averages DeepSearchQA, BrowseComp and AA-Omniscience and reports cost and time per task. Parallel, Exa and Firecrawl lead, against a 33 no-search baseline.
Why it mattersWith model and harness held constant, search providers differ by up to ten index points. A pricier but more focused tier can cut total cost per task by shrinking model token use, so per-call price and latency are poor selection criteria.
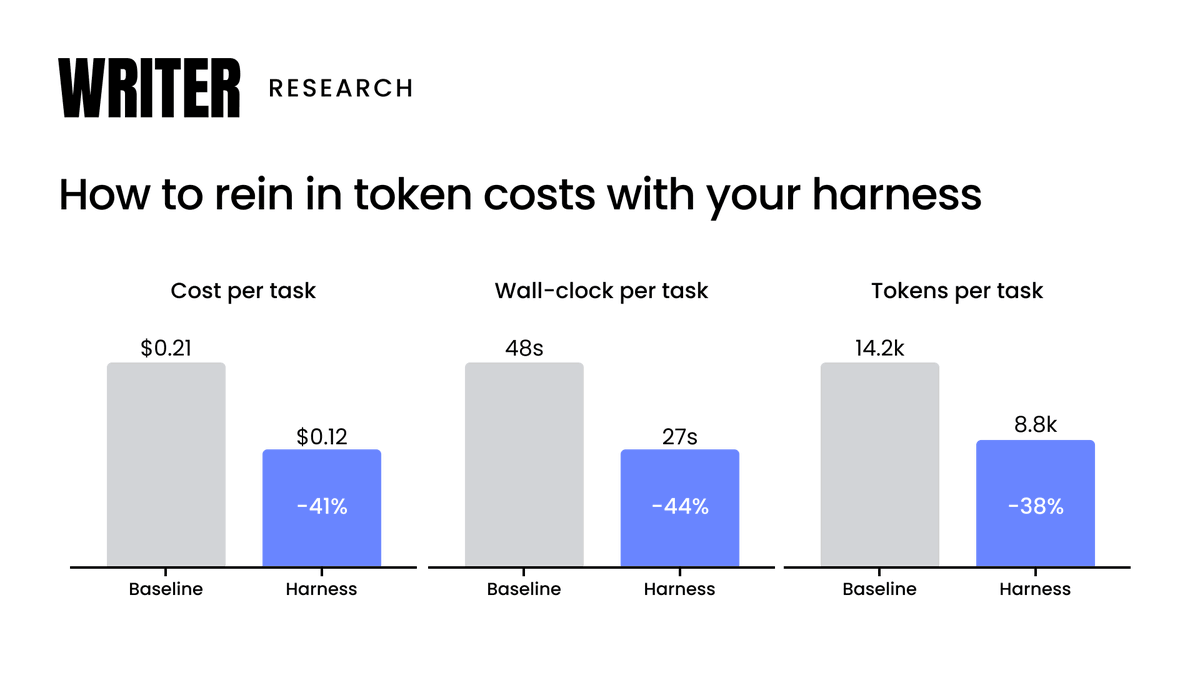
Harness Design Cut Agent Cost 33-61% Across Six Models
Writer benchmarked six models on 22 tasks against a naive harness and a token-efficient one built on cache-stable prompts, incremental compaction, context offload, zero-token waiting and retry limits.
Why it mattersAgent cost is dominated by input tokens, so cache hit rate matters most. Keeping a byte-stable prompt prefix, compacting incrementally and bounding retries cut cost 33-61% across six models in Writer's tests, with quality parity.

Generative Video at the Speed of Light — Keegan McCallum, uRun
Ten dollars now buys about three hours of continuously generated video.
Why it mattersCurrent cost and latency numbers for interactive video generation, plus the serving architecture it demands.
Introducing LangSmith Tuned Evaluators They automatically score agent behavior i
LangSmith adds Tuned Evaluators, small tuned models that score production agent traces automatically, starting with Perceived Error.
Why it mattersOnline evaluation of production agent traces is usually priced out by frontier-model judges, and a tuned small model that claims better accuracy at a fraction of the cost changes that calculus.

Perplexity Computer is now addressable by email. Send, forward or cc its address on a thread and the request runs as a regular session visible on web and mobile, with the same audit trail as in-app tasks. Available to all Computer users.
Why it mattersAgent tasks can now start from any email thread by cc'ing the agent, with each run logged as a normal session with the standard audit trail. Email becomes a trigger surface for delegation without opening the app.
Full breakdown: Claude-only apps often wait until the host speaks the new revisi
MCP spec 2026-07-28 removes the initialize handshake and session header, making each tool call a self-contained POST any replica can answer.
Why it mattersIf you run an MCP server, protocol sessions and sticky routing are gone: a dropped response is now a full retry, so every write-or-charge tool needs a caller-supplied idempotency key to avoid double execution.

What the stateless protocol revision changes for server authors: tool calls without a handshake, and a timed-out retry counting as a fresh call so one aborted request produces two writes.
Why it mattersIf your server treats a dropped connection as a rollback, ordinary retries can double-write, and this shows the failure with a reproduction.

While my guitar gently speaks — Todd Fisher, Philo Ventures
A JUCE plugin routes a microphone through speech recognition into a local model and answers through guitar strings.
Why it mattersA worked example of putting a local model inside a real-time audio pipeline, including why silence-based segmentation of synthesized speech breaks and what to pair it with.

The Next Game Engine Won't Have a Manual — Arturo Nunez, Nereu
A game engine designed around coding agents.
Why it mattersLevel-of-detail context assembly is a reusable answer to giving an agent a workspace too large to fit in a prompt.

Building an Agentic Video Editor for Mass Consumer — Ekaterina Deyneka, Reelful
An agentic video editor built like an agentic app builder.
Why it mattersThe pattern of encoding taste in skills and adding a render-verification loop transfers well past video.
Training Krea 2: What matters in generative model training — Sangwu Lee, Krea.ai
What actually goes into training an image model.
Why it mattersData curation, not architecture, is where generative model quality gets decided, and this names the filters, dedup passes, and caption failures that shape what the model learns.
$1 million hacker challenge for Vercel Sandbox
A two-week public bounty program pays up to one million dollars for escaping a microVM agent sandbox.
Why it mattersAnyone running untrusted agent code should understand where this isolation model actually breaks, and the findings will be public.
Ben Thompson: Winners & Losers of the AI Era
When a model reads a drug's class from its name—not its knowledge
Researchers separate what a model knows about a drug from what it can infer from the drug's name, then trace the shortcut back into the training corpus.
Why it mattersDrug names encode their class in suffixes like -pril and -olol, so a model can answer correctly from spelling alone. On Olmo 3, most tested drugs showed little genuine drug-specific knowledge behind confident answers.

The model behind Sakana Chat is now available through OpenRouter, bringing Japanese and business-context reasoning with web search and code execution into any workflow already routing through that gateway. Pricing is listed at $0.95 input and $4 output per million tokens.
Why it mattersNamazu is callable through OpenRouter at $0.95 in and $4 out per million tokens, so adding a Japanese-tuned model with web search and code execution to an existing router setup is a config change, not a new integration.

SemiAnalysis flags a 50 percent OpenAI price cut on GPT-5.6 Sol limited to two gateways, and argues the venues were picked because they are the datasources most used to estimate model market share.
Why it mattersThe cut changes routing economics for anyone serving Sol through those gateways, and it is a warning that gateway-derived market-share charts are now a target for pricing decisions.
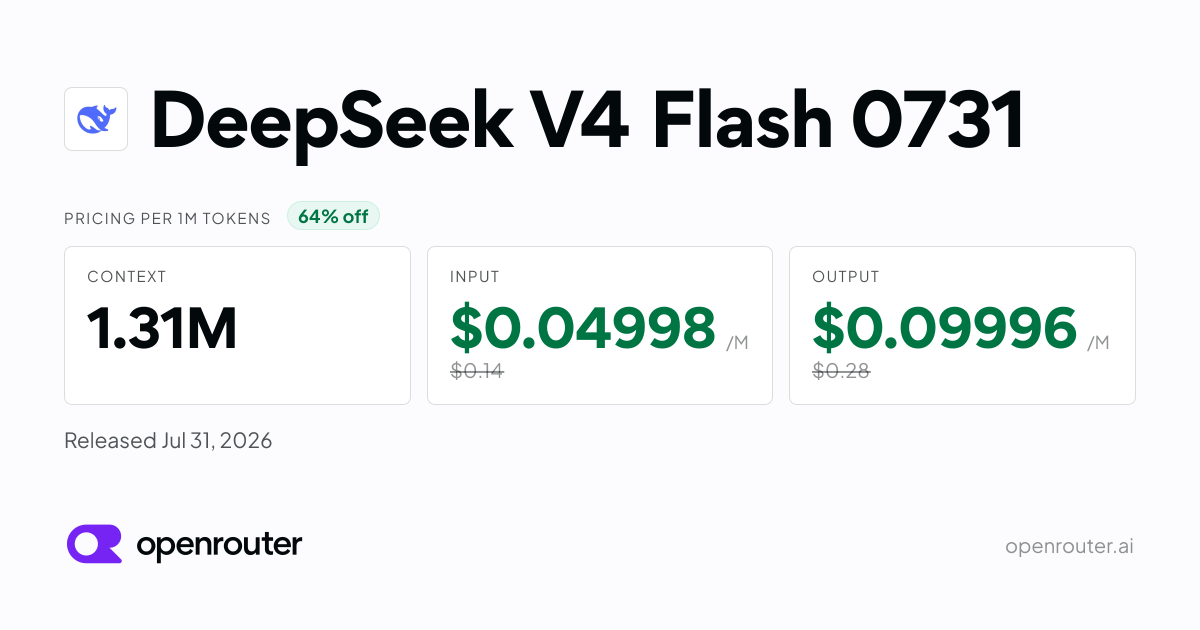
Model pricing is getting more complex over time.
DeepSeek charges different rates by hour of day.
Why it mattersModel pricing is no longer a single number. If batch and eval jobs can be shifted in time, DeepSeek's off-peak windows cut the bill without changing the model.
AgentR A Stateful and Recovery-Aware Software Architecture for LLM-based Auditable Workflows
An architecture for stateful LLM workflows built on durable artifacts, queue-backed workers, explicit state transitions, retry and orphan-job handling.
Why it mattersMost agent applications are still stateless prompt-response wrappers, and this lays out what has to exist for one to survive interruption and stay auditable.
The Quality of Claude AI-authored Python Tests Is Not Weaker Than Human-authored Tests
A controlled study scoring hundreds of Claude-written Python tests against human-written Django and Pandas tests under identical fault-injection and design rubrics, reporting non-inferiority for recent models.
Why it mattersTest quality is the usual objection to letting an agent write tests, and this puts a measured, individually-scored answer against two mature human corpora.
HxAgent: Iterative Agent Planning for End-to-End Web Application Testing
An iterative LLM planning agent for web testing that re-reads page state after every action and draws on both recent actions and past correct and incorrect sequences, reported ahead of WALT on three benchmarks.
Why it mattersThe proactive re-assessment loop and the split between short-term and long-term memory are directly transferable to anyone building a browser-driving agent.
The Unwritten Benchmark: A New Challenge for Multimodal Machine Learning in Abstract Perceptual Reasoning
A benchmark asking models to infer written words from pen-scratch audio and hand-movement video with no visible ink, where humans clear 80 percent accuracy and leading multimodal models stay under 10.
Why it mattersIt marks a class of inference from dynamic multimodal evidence where current frontier models fail almost completely, which is useful when scoping what a multimodal agent can be trusted to do.
Evaluating Agentic Code Repair Capabilities in Distributed Systems
A code-repair benchmark of 60 real distributed-system bugs that runs each case with and without bounded debugging context, isolating how much logs, traces and runtime state change agent success.
Why it mattersCoding agents cluster in the high 70s on single-process SWE-bench, and this shows what happens when root causes span processes and what feeding in logs and traces is worth.
The Recall Trap: A Recall-Maximizing Retriever Configuration Reduces Issue Resolution in Fixed-Budget Code Context
A controlled study on SWE-bench Verified showing that the higher-recall retriever setting lowers single-shot issue resolution under a fixed context budget.
Why it mattersRetrieval for code agents is routinely tuned against recall@k, and this is direct evidence that optimizing that metric can cost you resolved issues when the context window is fixed.
Kozuchi Agent: A Language-Agnostic Open-Weight Agent for Software Repair
An open-weight software repair agent with explicit phases, persistent state and deterministic tools that resolves 374 of 500 SWE-bench Verified instances on the official evaluator using a locally hosted 27B model.
Why it mattersIt is evidence that a locally hosted open-weight model plus disciplined agent scaffolding reaches frontier-adjacent repair rates, which changes the build-versus-buy calculation for teams that cannot send code to a hosted API.

Anthropic reports Claude Code CLI now uses half the CPU at p99 after moving Bun's garbage collection off a fixed timer to run only when the process is idle.
Why it mattersAnyone running Claude Code in CI or on constrained machines gets the win by updating, and the timer-versus-idle GC diagnosis generalizes to other Bun-hosted agent runtimes.
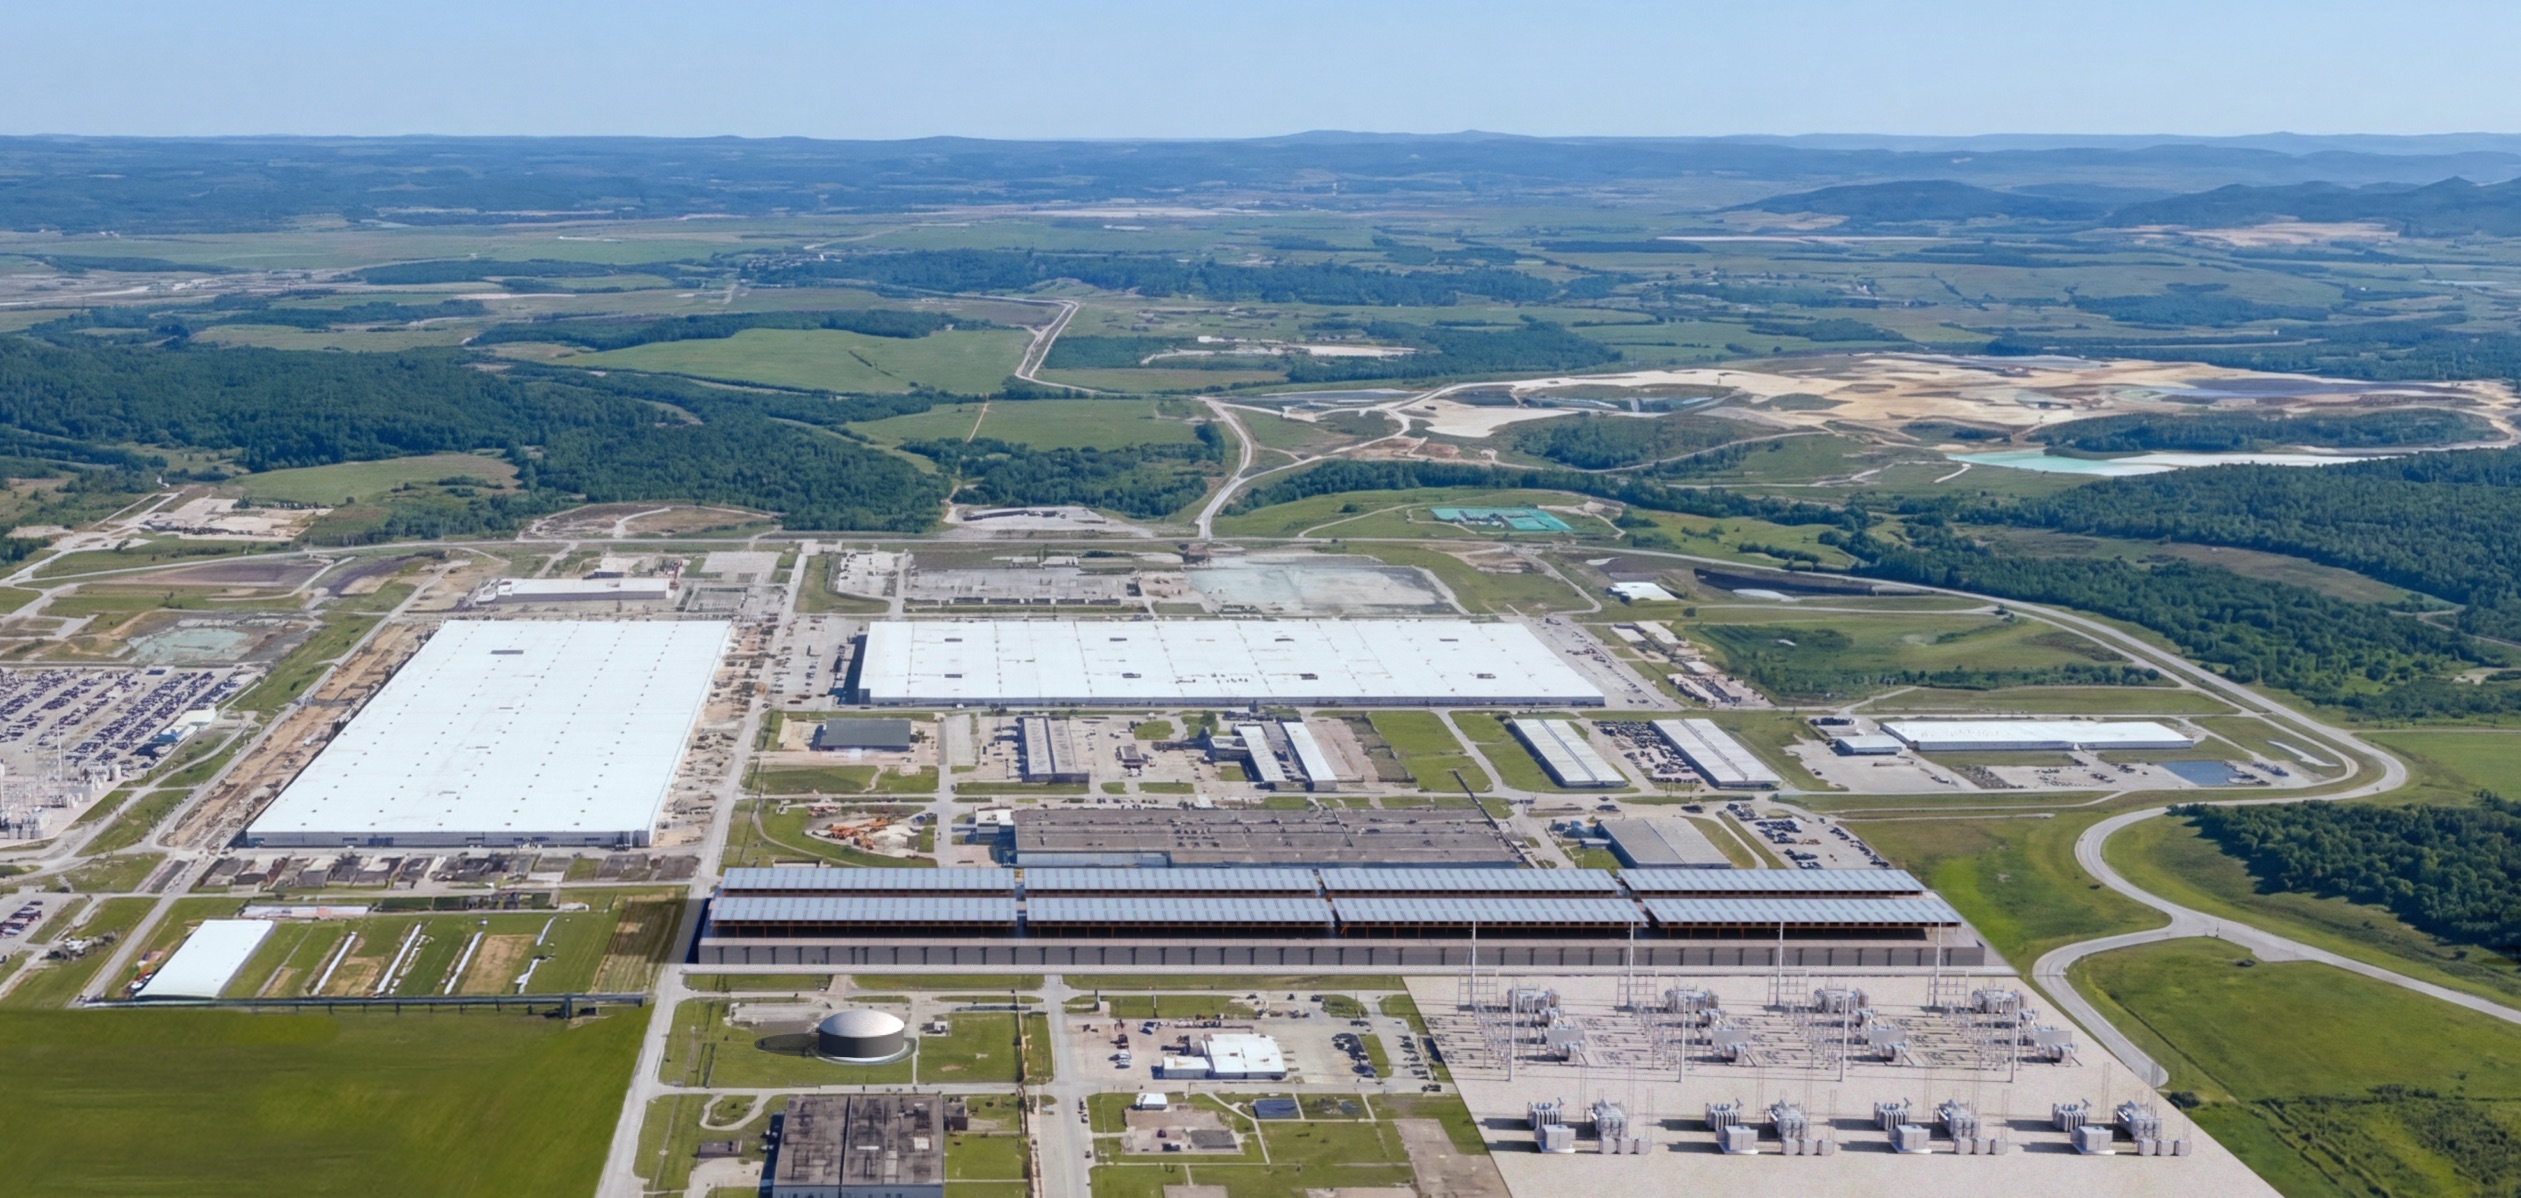
8/17: Nvidia + OpenAI + SB Energy = PORTS-Pike
Search Api
Artificial Analysis launches the Search Index comparing search API providers inside the Stirrup harness with GPT-5.6 Luna, scored on DeepSearchQA, BrowseComp and AA-Omniscience against a no-search baseline.
Why it mattersHolding the agent and model constant, it measures how much each search API lifts answer quality, cost and speed, helping you pick a search provider for research agents.
GLM 5.3 now available on AI Gateway
GLM 5.3 lands on Vercel's AI Gateway with better multi-step agent and software engineering results than GLM 5.2 at fewer output tokens, a 1M token context window, 128K max output.
Why it mattersA new open-weights-class model reachable through an existing gateway, with published effort levels and a documented path into Claude Code, Codex and other agents, is directly actionable.
Cline is now available in the AI SDK harness layer
Vercel adds an official Cline adapter to the AI SDK harness layer, built with the Cline team.
Why it mattersSwapping coding-agent runtimes behind one interface is the point of the harness layer, and each added adapter widens what a team can switch to without rewriting application code.
Why Ai Agents Need A Cloud Browser
The browser, not the model, is usually where agent automation breaks.
Why it mattersNames the specific points where an agent's browser layer outgrows a laptop Chrome, and what changes at the CDP boundary when it moves — the reasoning holds whether you buy or self-host.
Multi-Vector (Late Interaction) Embedding Models with Sentence Transformers
Sentence Transformers v6.0 adds MultiVectorEncoder for ColBERT-style late interaction.
Why it mattersLate interaction preserves token-level matching that a single dense vector averages away.
DeepSeek V4 Pro 0813 vs GPT-5.6 Sol on DeepSWE: Cost, Coding, and Routing
A DeepSWE head-to-head putting DeepSeek V4 Pro 0813 against GPT-5.6 Sol on accuracy, cost per rollout and failure modes.
Why it mattersIt quantifies when a 35x cheaper model is good enough and gives a concrete escalation policy teams can copy into their own routing layer.
Qwen 3.8 27B scores 52 on the Artificial Analysis Intelligence Index
Qwen 3.8 27B lands at 52 on the Artificial Analysis Intelligence Index — the same score as GPT-5.6 Luna (max), one point behind GLM-5.2 and DeepSeek V4 Pro, both vastly larger.
Why it mattersAn open-weight 27B model scoring level with a frontier closed model on a public index changes the arithmetic on running inference locally instead of paying per token.
[AINews] Stripe buys OpenRouter for $7B
Stripe's ~$7B acquisition of OpenRouter closes 90 days after a $1.3B Series B, on roughly $140M annualized revenue and ~70% gross margins, with 250T tokens routed monthly.
Why it mattersThe router 8 million developers call is now Stripe-owned, and the disclosed numbers — 250T tokens a month at roughly 70% gross margin — show where margin in the AI stack is actually landing.

I'm done with terminals
Theo argues the terminal is the wrong surface for coding with agents, and that after a career spent living in it the workflow now needs something else.
Why it mattersEvery coding agent shipping today defaults to a terminal, so a serious argument that it is the wrong surface is worth hearing before teams standardize around it.
SemiAnalysis traces Google's TPU interconnect from 2D torus on TPUv2 to 3D on v4/v5p and Boardfly on v8i, then walks the rumored 6D torus for TPUv9t: 12 ICI links per chip, worst-case hops on 4,096 chips cut from 24 to 12, paid for in far more optics.
Why it mattersCluster topology sets how far a training job scales efficiently. A 6D torus halves worst-case hops and multiplies bisection bandwidth, paid for in optics and OCS capacity — a cost that shapes future TPU availability and pricing.
Claude Code ships /design as a research preview in both CLI and Desktop, bringing Claude Design's artboard workflow to the terminal on top of artifacts — generate UI options, edit the one you want, then have Claude build it. Live on Pro, Max, Team and Enterprise after updating.
Why it mattersDesign exploration now happens inside the coding agent: generate editable artboards for a UI, pick one, and have Claude implement it rather than describing the interface in prose.
Anthropic's ClaudeDevs account announces a /design skill in research preview for Claude Code CLI and Desktop. It brings Claude Design's artboard workflow, built on artifacts, so users pick and edit a UI artboard and then have Claude implement it.
Why it mattersClaude Code can now produce editable UI artboards before writing code, so you can pick and tweak a design and then have the agent implement it, instead of describing layouts in prose.

Tarun Chitra ran paid experiments on OpenRouter and found that providers who cut quoted prices often lose cache hits, so repeated agent queries cost more. He models routing as a Tullock contest, estimates about 2% of revenue extracted, and proposes ranking by effective session price.
Why it mattersThe cheapest quoted token on OpenRouter is not always the cheapest conversation: some repricing providers drop cache hits, and after roughly 5 repeated queries you can pay more than at the model builder's endpoint.

How to Kill the Code Review — Ankit Jain, Aviator
Ankit Jain argues code review has already ended, with over 30% of changes merging unreviewed, and proposes replacing the diff with intent and evidence.
Why it mattersTeams are already merging AI-written code with no human reader, and this is a worked proposal for what replaces the diff as the review surface rather than a complaint about it.

Sakana AI's Namazu is routable on OpenRouter. Built on Kimi K2.6, it pairs reasoning with integrated web search and code execution and is specialized for Japanese cultural and business context.
Why it mattersIf you serve Japanese-language workloads, there is now a reasoning model tuned for that context with web search and code execution, reachable through the same OpenRouter API as everything else in your stack.
Same Cluster, 33 Points More Utilization: What Changed Was the Order
A constraint-aware GPU allocator benchmarked against FIFO across seven scenarios on identical hardware.
Why it mattersCluster utilization under contention is decided by allocation order, not hardware: mixing contiguous-block training jobs with elastic inference demand under FIFO leaves large amounts of capacity and priority-weighted output on the table.
Download Hermes Desktop to get started:
Nous ships Hermes Agent as a native desktop app for macOS, Windows and Linux alongside the terminal build.
Why it mattersAn open-source agent you can run locally across desktop and terminal, with per-session sandbox backends spanning Docker, SSH, Singularity and Modal, persistent memory across chat surfaces.
An index of the vibe-coding frontier. Corrections welcome.