Intel
Page 81
A Codex postmortem on destructive deletes: cleanup routines reused variables like $HOME and could target the real home directory, and temp paths were overwritten without checking contents. Fixes span explicit model instructions, execution-layer detection of high-risk delete commands, and making Full
Why it mattersA specific failure mode for any shell-wielding agent: env-var reuse in cleanup commands can resolve to a real home directory.
Cerebras's Next Generation CS-4: Fast Just Got Faster
SemiAnalysis breaks down Cerebras CS-4, which doubles inference throughput on the same 5nm wafer by roughly doubling clock speed.
Why it mattersInference economics set what agent workloads cost to run, and a doubling in tokens per second per user at flat cost moves that arithmetic.
Building Shared Memory For Ai Agents In Notion
Notion open-sourced Lore (MIT), a shared persistent memory for agents backed by Notion pages and reachable from any MCP-compatible harness.
Why it mattersAgent memory is usually harness-local or machine-local.
Vercel Connect now supports Microsoft
A managed connector that registers the identity application and federated credentials for you.
Why it mattersAgent integrations usually die on credential management. Short-lived tokens issued against a deployment identity removes the stored secret from the picture.
Introducing Vercel for Slack
Vercel Agent is now reachable in Slack for Pro and Enterprise teams in public beta.
Why it mattersApproval-scoped, temporarily elevated agent access with per-action attribution is the pattern most teams will have to copy when they put agents near production.
Openrouter Is Joining Stripe
The largest multi-model gateway is joining Stripe, with no announced change to the API, product or roadmap.
Why it mattersOpenRouter, the gateway many agent stacks route through, is being acquired by Stripe. The company states the API, name, pricing model, and roadmap are unchanged, so no integration action is required.
Fish Audio models now available on Vercel AI Gateway for free
Four Fish Audio speech models, three text-to-speech and one transcription, are now served on Vercel AI Gateway and free through September 18.
Why it mattersFree-tier model names that quietly convert to paid are a real billing hazard, and the suffix behavior here decides which of the two you get.
Chat SDK adds Instagram adapter
Chat SDK gains an Instagram adapter so bots can handle DMs, media, quick replies, reactions and story replies through Meta's messaging API.
Why it mattersAdds a mainstream consumer messaging surface to bot and agent builds without hand-writing Meta API plumbing.
Exa joins the Vercel AI Gateway and Agent Marketplace
Exa lands on Vercel as a native integration.
Why it mattersAny model on Vercel's AI Gateway can now ground itself in live search through a built-in Exa tool — no separate Exa key, and the gateway runs the search loop rather than your application code.
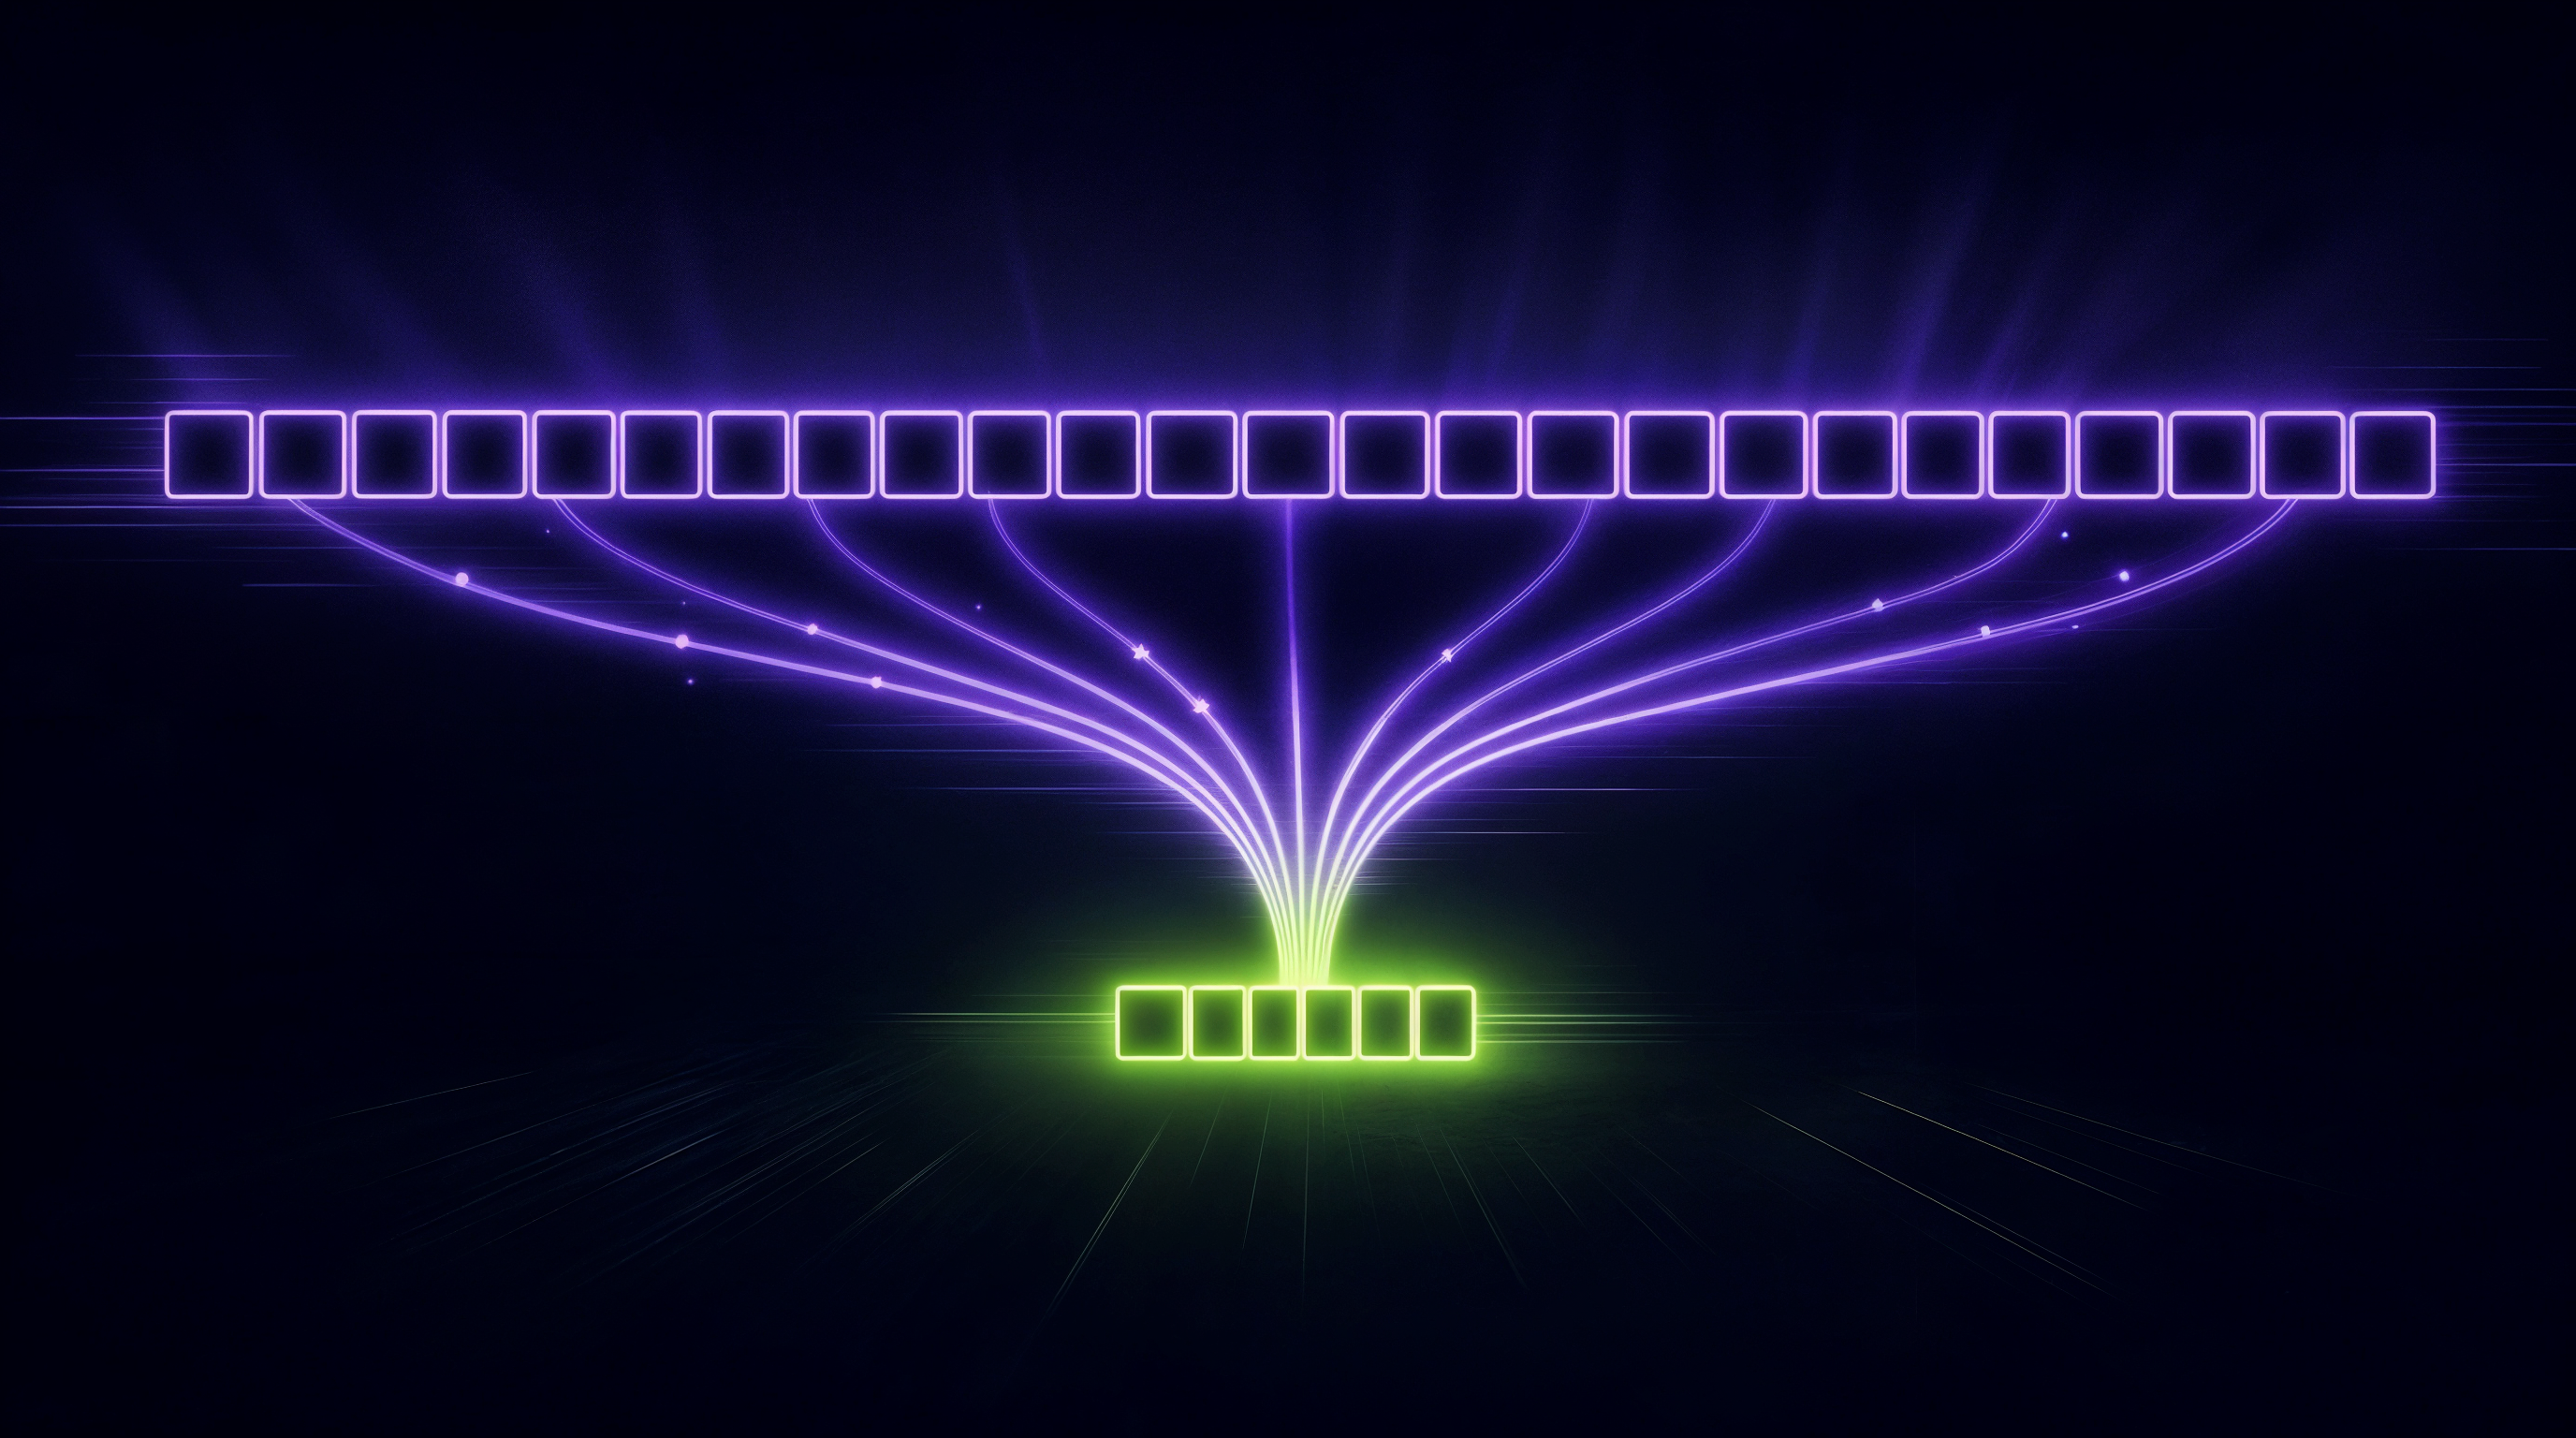
Gisting
Gisting trains embeddings for special tokens that stand in for a long system prompt at inference time.
Why it mattersLong system prompts are a recurring inference tax on self-hosted agents; distilling them into learned gist token embeddings cut a 6k-token prompt 4:1 with measured latency and throughput gains and no quality loss.


Artificial Analysis Index = 60 https://t.co/ts3QfDtRmv
Why it mattersGLM-5.3's API is now generally available at GLM-5.2 pricing via the official API and partner gateways, giving engineers a same-cost upgrade path for coding and long-horizon agent workloads.

Anthropic's Claude Desktop now boots roughly twice as fast, after the team found background windows were throttling timers and dropping the JS engine into power-saving mode.
Why it mattersAnyone shipping an Electron-based agent client hits the same background throttling, and the fix is stated plainly enough to apply.
8/18: OpenAI Paces the Frontier
Maritime, a platform for running AI agents for $1 a month
Maritime provisions one isolated micro-VM per agent from a single command.
Why it mattersPer-tenant agent isolation is otherwise a build-it-yourself problem, and a micro-VM per agent with lifecycle webhooks is a credible shape for it.

React Grab, the browser tool that copies a UI element into a prompt for your coding agent, now handles Three.js and React Three Fiber scenes.
Why it mattersHanding an agent the right element instead of a screenshot is the difference between a usable and a wasted turn, and 3D scenes were a real gap.
Clinch – Local-first Warp fork built for agent session management
Clinch is a local-first Warp fork built around agent session management.
Why it mattersManaging many concurrent coding-agent sessions across repos is an unsolved daily problem, and this is a considered answer to it rather than a terminal reskin.
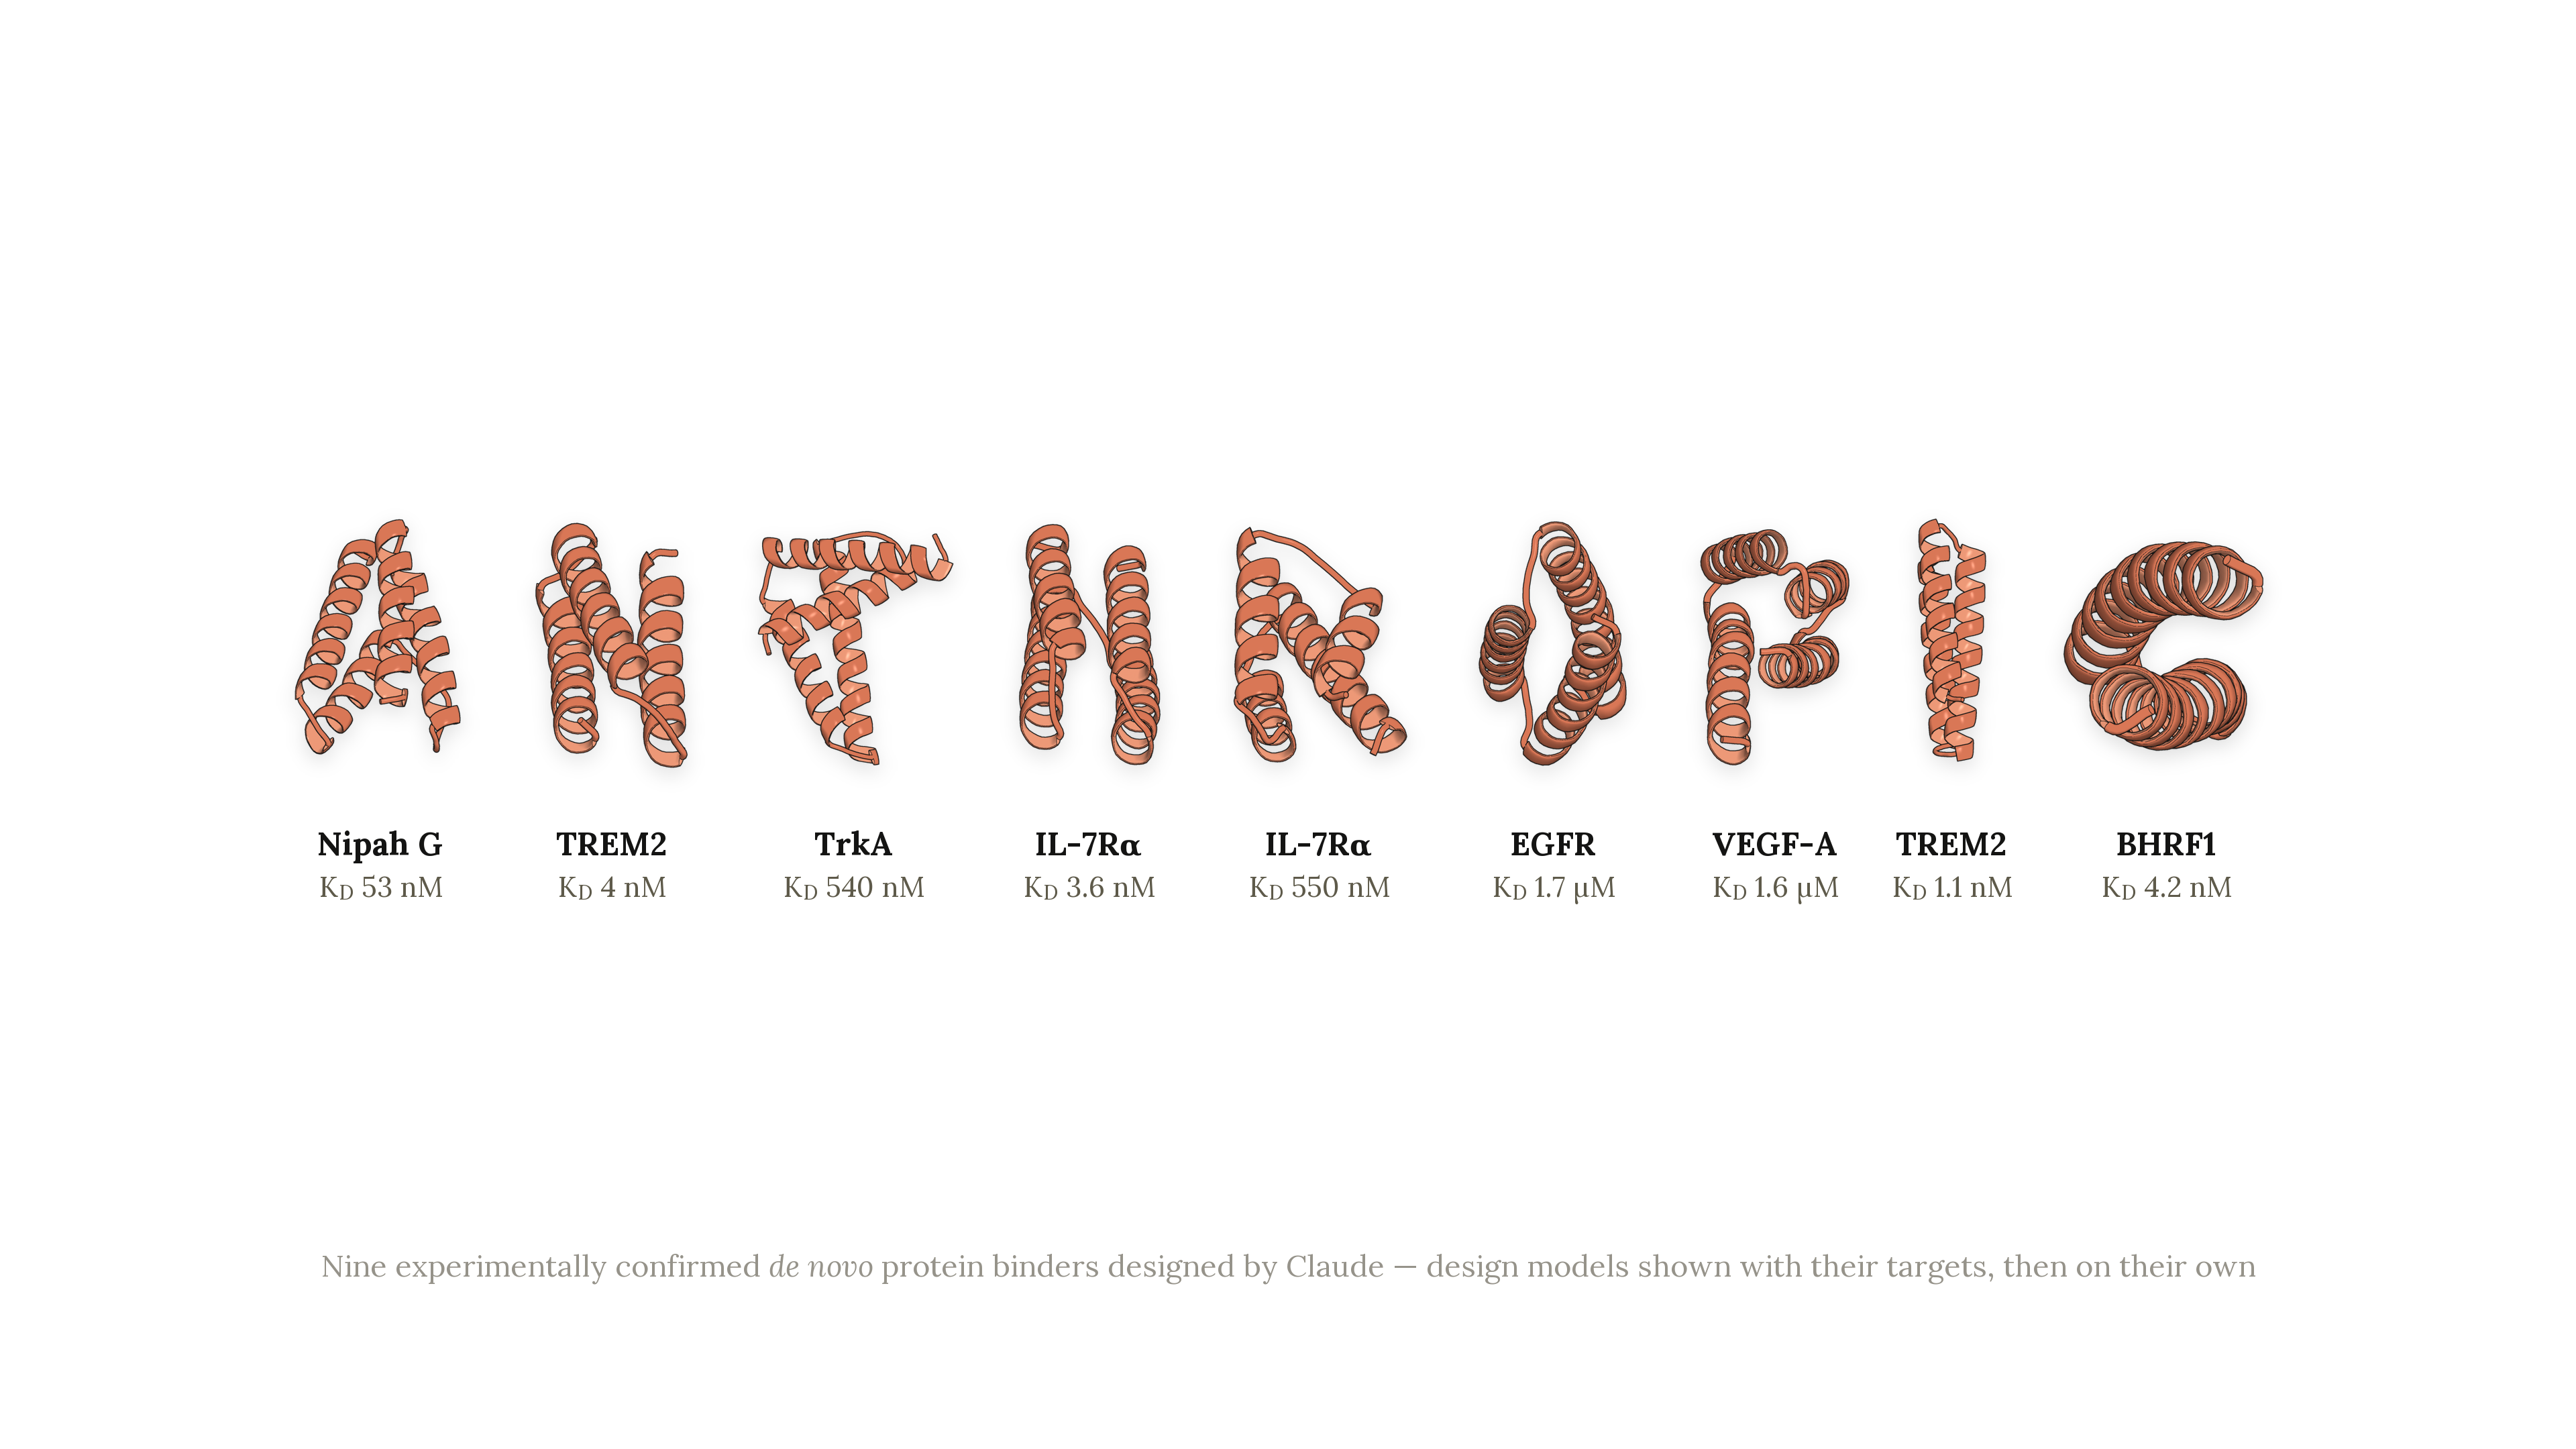
For more on how Claude ran this experiment and the full results, see our blog:
Anthropic reports Claude designing protein binders that hit 14 of 15 targets at a 22-35% per-design bind rate against a 10-15% field norm.
Why it mattersA generally available model matched or beat expert baselines on protein binder design and analytical chemistry, with per-design success rates and turnaround times published against human results.

Given a design prompt written by a human expert, Claude autonomously designed de novo protein binders against 14 of 15 targets. Adaptyv Bio and Twist Bioscience built and tested them, with 22 to 35 percent binding against a field baseline of 10 to 15 percent.
Why it mattersAn autonomous design loop validated by outside labs is a concrete data point on where frontier models now sit on open-ended scientific work.
See the full results for GLM-5.3 at
Z AI's GLM-5.3 scores 60 on the Artificial Analysis Intelligence Index, ninth of 187 and seven points above GLM-5.2, with a 1M context at $1.40/$4.40 per million tokens.
Why it mattersGLM-5.3 reaches the leading open-weights tier at moderate pricing, but consumes roughly 2.4x the median tokens on the same evaluation — the verbosity, not the sticker price, drives its real cost.
GLM-5.3 achieves 60 on the Artificial Analysis Intelligence Index, on par with K
Artificial Analysis scores GLM-5.3 at 60 on its intelligence index, level with Kimi K3, with a 246 point jump to 1770 Elo on its agentic evaluation.
Why it mattersAnyone weighing an open weights model for agentic work needs the cost and token-efficiency side of the trade, not just the headline score, and this gives both.

OpenRouter serves GLM-5.3 and points at where the gains came from: the same base model as GLM-5.2, with post-training alone moving Terminal-Bench 3.0 from 4.6 to 28.3 and DeepSWE v1.1 from 46.2 to 66.9.
Why it mattersA jump of that size on an unchanged base model is evidence that agentic competence is now largely a post-training problem, and the model is callable today rather than a paper claim.
Frontier Model Cost and Open-Weights Popularity is Driving Demand for Model Routing
Glean's Arvind Jain explains why frontier model cost and stronger open weights have made routing a core deployment layer, including the case for answering some queries without an LLM at all.
Why it mattersModel routing is becoming a deployment layer of its own, and this lays out how a large deployment decides which model, or no model, handles each task.
Mojo🔥 is now open source
Three years after promising it, Modular has released the Mojo compiler and toolchain under Apache 2, a week after shipping 1.0.
Why it mattersGPU kernel work now has an open-source, Python-flavored toolchain you can read, fork and build on, with the compiler no longer behind a vendor license.
Tomorrow, voice AI meets its toughest test: a real phone call. 📞 We’re teaming…
A Deepgram and Twilio session on what changes when a voice agent moves from a web page to a phone line.
Why it mattersTelephony breaks voice agents in ways a web demo never surfaces.

DeepSeek V4 Pro arrives in Perplexity Computer on US-hosted infrastructure, scoring 0.359 on the WANDR research benchmark at $0.75 per task, 62% below the next model on the cost-performance frontier.
Why it mattersDeepSeek V4 Pro is now reachable from US-hosted infrastructure inside Perplexity Computer at $0.75 per task, 62% cheaper than the next model on the cost-performance frontier, which makes it viable for bulk agent work.

GLM-5.3 is now available via API and partner gateways at the same price as GLM-5.2, positioned for coding, defensive cybersecurity, and long-horizon agentic workloads, with third-party providers already integrating it at roughly half the benchmark cost of frontier closed models.
Why it mattersGLM-5.3 is live via API at GLM-5.2 pricing, giving agentic coding and cybersecurity workloads a materially cheaper alternative to frontier closed models, with early adopters reporting real accuracy gains on internal benchmarks.

Claude can now send Gmail messages and manage Google Drive files through connectors, drafting and sending replies with a user-set approval gate. Available on all paid plans.
Why it mattersWrite-capable connectors with an approval gate are the pattern most agent products are converging on, and this is a shipped reference for how one lab drew that line.
Anthropic extends the 50 percent increase to weekly Claude Code limits through August 31, with a warning that model demand may make capacity tight and no commitment yet on making the change permanent.
Why it mattersWeekly limits govern how much agentic coding work a team can actually run, so a dated extension and a capacity warning both affect planning.
AI agents don't just reason anymore. They transact. Cloudflare's Monetization Ga
Cloudflare's Monetization Gateway lets content owners, API providers and MCP servers charge agents per request using x402.
Why it mattersAgent-to-service payment is an unsolved piece of agent infrastructure, and a per-request billing path that MCP server operators can adopt is something builders can act on directly.
LLMs answer drug questions from name patterns, not drug knowledge
Researchers replaced parts of drug names with invented strings to test whether Olmo 3 answers from the name's suffix or from drug knowledge.
Why it mattersA fluent answer about a named drug can come from a suffix pattern rather than knowledge of the drug. The nonce-substitution diagnostic gives engineers a way to test this in any medical or high-stakes entity-handling pipeline.

OpenAI says it has paused part of its frontier reinforcement-learning training until it can meet alignment, security and monitoring standards for new capability levels. Near-term model launches are unaffected, further-out releases are delayed, and the company will act unilaterally until shared indus
Why it mattersOpenAI says safety readiness, not just capability, now sets its release pace, so further-out models may arrive later while near-term launches continue.
Agent loops with external verification took a tokenizer trainer to production
Liquid AI had Claude Opus 4.5 and Codex build a BPE tokenizer trainer.
Why it mattersPassing unit tests on toy data hid every production failure.
As models become more capable, the risks associated with developing and testing
OpenAI paused reinforcement learning training on its latest deployment-bound models for two weeks while it hardened and red-teamed research environments.
Why it mattersA frontier lab halting its largest RL run is a direct signal about near-term model timing and about how cyber capability findings are now gating training.
Open Sourcing Evals For Open Weight Agents
Cline explains how it evaluates open-weight coding agents with Harbor and Terminal Bench, found its requests 20-30% heavier than efficient harnesses.
Why it mattersGives five hill-climbing heuristics and released traces for tuning a coding harness on open-weight models, where token overhead of 20-30% decides whether a cheaper model is actually cheaper.
How Much Memory Does Your Agent Actually Need?
IBM Research scaled its ALTK-Evolve memory system across eight models, from a 30B dense model to frontier systems.
Why it mattersTeams bolting memory onto agents usually assume more retrieved context is strictly better, and this shows accuracy and cost both turn on the dose and the delivery mode.
How AI Coding Agents Can Unlock Materials Simulation with NVIDIA ALCHEMI Toolkit
Benchmarking 45 agent-generated simulation pipelines found that prompt specificity changed code structure and reusability but not physical correctness.
Why it mattersA rare controlled measurement of what extra prompt detail actually buys when a coding agent writes domain-specific code.

Cua Driver's early-preview Computer History keeps an encrypted local record of app, capability and outcome metadata, so a new session or a different compatible agent can reuse a working route. It excludes screenshots, keystrokes, typed text, titles, URLs and paths.
Why it mattersAgents that reset or switch sessions can query an encrypted local record of which apps and capabilities worked, rather than retrying failed routes. It stores only fixed metadata, so it avoids retaining screenshots or typed text.

The Next Medium: Why Real-Time Interactive Video Changes Everything — Ahmed Ahres, Reactor
The case that real-time generative video is a change of medium rather than a speedup, with the consequences that follow.
Why it mattersIf you are building on video models, none of the batch serving playbook carries over to interactive generation.

Infra behind Krea 2: How to train and serve at scale — Gabriel Jorge Menezes, Krea.ai
An infrastructure lead on training at cluster scale.
Why it mattersConcrete metrics and failure modes for anyone operating large training clusters, including how to keep a site up while training holds priority.
We're making Git hosting more reliable, performant, and scalable. This post trac
Cursor traces twenty years of Git hosting design and explains why it operates its own storage layer, Origin, as a database rather than a filesystem.
Why it mattersAnyone running agents against many repositories at once hits the same Git scaling limits, and this documents one team's design and operational reasoning in detail.
Anthropic has opened Claude Cowork to mobile and web across every paid plan, taking the agentic workspace beyond the desktop application.
Why it mattersThe agent workspace is now reachable from a phone and browser, which changes where and when work can be handed to it.
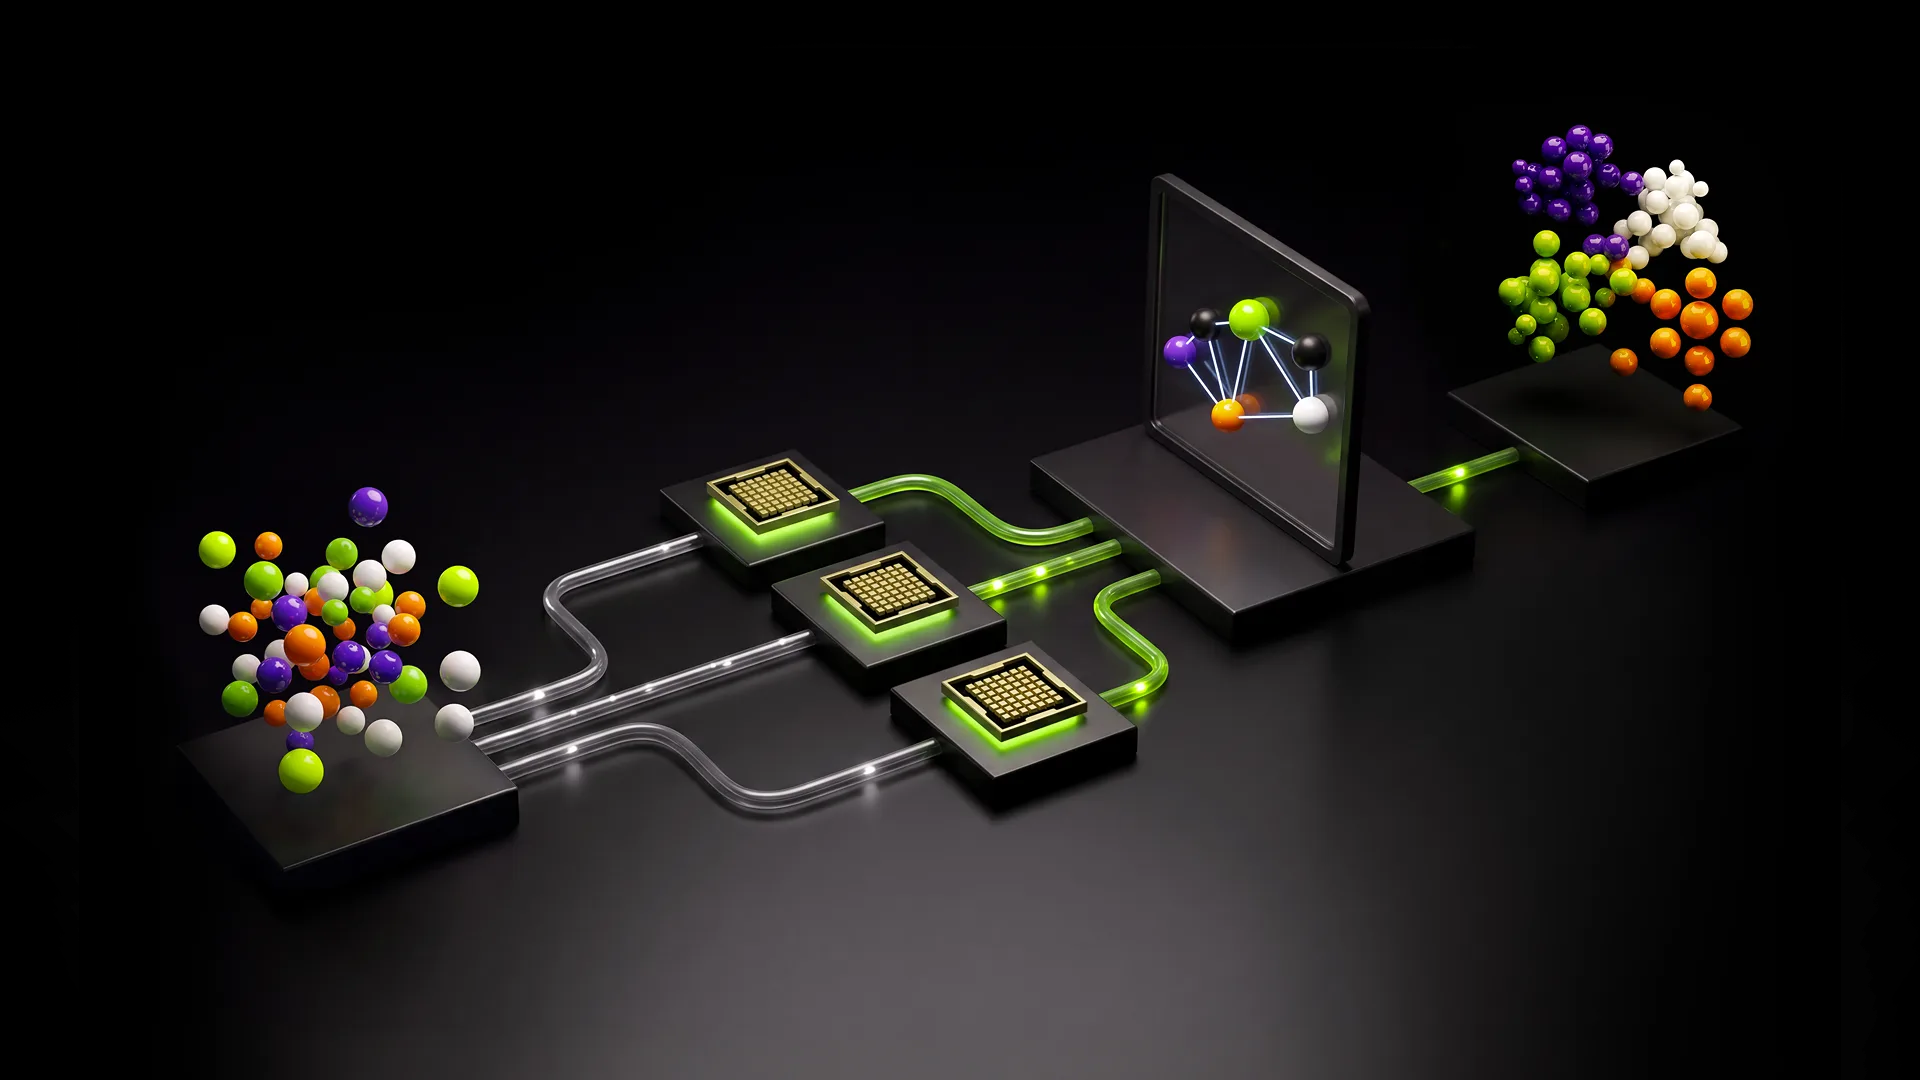
Run Massive-Scale UMAP in Minutes Using Multiple GPUs—Without Losing Accuracy
cuML and cuVS 25.06 distribute UMAP's all-neighbors kNN construction across GPUs by partitioning into balanced clusters, computing local graphs, then merging.
Why it mattersEmbedding-space analysis at hundred-million-vector scale drops from an overnight job to minutes, and the partition-and-merge design keeps embedding quality rather than trading accuracy for throughput.
➤ Leaderboard: ➤ Methodology: ➤ Stirrup, our open-source agent harness: Search A
Artificial Analysis benchmarks 15 search APIs from 7 providers inside a fixed agent harness — same model, same tasks, only the search tool varies.
Why it mattersChoosing a search API for an agent has been guesswork. This holds model and harness fixed so quality, blended cost and added latency are comparable — including how much a weaker provider costs you in extra model tokens.

Benchmark results place two search providers on the cost-quality frontier for agent tasks, with one scoring 73 at 7.5 cents per task but the slowest completion time, and another reaching 75 for 12 percent more.
Why it mattersSearch provider choice moves both agent answer quality and total task cost, and this puts numbers on the tradeoff.
Artificial Analysis launched a Search Index scoring seven search API providers inside its open-source Stirrup agent with one fixed model. It averages DeepSearchQA, BrowseComp and AA-Omniscience and reports cost and time per task. Parallel, Exa and Firecrawl lead, against a 33 no-search baseline.
Why it mattersWith model and harness held constant, search providers differ by up to ten index points. A pricier but more focused tier can cut total cost per task by shrinking model token use, so per-call price and latency are poor selection criteria.
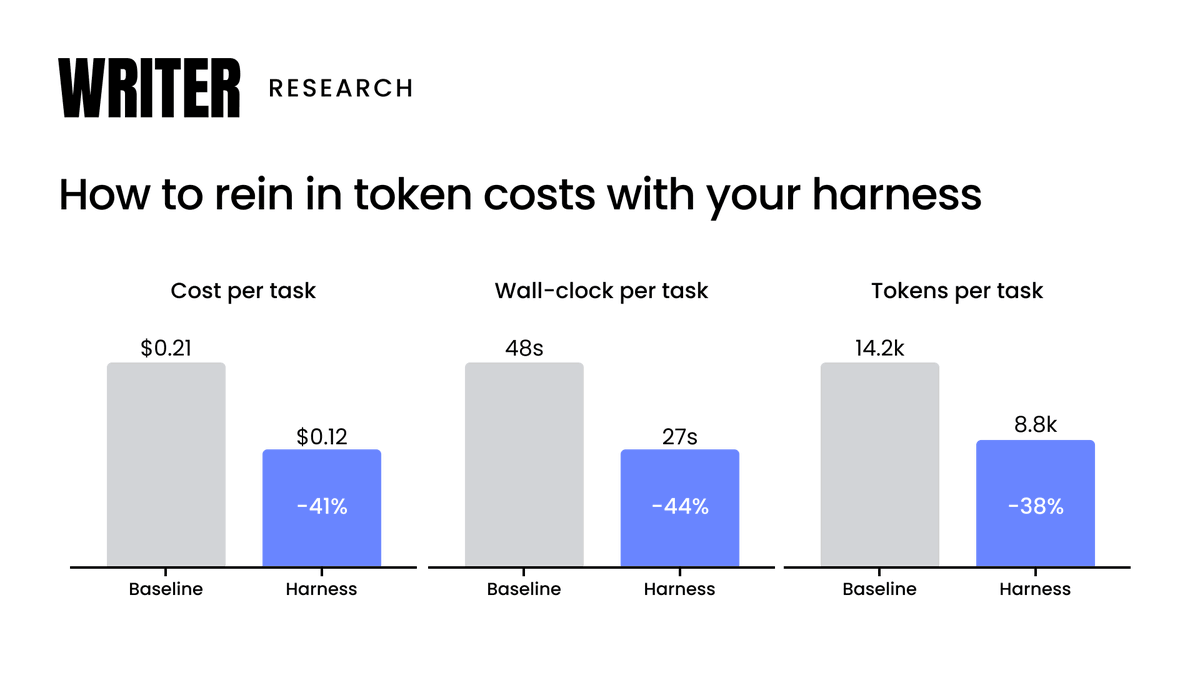
Harness Design Cut Agent Cost 33-61% Across Six Models
Writer benchmarked six models on 22 tasks against a naive harness and a token-efficient one built on cache-stable prompts, incremental compaction, context offload, zero-token waiting and retry limits.
Why it mattersAgent cost is dominated by input tokens, so cache hit rate matters most. Keeping a byte-stable prompt prefix, compacting incrementally and bounding retries cut cost 33-61% across six models in Writer's tests, with quality parity.

Generative Video at the Speed of Light — Keegan McCallum, uRun
Ten dollars now buys about three hours of continuously generated video.
Why it mattersCurrent cost and latency numbers for interactive video generation, plus the serving architecture it demands.
Introducing LangSmith Tuned Evaluators They automatically score agent behavior i
LangSmith adds Tuned Evaluators, small tuned models that score production agent traces automatically, starting with Perceived Error.
Why it mattersOnline evaluation of production agent traces is usually priced out by frontier-model judges, and a tuned small model that claims better accuracy at a fraction of the cost changes that calculus.
Perplexity Computer is now addressable by email. Send, forward or cc its address on a thread and the request runs as a regular session visible on web and mobile, with the same audit trail as in-app tasks. Available to all Computer users.
Why it mattersAgent tasks can now start from any email thread by cc'ing the agent, with each run logged as a normal session with the standard audit trail. Email becomes a trigger surface for delegation without opening the app.
Full breakdown: Claude-only apps often wait until the host speaks the new revisi
MCP spec 2026-07-28 removes the initialize handshake and session header, making each tool call a self-contained POST any replica can answer.
Why it mattersIf you run an MCP server, protocol sessions and sticky routing are gone: a dropped response is now a full retry, so every write-or-charge tool needs a caller-supplied idempotency key to avoid double execution.
An index of the vibe-coding frontier. Corrections welcome.