CoPaRe: StepFun open sources coordinated parallel reasoning
- Source
- x.com
- Date

💥 Karpathy’s 2025 LLM summary puts RL with verifiable rewards (RLVR) first — hinting at a new scaling law. 🤗 We just open-sourced CoPaRe (Coordinated Parallel Reasoning): scale test-time compute, generate longer reasoning chains, and unlock big gains. 🔢 An 8B model beats GPT-5 Thinking on math and it’s already gaining strong traction on HuggingFace. 🚀 Dive in and try it now! https://t.co/hDgopViIuS
Context
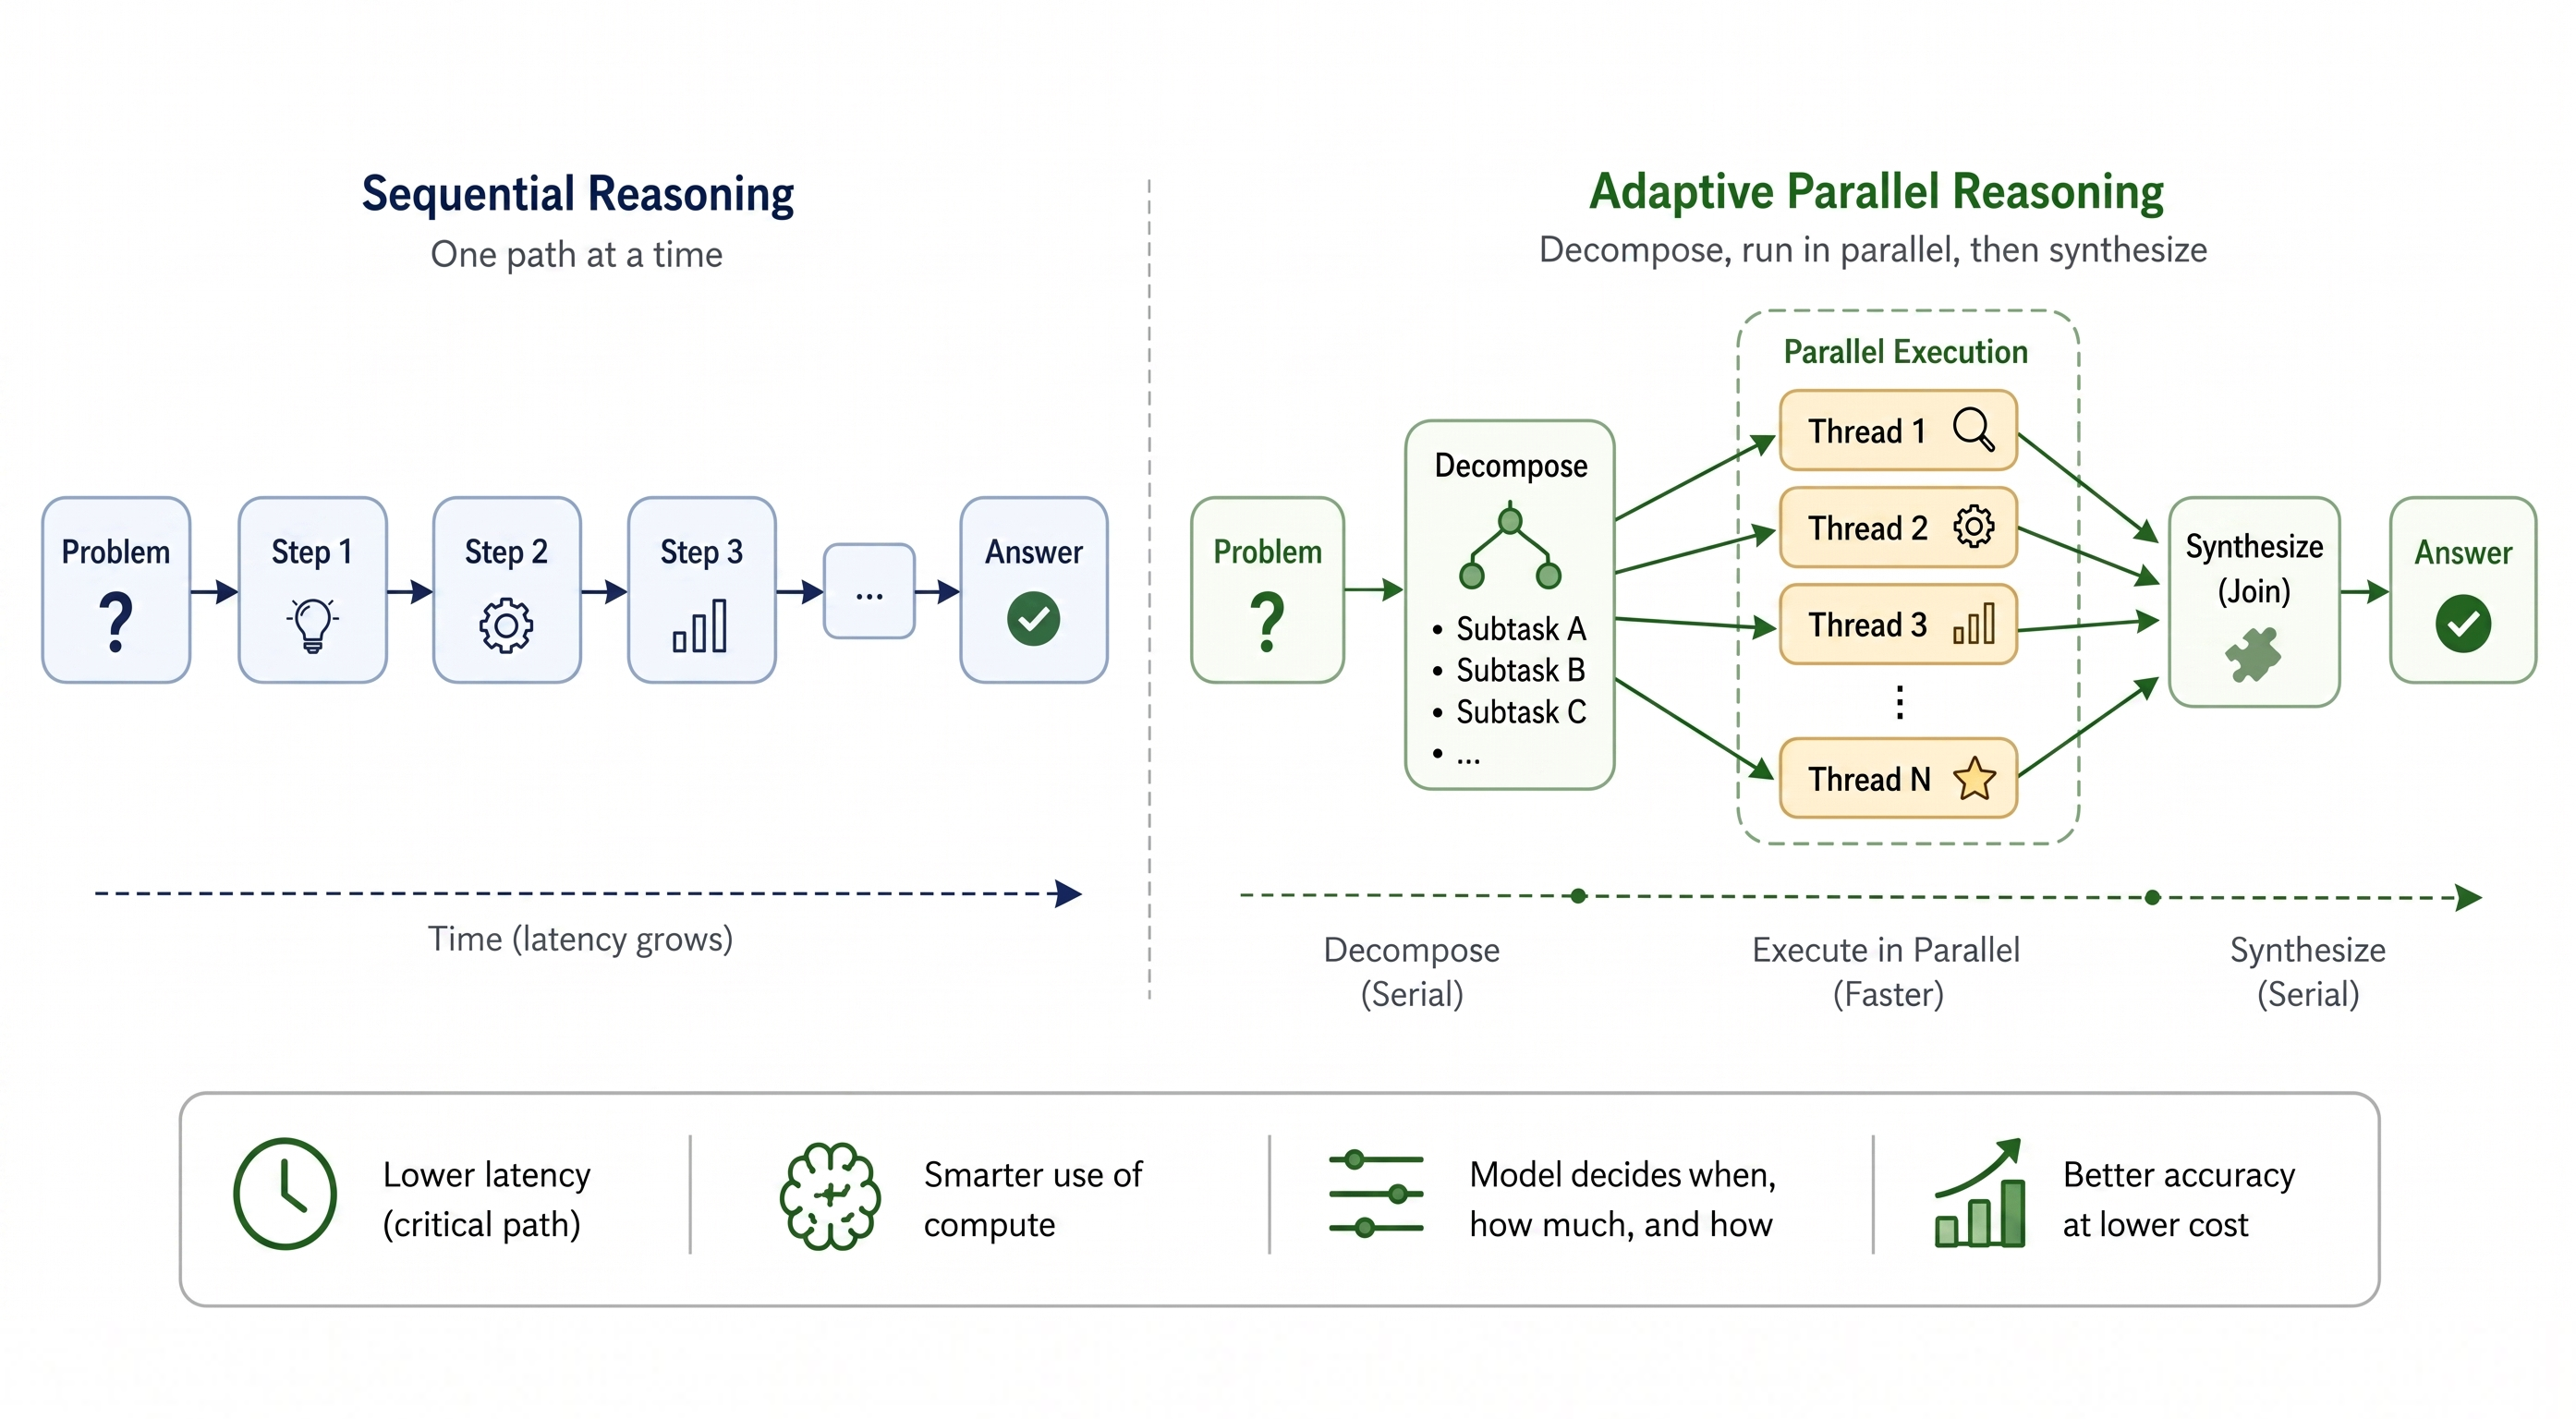
Per StepFun's post, CoPaRe, or Coordinated Parallel Reasoning, is an open-sourced method for scaling , letting a model spend more computation at the moment it answers a question rather than only during training, specifically by generating longer, coordinated reasoning chains. StepFun frames it against a broader trend it credits to reinforcement learning with verifiable rewards, a training approach that rewards a model based on whether its answer to a checkable problem, such as a math result, is actually correct.
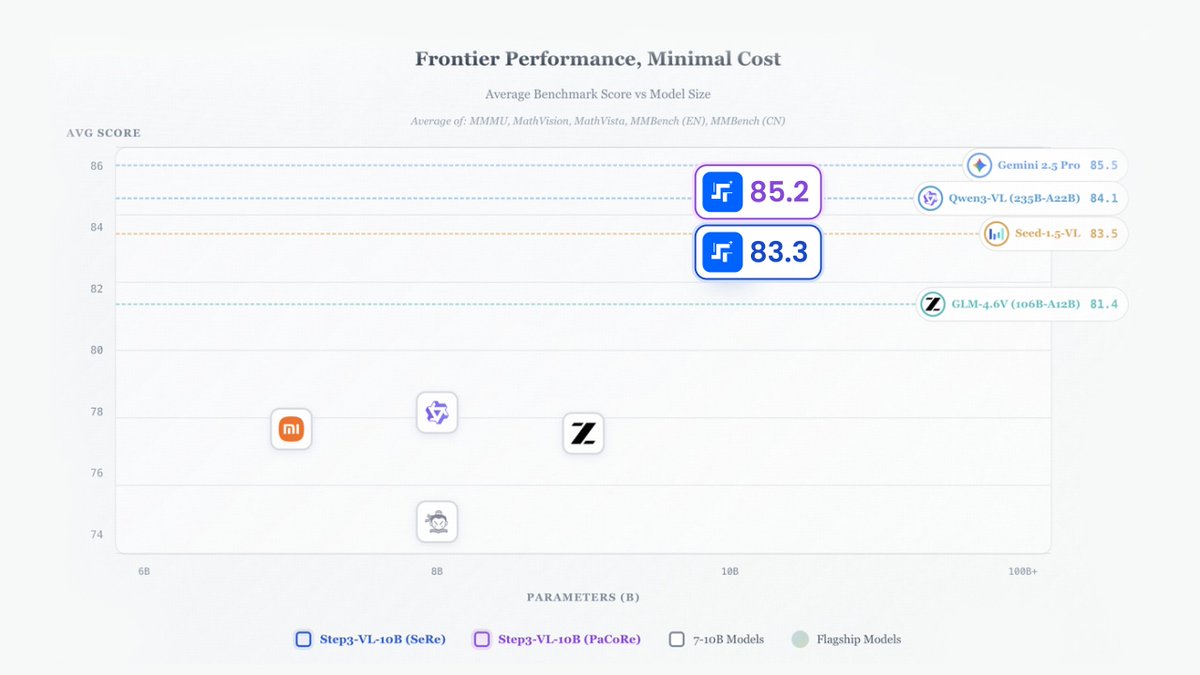
StepFun reports that an 8-billion-parameter model using CoPaRe outperformed GPT-5 Thinking on math problems, a comparison the company made itself rather than an independent , though the code was released publicly so the claim can be checked. StepFun later applied the same underlying parallel-reasoning idea at time in a separate compact vision-language release, Step3-VL-10B (Step3-VL-10B), and in its audio Step-Audio-R1.1, which also allocates extra test-time compute specifically to reasoning about audio (Step-Audio-R1.1).
- test-time compute — Spending more computation when the model answers — thinking longer, trying multiple attempts — to buy accuracy without training a bigger model.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
- inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
- reasoning model — A model trained to think — generating extended internal reasoning before answering — trading time and tokens for accuracy on hard problems.
 postStepFun Open-Sources Step Code, a CLI Coding Agent Benchmarked on Terminal-Bench
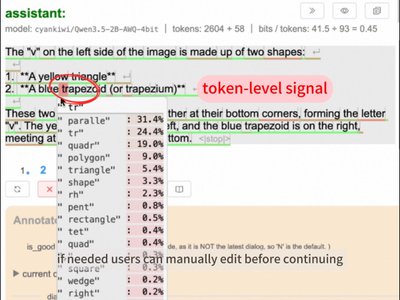 postStepFun Open-Sources onPanda, Its Internal LLM Annotation and Debug Tool
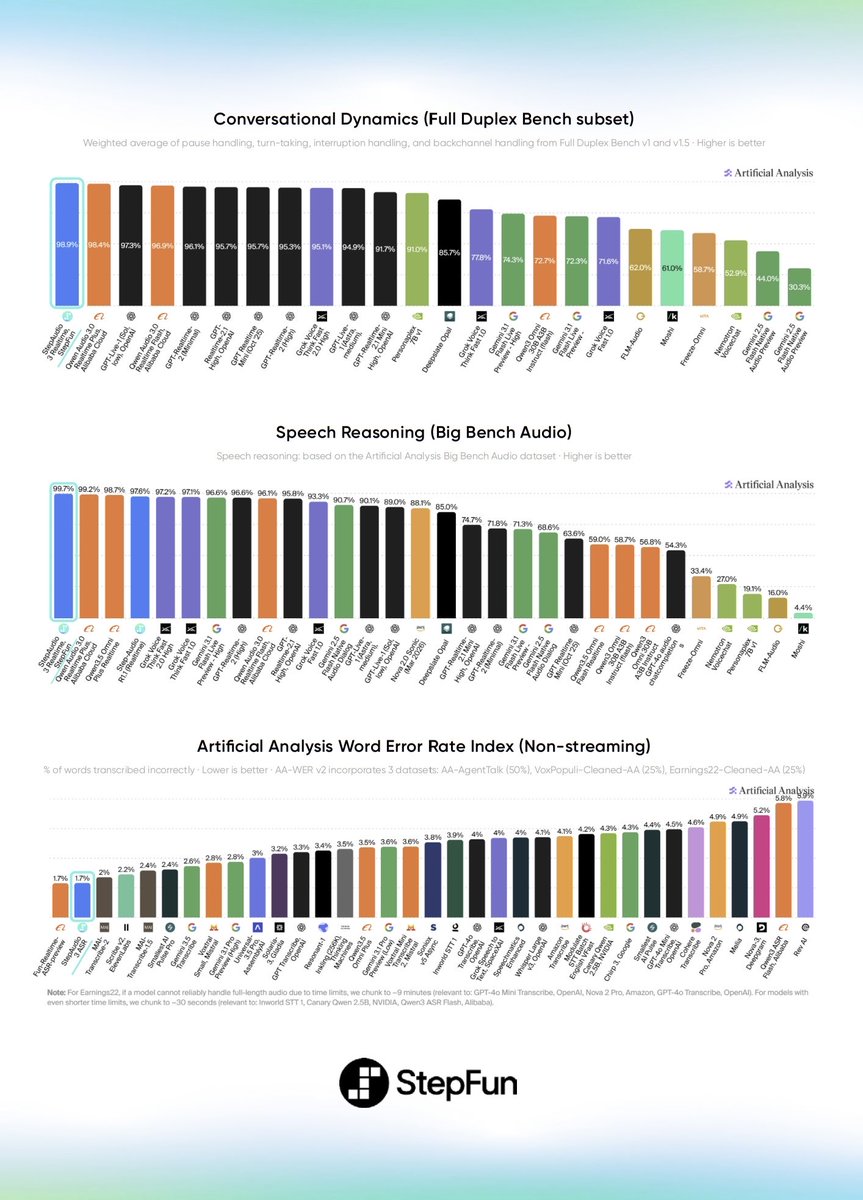 postStepFun debuts StepAudio 3 voice model family, tops real-time benchmarks
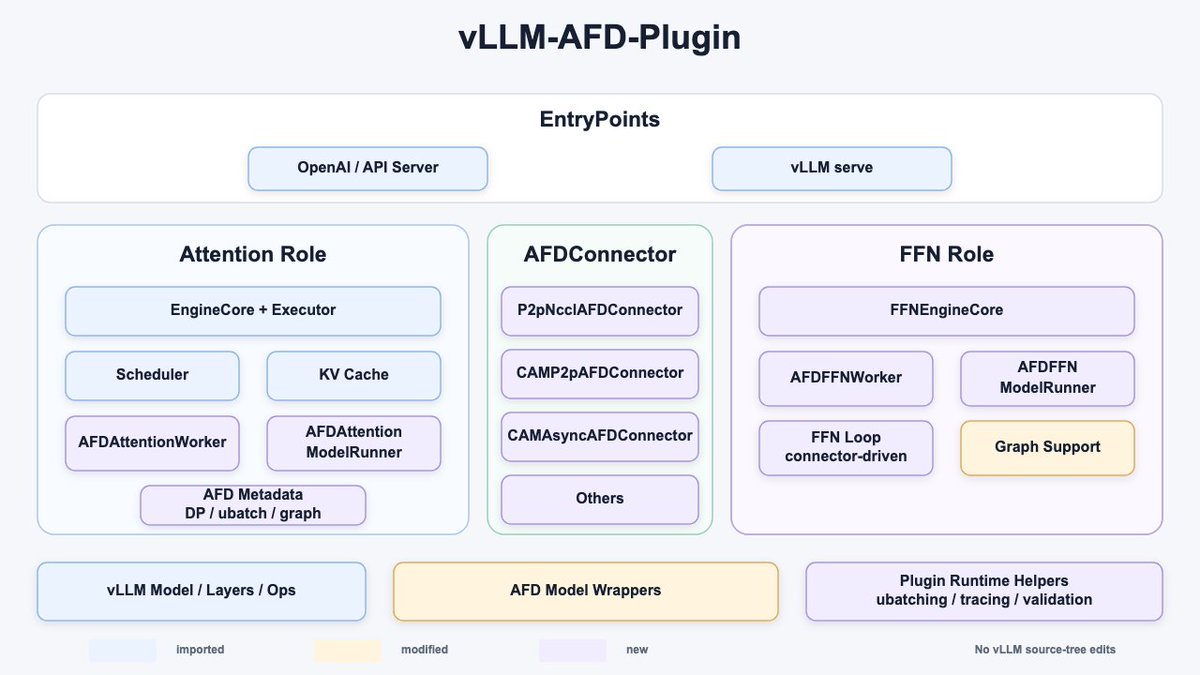 postvLLM gains an experimental Attention-FFN disaggregation plugin for MoE
Checking sign-in…
Loading comments…