GLM-5.1-highspeed debuts at 400 tokens per second
- Source
- x.com
- Date

GLM-5.1-highspeed is coming, 400 tokens per second. Very expensive, but bring a new possibility.


Context
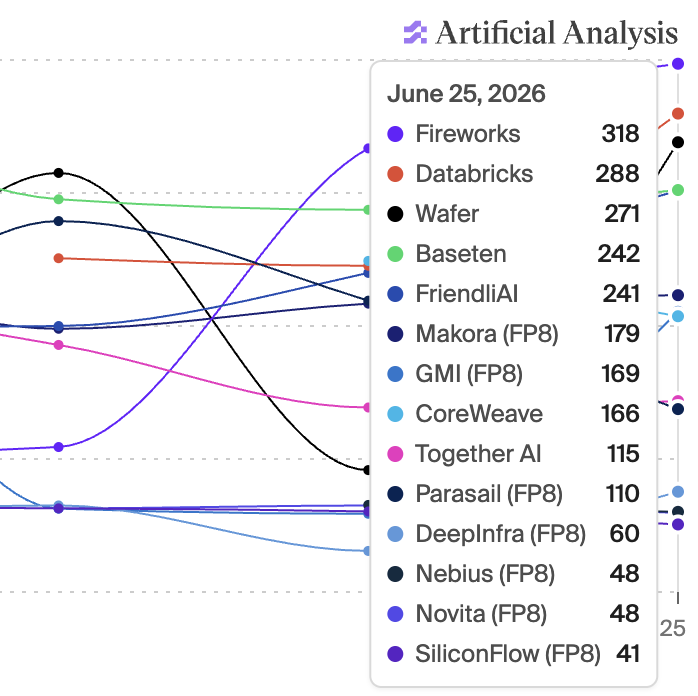
Zhipu, now Z.ai, announced GLM-5.1-highspeed, a version of its GLM-5.1 model tuned to generate text at about 400 per second, well above typical serving speeds for a model of similar size. Jie Tang's announcement says the variant costs significantly more to run than standard GLM-5.1 but 'brings a new possibility,' without specifying which workloads benefit most; the likely use case, based on the tradeoff described, is loops where waiting on token generation is the bottleneck rather than model quality. No independent throughput measurement or pricing detail accompanies the tweet. The throughput race continued into the summer, when providers pushed GLM-5.2 serving speeds higher still.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
Checking sign-in…
Loading comments…