Vals AI: higher reasoning effort has diminishing returns on math proofs
- Source
- x.com
- Date
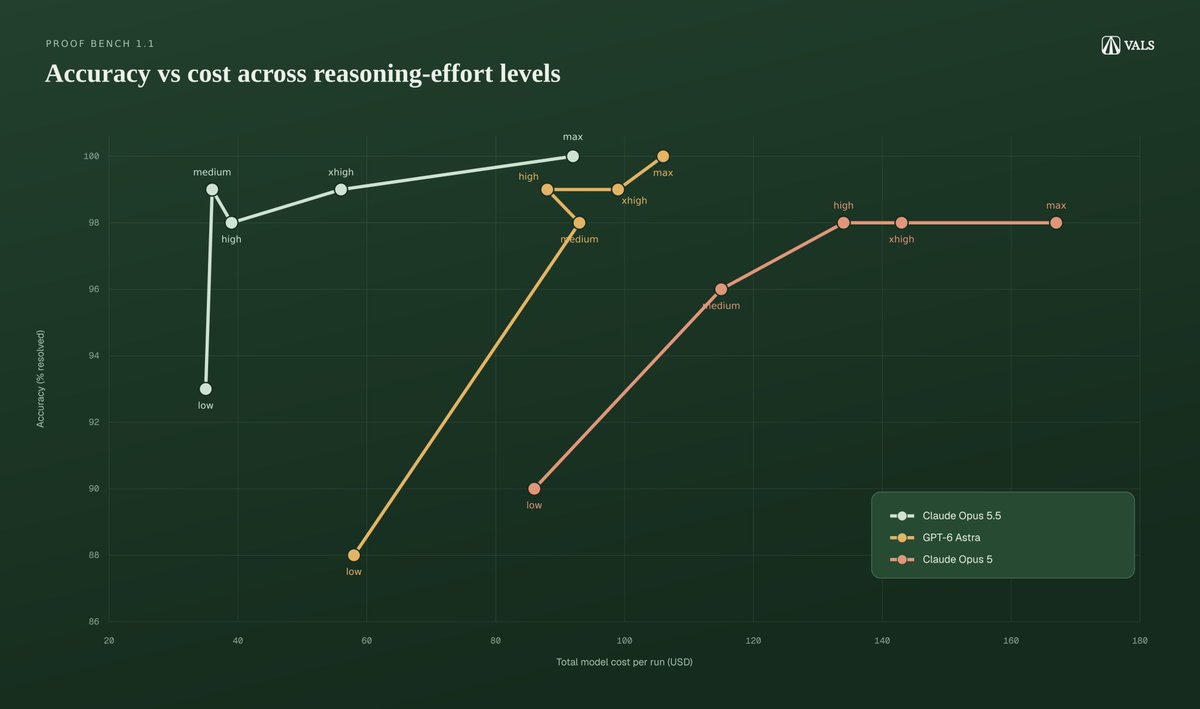
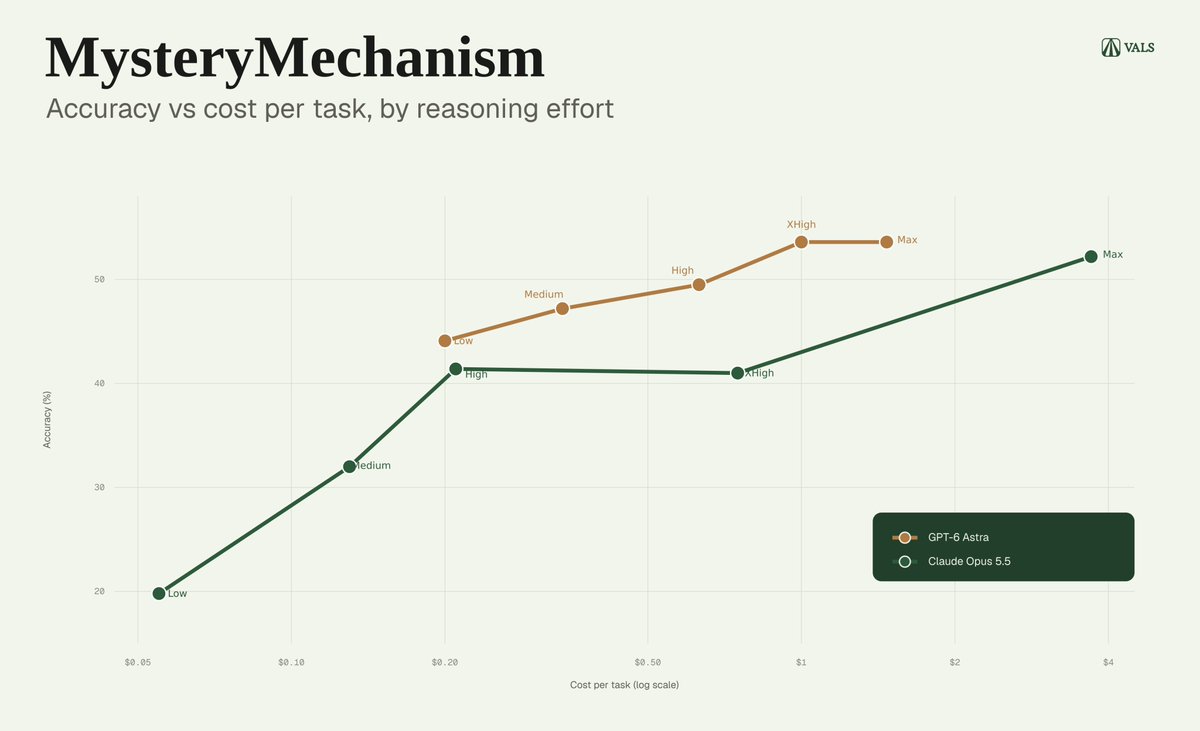
Vals AI ran its Proof Bench math suite across reasoning effort settings and reports that the largest step in accuracy comes from moving low to medium. Past that point the curve flattens. Opus 5.5 scored 99% at medium effort, at a fraction of the cost of running it at max, and Vals notes that some other models stop improving no matter how much effort is applied. The practical reading is that effort is a cost dial with a knee, not a quality dial that keeps paying out. Anthropic's Thariq published a same-day explainer on what effort changes inside Claude Code: higher settings spend more on verification and edge-case testing, while low and medium favor faster iteration, illustrated with Terminal-Bench 3.0 results. Taken together, the two posts suggest a default of medium for well-specified work, with high or max reserved for tasks where extra verification is the point. Teams paying for max on every call should measure their own knee before assuming the extra spend buys accuracy.

How does "thinking harder" change how models perform on math proofs? We ran GPT-6 Astra, Opus 5, and Opus 5.5 on every reasoning level: low, medium, high, xhigh, and max on our benchmark, Proof Bench v1.1.
Context
Vals AI's Proof Bench v1.1 comparison shows how scores on a math-proof change with reasoning effort, the setting for how much a model thinks before answering. In its attached chart, Anthropic's Claude Opus 5.5 resolves 99% of problems at medium effort and 100% at max, while total model cost per run rises from roughly $36 to roughly $92, more than double.
The curve depends on the model: Claude Opus 5 stays at 98% from high through max effort while its cost climbs from roughly $134 to $167. The chart shows no error bars, so small differences may not be meaningful. What it supports is comparing effort settings on the actual task instead of assuming the maximum setting is worth its cost.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
Checking sign-in…
Loading comments…