Paradigma releases Limite 1B - Violetto, a small open-weight math reasoning model
Source
paradigma.inc
Author
Paradigma
Date
Context
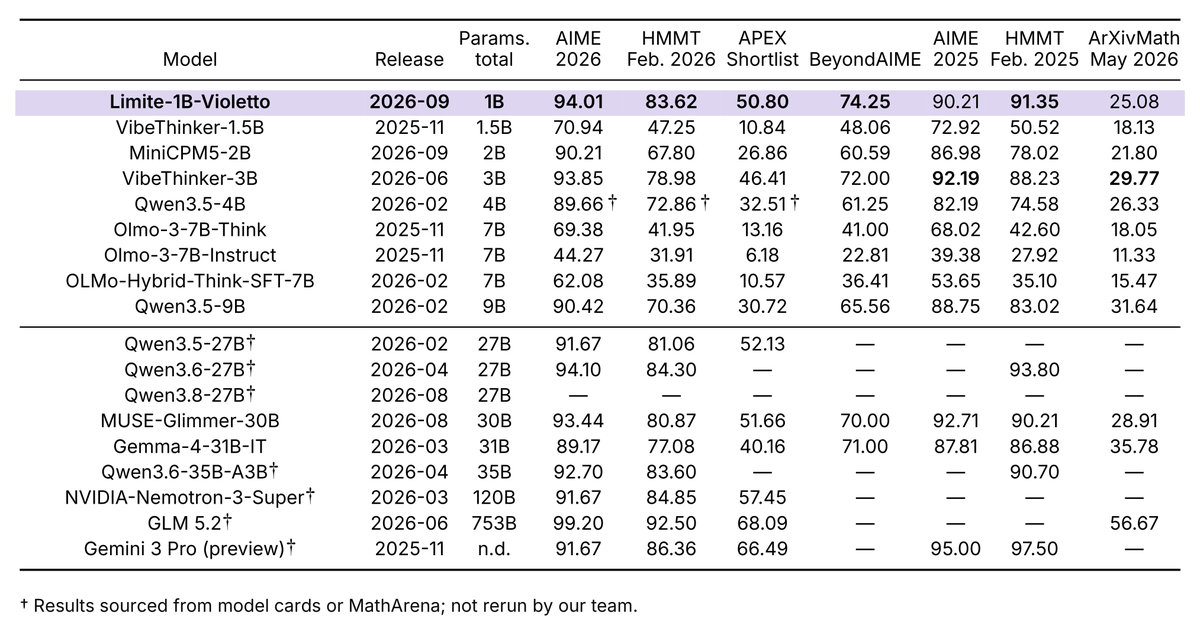
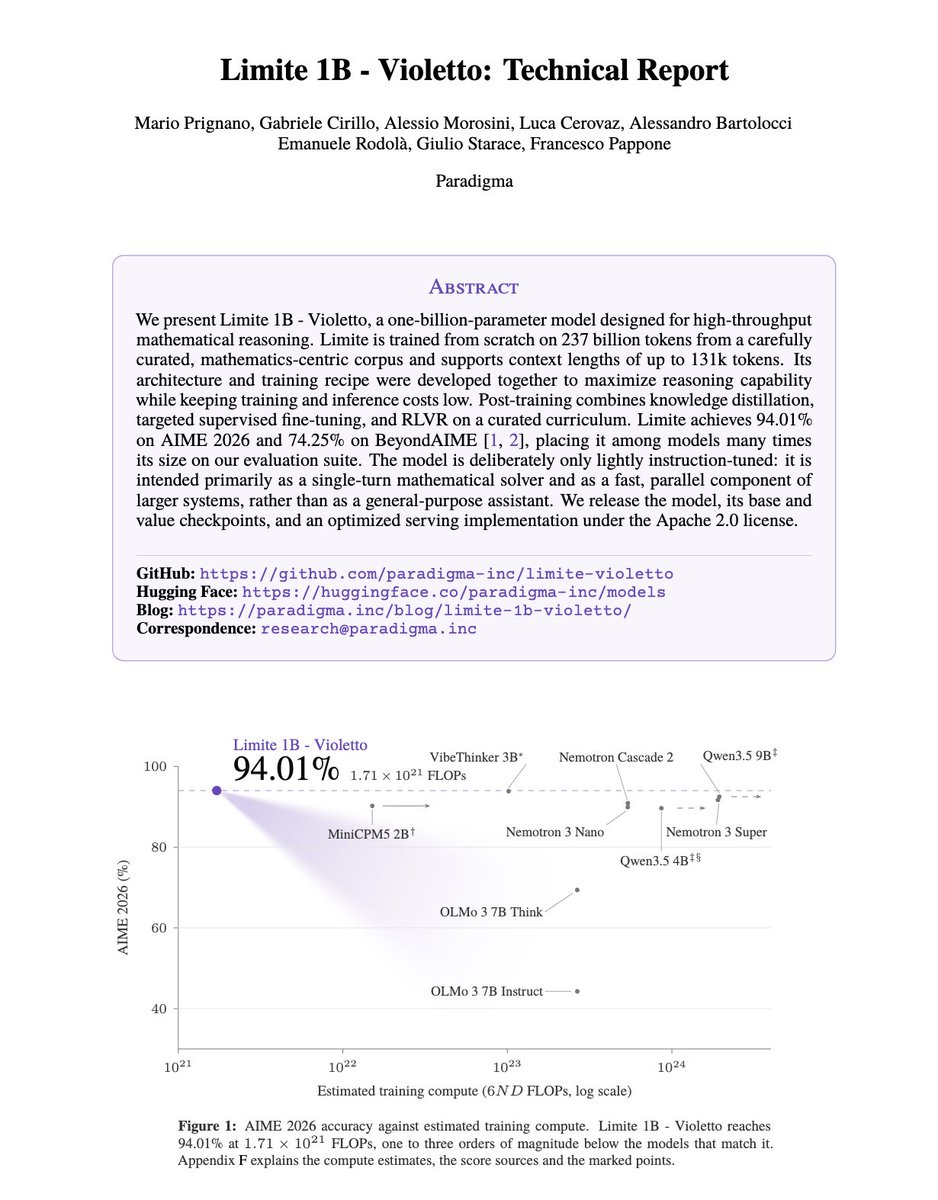
Paradigma's Limite 1B - Violetto is a small language model designed for mathematical problem solving in individual prompts. The company says it combines curated training data with supervised examples and reinforcement learning, while deliberately keeping general instruction tuning light. That specialization affects how the model should be used. The release article includes examples where it replaces the user's question with a different mathematical task, alongside selected mathematical solutions. Its intended role is therefore a specialized math model whose answers require checking against the original problem, rather than a dependable conversational interface for arbitrary requests.
Key takeaways · AI-distilled
Limite is a dense 1B transformerThe neural network architecture behind modern AI models, built on attention — letting every word directly consider every other word in parallel.Full definition → trained from scratch with a 131k-token context windowThe maximum amount of text a model can consider at once — its working memory for the current conversation or task.Full definition →. Paradigma credits its sample efficiency to data curation and an architecture drawn from community pretrainingThe first, biggest phase of building a model: training it on enormous amounts of text so it learns language, facts, and reasoning in general.Full definition → speedrun competitions.
Post-training mixed synthetic data generation, curated SFT and RL. Paradigma kept instruction tuning deliberately light to test whether a model needs an assistant persona to perform well, so Limite is meant for single-turn answers.
Paradigma lists limitations in instruction following and scope: Limite can lose track of what a prompt asks and reinterpret it as a different, often mathematical, task.
Alongside Apache-2.0 weights, the release includes the evaluations, a value model used during training, and a custom vLLM inference plugin. Paradigma says a technical report is coming soon and that Limite is the first of several models aimed at science and autonomous research.
Terms in this piece · Glossary
reasoning model — A model trained to think — generating extended internal reasoning before answering — trading time and tokens for accuracy on hard problems.
transformer — The neural network architecture behind modern AI models, built on attention — letting every word directly consider every other word in parallel.
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
pretraining — The first, biggest phase of building a model: training it on enormous amounts of text so it learns language, facts, and reasoning in general.