Gemini 3.8 Flash TTS takes the top spot for pronunciation robustness
- Source
- Artificial Analysis
- Date

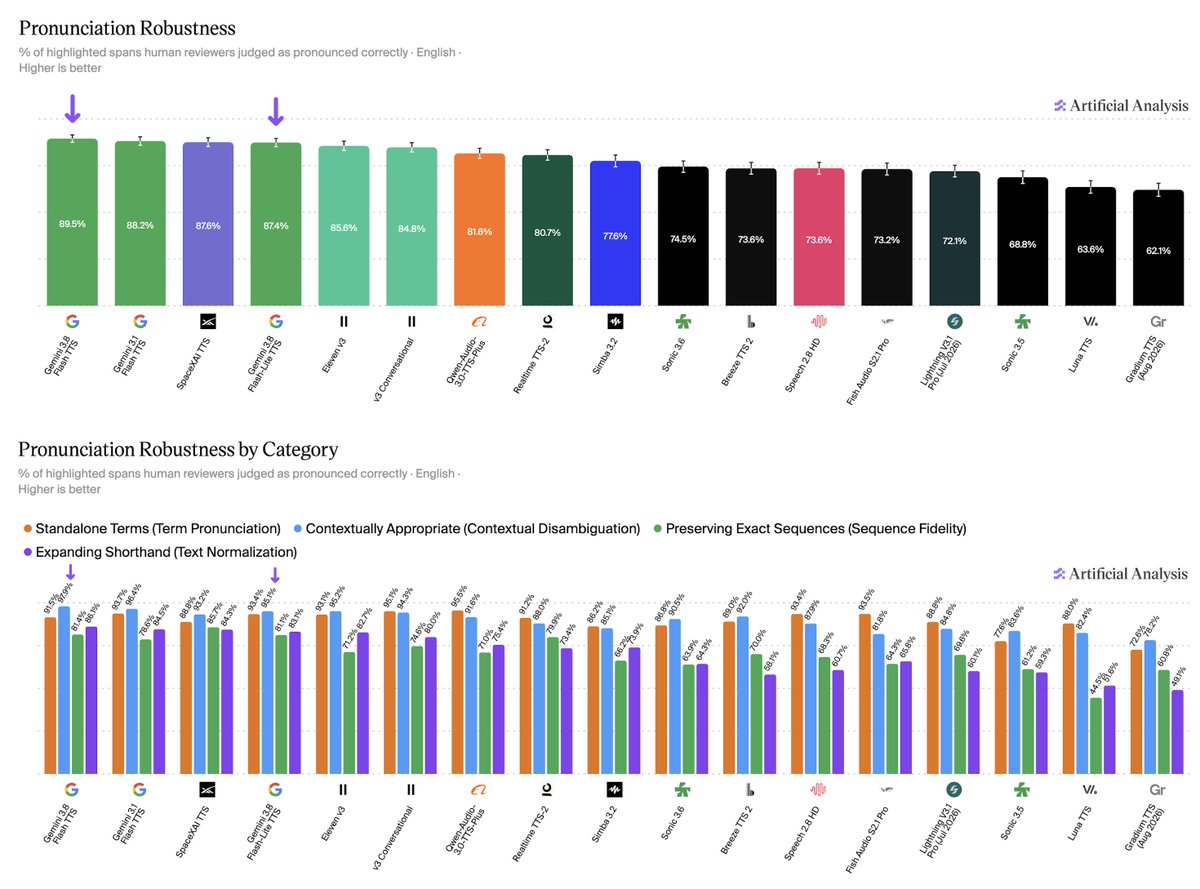
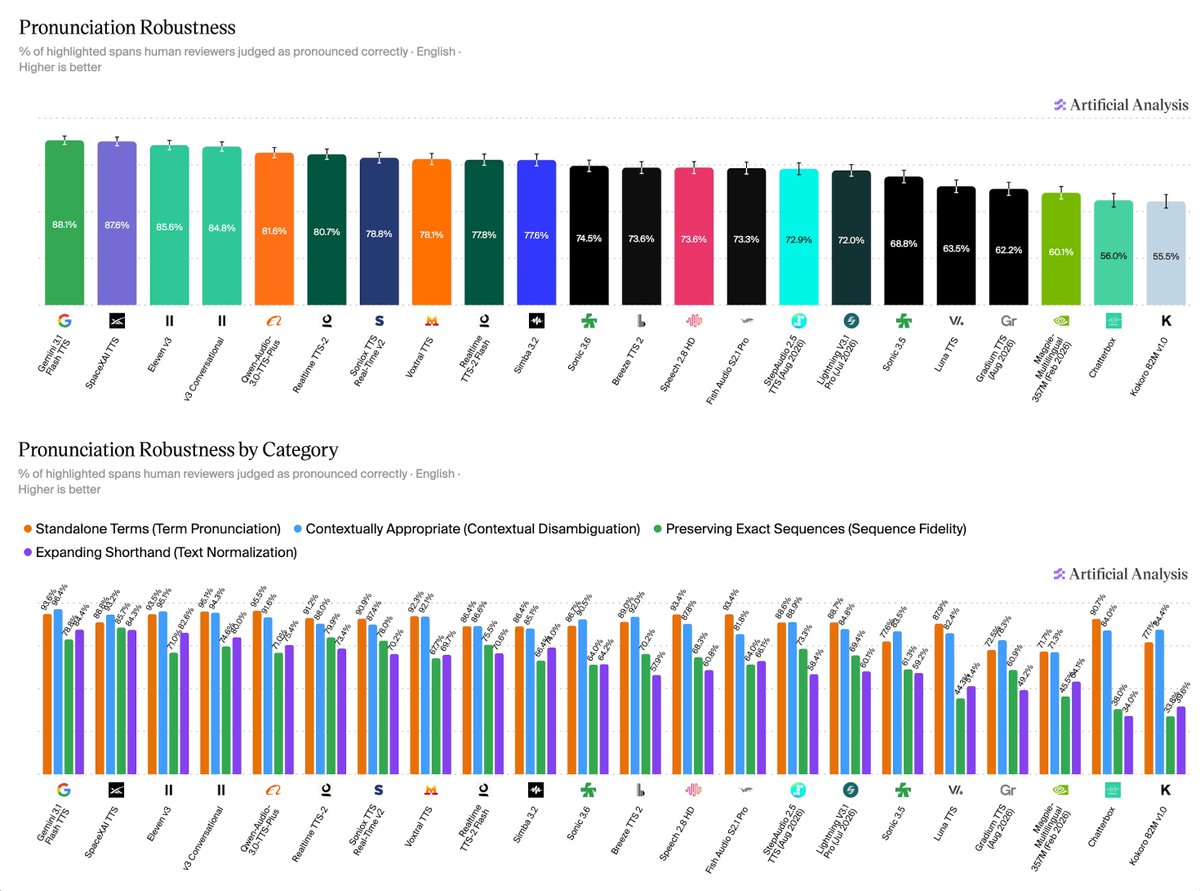
Gemini 3.8 Flash TTS takes the #1 spot on the Artificial Analysis Pronunciation Robustness benchmark at 89.5%, ahead of Gemini 3.1 Flash TTS at 88.2%, SpaceXAI TTS at 87.6%, and Gemini 3.8 Flash-Lite TTS at 87.4%. Gemini 3.8 Flash TTS leads on Contextually Appropriate pronunciation at 97.9% and Expanding Shorthand at 86.1%, while SpaceXAI TTS leads on Preserving Exact Sequences at 85.7% and Qwen-Audio-3.0-TTS-Plus leads on Standalone Terms at 95.5%. Listen to examples from our Pronunciation Robustness benchmark below ⬇️
Example audio generated by Gemini 3.8 Flash TTS for the Contextually Appropriate category of speech generation including "St. Mary's is on Church St.", "That excuse does not excuse the delay.", and "The instructions say to wait 30 sec. before reading sec. 4."

Example audio generated by Gemini 3.8 Flash TTS for the Expanding Shorthand category of speech generation including "Median latency was 12 ms, reported as p50.", "Take the elevator to the 3rd Fl and turn left.", and "The Class of '09 reunion is on 9/9, of all days."

Compare Text to Speech models across all benchmarks: https://t.co/gdkyEw7YDB Learn more about our Pronunciation Robustness Benchmark: https://t.co/mLJRAEFMYg
Context
Artificial Analysis's Pronunciation Robustness checks whether a text-to-speech model reads ambiguous or -dependent text the way a person would, for example reading '30 sec.' as 'seconds' rather than spelling out the abbreviation. Within that benchmark, Google DeepMind's newly released Gemini 3.8 Flash TTS leads on two of four sub-categories, per Artificial Analysis's breakdown: it scores highest on reading words whose correct pronunciation depends on context, at 97.9%, and on expanding shorthand like time and date abbreviations, at 86.1%. It doesn't lead on every category, though: SpaceXAI's TTS model stays ahead on preserving exact sequences such as codes or serial numbers spoken character by character, and Alibaba's Qwen-Audio-3.0-TTS-Plus leads on correctly pronouncing standalone technical terms. The split result means no model in Artificial Analysis's comparison is uniformly best at pronunciation; which one performs best for a given voice- or accessibility product depends on what kind of text that product mostly needs to read aloud.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.




Checking sign-in…
Loading comments…