Explains what SWE-bench Verified scores do and do not show: mostly simple Python bug fixes from few repos, with scaffold choice affecting results as much as the model.
Key takeaways · AI-distilled
Epoch's 2025 review describes SWE-benchThe standard benchmark for AI coding agents: real GitHub issues from real repositories, scored by whether the agent's patch passes the project's own tests.Full definition → as 500 tasks from 12 public Python repositories, primarily bug fixes. It tests repository navigation and patching, but covers a narrow slice of software engineering.
SWE-bench Verified checks that selected failing tests pass and selected passing tests stay green. A patch can satisfy those tests while introducing bugs elsewhere, so benchmarkA standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.Full definition → success is not proof that a change is safe to ship.
The five largest repositories supply over 80% of SWE-bench Verified tasks. Epoch warns that familiar public code and static historical issues create contamination risk and limit transfer to unfamiliar, closed-source projects.
SWE-bench Verified scores measure the model together with its AI agentAn AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.Full definition → tools, prompts and retry strategy. Epoch recommends inspecting single-trace pass@1 results because extra attempts can raise scores while also increasing evalA repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.Full definition → cost.
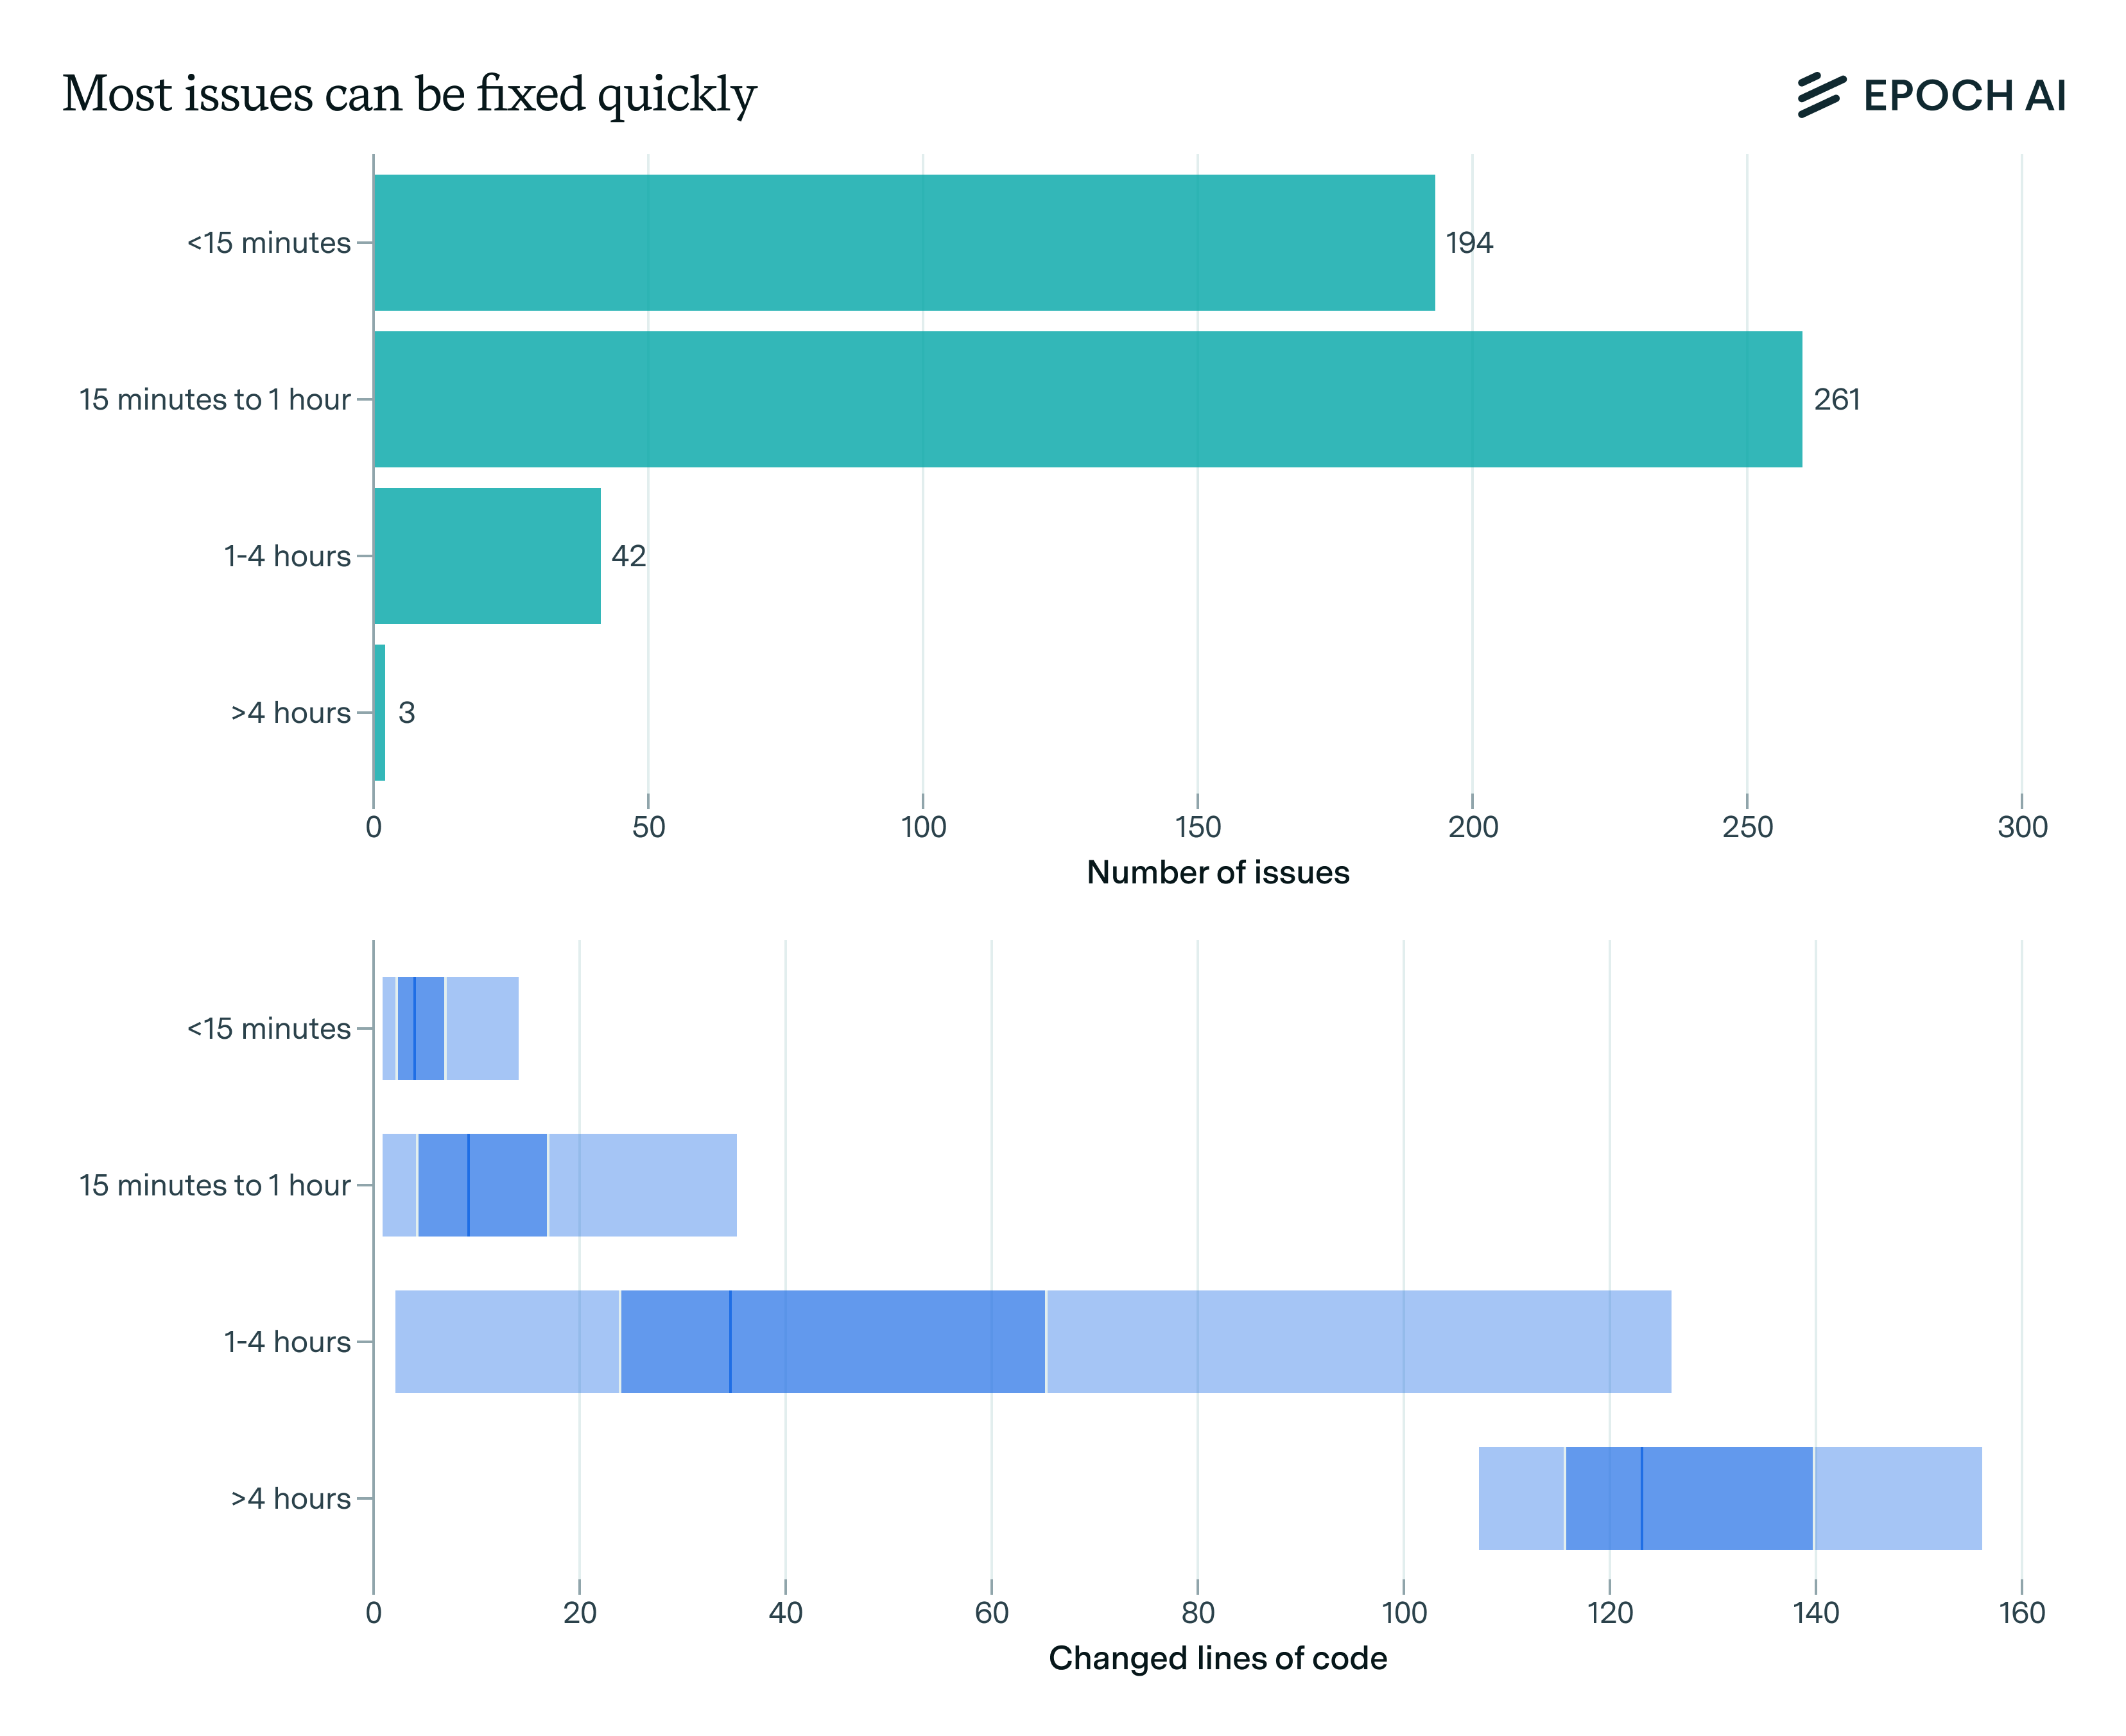
Annotators judged 91% of SWE-bench Verified issues solvable in under an hour by an experienced engineer familiar with the repository. Epoch notes that METR's small timing study challenged those estimates; they are not measured completion times.
Terms in this piece · Glossary
SWE-bench — The standard benchmark for AI coding agents: real GitHub issues from real repositories, scored by whether the agent's patch passes the project's own tests.
AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.