AA-3D benchmark ranks 21 models on agent-built 3D scenes
- Source
- x.com
- Date

We have measured intelligence. Now it's time to see it. We are launching AA-3D, our new benchmark for how well AI models build interactive 3D scenes. Each model works as an agent in an offline sandbox and turns a written brief into a three.js web page. A human panel of judges compares pairs of scenes built from the same brief without knowing which model made which. AA-3D details: ➤ 55 written briefs across seven domains, including landmarks, machines, living bodies, games, and space. Each brief says what the scene must show and how people should interact with it, and leaves the rest to the model ➤ Each model gets up to three hours and 250 turns. Its sandbox has Blender, Rapier physics, Python, a headless browser to test its own work, and a CC0 library of materials, 3D models, and characters ➤ Panelists spend at least 30 seconds with each scene before they vote. One comparison in every four is a validation check ➤ Over 10,000 counted votes from over 1,000 panelists rank 21 models by Elo, with 95% confidence intervals Key findings: ➤ Four models are statistically tied at the top: Claude Sonnet 5.5 (1194), Claude Opus 5.5 (1190), GPT-6 Astra (1165), and Claude Fable 5.1…

Context
AA-3D is a from Artificial Analysis that scores AI models on building interactive 3D scenes. People judge the results, not an automated checker. According to the launch post, each model works as an in an offline and turns a written brief into a three.js web page. The 55 briefs cover seven domains, including landmarks, machines, games and space. Each brief says what the scene must show and how people should interact with it. The model gets up to three hours and 250 turns, with Blender, Rapier physics, Python, a library of free assets and a headless browser for testing its own work. Human panelists then compare two scenes built from the same brief without knowing which model made which. They spend at least 30 seconds with each scene, and one comparison in four is a validation check. The rankings are Elo ratings, a chess-style score built from these head-to-head votes. They come from over 10,000 counted votes by more than 1,000 panelists.
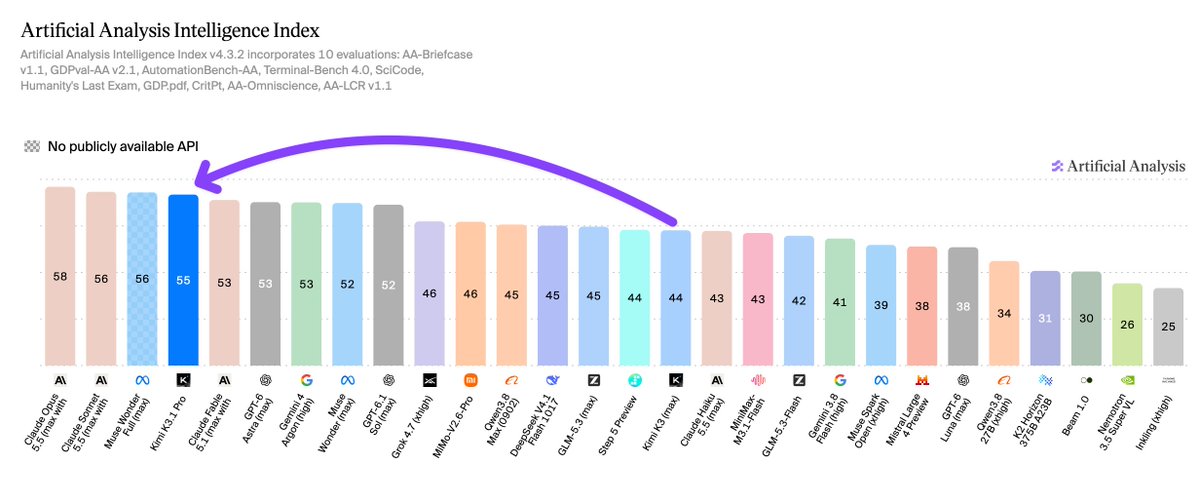
The main result is a cluster at the top, not a single winner. Artificial Analysis says Claude Sonnet 5.5 (1194), Claude Opus 5.5 (1190), GPT-6 Astra (1165) and Claude Fable 5.1 (1131) are statistically tied, because their 95% confidence intervals overlap. It also reports that AA-3D scores track its general Intelligence Index closely, at about 18 Elo per index point (Pearson 0.92). The best open-weights models, Kimi K3 and MiMo-V2.6-Pro, rank 11th and 12th, more than 200 points behind. Cost per scene ranges from $0.20 to $32.08, and the cheapest model, GPT-6 Luna, places eighth. The post says more detail follows in the thread, but the collected thread contains only this opening post, and the attached video could not be read. Artificial Analysis also published an AA-3D announcement article on its own site covering the same launch.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- sandbox — An isolated environment where AI-generated code or agent actions run without being able to touch anything real.
Checking sign-in…
Loading comments…