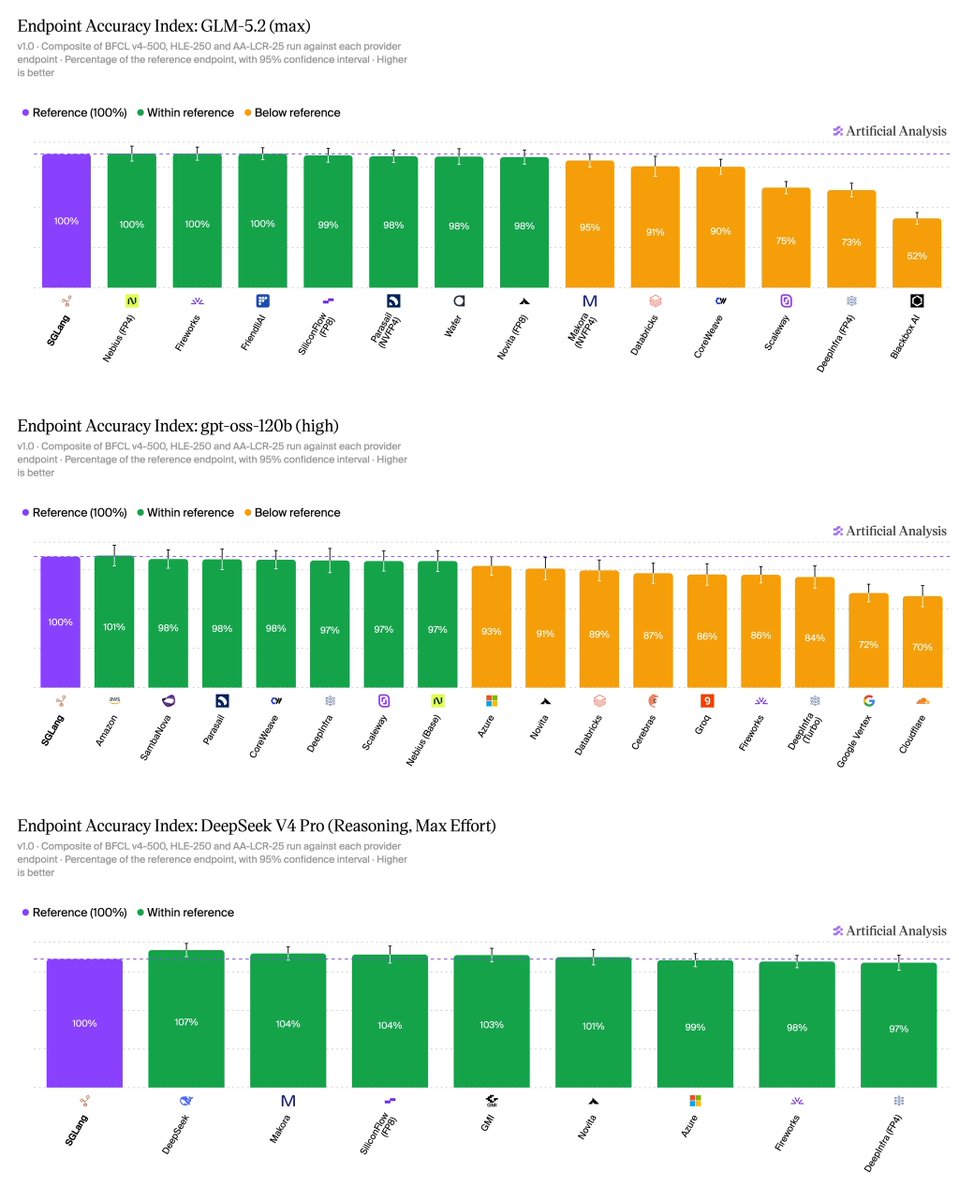
The same open model can score half as well or worse depending on the provider, due to output tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition → limits and tool call handling, so choose endpoints on accuracy and not only price and speed.
Key takeaways · AI-distilled
The Endpoint Accuracy Index compares each provider with a self-hosted deployment of the official weights. It equally weights tool useA model's ability to call external functions — run code, search the web, edit files — instead of only generating text.Full definition →, scientific reasoning and long-context windowThe maximum amount of text a model can consider at once — its working memory for the current conversation or task.Full definition → recall.
The Endpoint Accuracy Index tests reference parity with a 95% confidence interval that accounts for uncertainty in both deployments. Results carry measurement dates because provider configurations can change.
The reported gaps show why matching model names is insufficient. Output limits can interrupt reasoning, and tool-call formatting can reduce accuracy even when providers serve the same weights.
Terms in this piece · Glossary
tool use — A model's ability to call external functions — run code, search the web, edit files — instead of only generating text.
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.