The Future of Meta Superintelligence: A 1 Year Progress Update
- Source
- newsletter.semianalysis.com
- Author
- Max Kan
- Date
Context
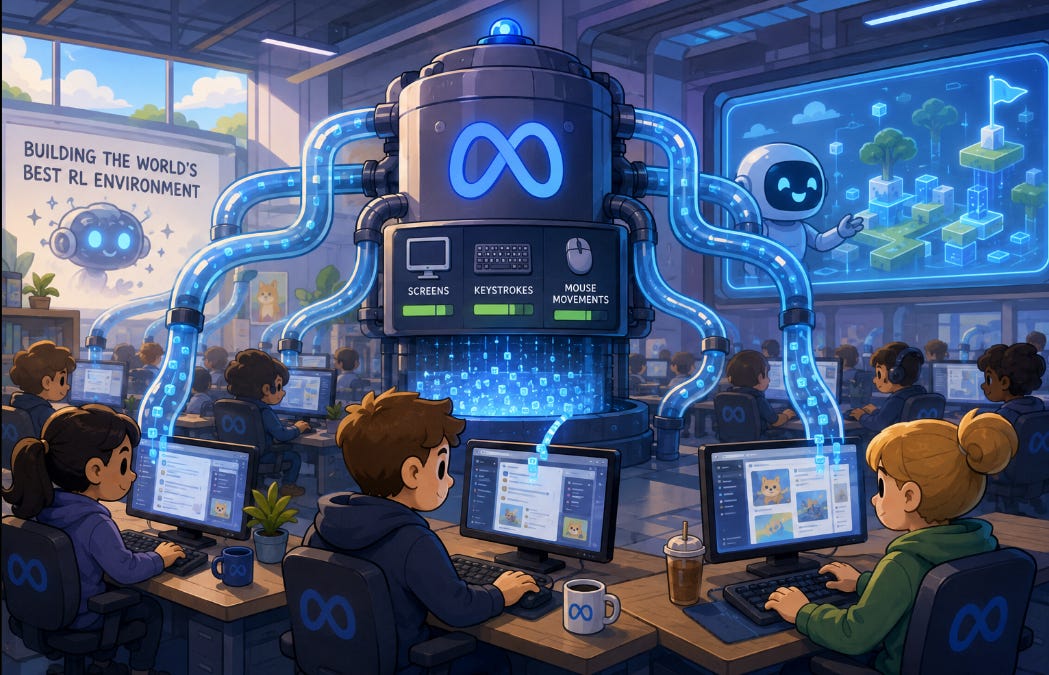
A central argument in SemiAnalysis's assessment of Meta is that recordings of real work could help build better reinforcement-learning tasks, the practice exercises in which an AI attempts a job and a verifier checks the result. The analysis says tasks written from scratch tend to become contrived and over-specified, while a task based on a recording of someone's actual job is representative of real knowledge work.
Recordings can also help produce the grading rubric. SemiAnalysis argues that thousands of traces of many people doing roughly the same task can reveal the range of actions involved, enough for a to draft a rubric, while a human still reviews it and assigns weights to the criteria. The argument supports a possible training-data advantage rather than demonstrating that it has already produced superior models.
- Authoring a good RL task is hard because difficulty can only be by trial: too easy and there is nothing to learn, too hard and the model never earns reward. Mechanize pays software engineers $400k+ and expects one usable task per week.
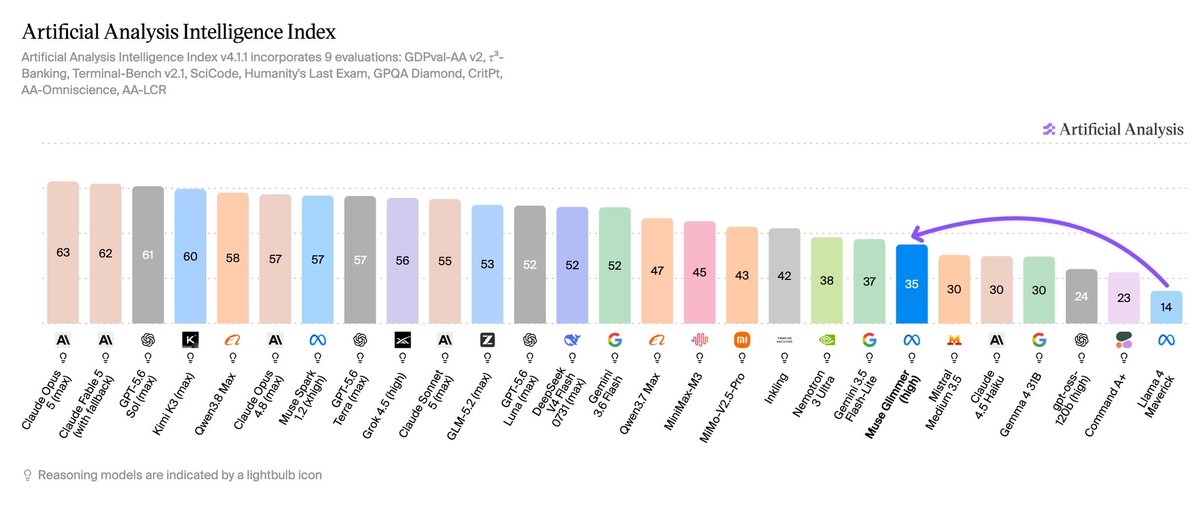
- The knock on benchmarks like GDPval is over-specification. Real knowledge work is hard because is scattered across email, texts, and random sites. Hand the model a 1,000-word spec and you have deleted the part that was difficult.
- Rubric graders can be bootstrapped from traces. Collect thousands of people doing roughly the same task and you cover the action space well enough for an LLM to draft the rubric; humans then review it and, crucially, weight the criteria.
- RL training data goes stale fast. A realistic coding task today involves orchestrating subagents, a workflow that did not exist seven months ago, so a task set only stays representative with a continuous stream of fresh recordings.
- The human-data supply chain became a real industry: Mercor, Surge, and Handshake are each past $1B ARR, with barely year-old entrants like Fleet, Mechanize, and AfterQuery near $100M. Demand for RL environments manufactured the supply.
- LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
- calibration — How well a model's confidence matches reality — a calibrated model saying "90% sure" is right about 90% of the time.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
“data is the fossil fuel of AI.”
Ilya
Checking sign-in…
Loading comments…