Cursor Composer 2 5 Coding Agent Index
- Source
- artificialanalysis.ai
- Author
- Artificial Analysis articles
- Date
Context
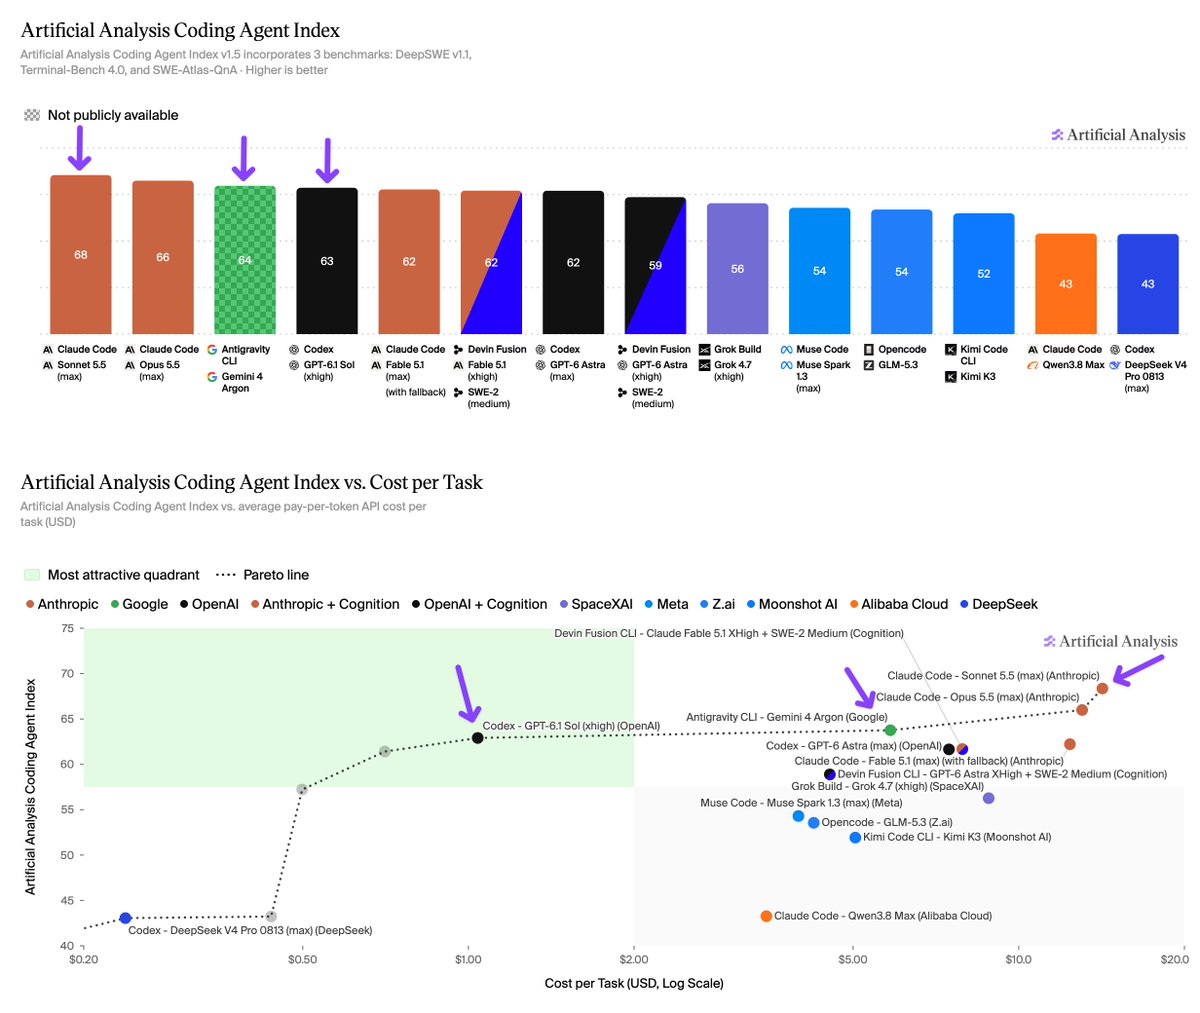
Artificial Analysis's Coding Index scores agents, meaning a model working inside a particular coding tool, on software tasks. Cursor's Composer 2.5 scores 62, up 14 points from Composer 2 at 48 (artificialanalysis.ai). Only two tested agents score higher: Anthropic's Claude Opus 4.7 (max) in Claude Code at 66 and OpenAI's GPT-5.5 (xhigh) in Codex at 65. Artificial Analysis says this puts Composer among the leading coding agent models, which was not clear for earlier releases.
The difference is cost. Those two leaders cost $4.10 and $4.82 per task, about 10 times Composer 2.5 Fast at $0.44 and about 60 times standard Composer 2.5 at $0.07. Medium-effort versions of rival agents cost $1.24 to $2.21 per task, and Composer 2.5 is the cheapest agent scoring above 60. Fast and standard are the same model served two ways: Fast finished tasks in 6.7 minutes on average against 9.3, about 30% faster, at about six times the cost per task, matching Cursor's sixfold pricing of $3.00/$15.00 against $0.50/$2.50 per million input/output tokens. Fast is the default in Cursor.
Most of the gain over Composer 2 comes from -Pro-Hard-AA, which rose from 12% to 47%, comparable to Claude Opus 4.7 (max) in Claude Code; Terminal-Bench v2 and SWE-Atlas-QnA rose 2 and 3 points. Like Composer 2, the model is built by continuing to train Moonshot AI's open-weights Kimi K2.5, and Cursor reports that about 85% of the total compute came from its own additional training and reinforcement learning. It is available only inside the Cursor IDE and Cursor CLI, with no external API.
- Composer 2.5 scores 62 on the Coding Agent Index, 14 points above Composer 2, behind only Claude Opus 4.7 (max) in Claude Code at 66 and GPT-5.5 (xhigh) in Codex at 65, which cost $4.10 and $4.82 per task.
- The largest gain is on SWE-Bench-Pro-Hard-AA, from 12% to 47%, comparable to Claude Opus 4.7 (max) in Claude Code; Terminal-Bench v2 rose 2 points to 66% and SWE-Atlas-QnA 3 points to 72%.
- Composer 2.5 Fast runs about 30% faster than standard (6.7 vs 9.3 minutes per task) at about 6x the per-task cost, matching Cursor's 6x token pricing of $3.00/$15.00 versus $0.50/$2.50 per million tokens.
- Composer 2.5 continues training on Moonshot AI's open-weights Kimi K2.5, with Cursor reporting about 85% of total compute from its own training and RL. It is available only in Cursor's IDE and CLI, with no external API.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- SWE-bench — The standard benchmark for AI coding agents: real GitHub issues from real repositories, scored by whether the agent's patch passes the project's own tests.




Checking sign-in…
Loading comments…