Ling 3.1 Flash doubles its Intelligence Index score to 41
- Source
- x.com
- Date

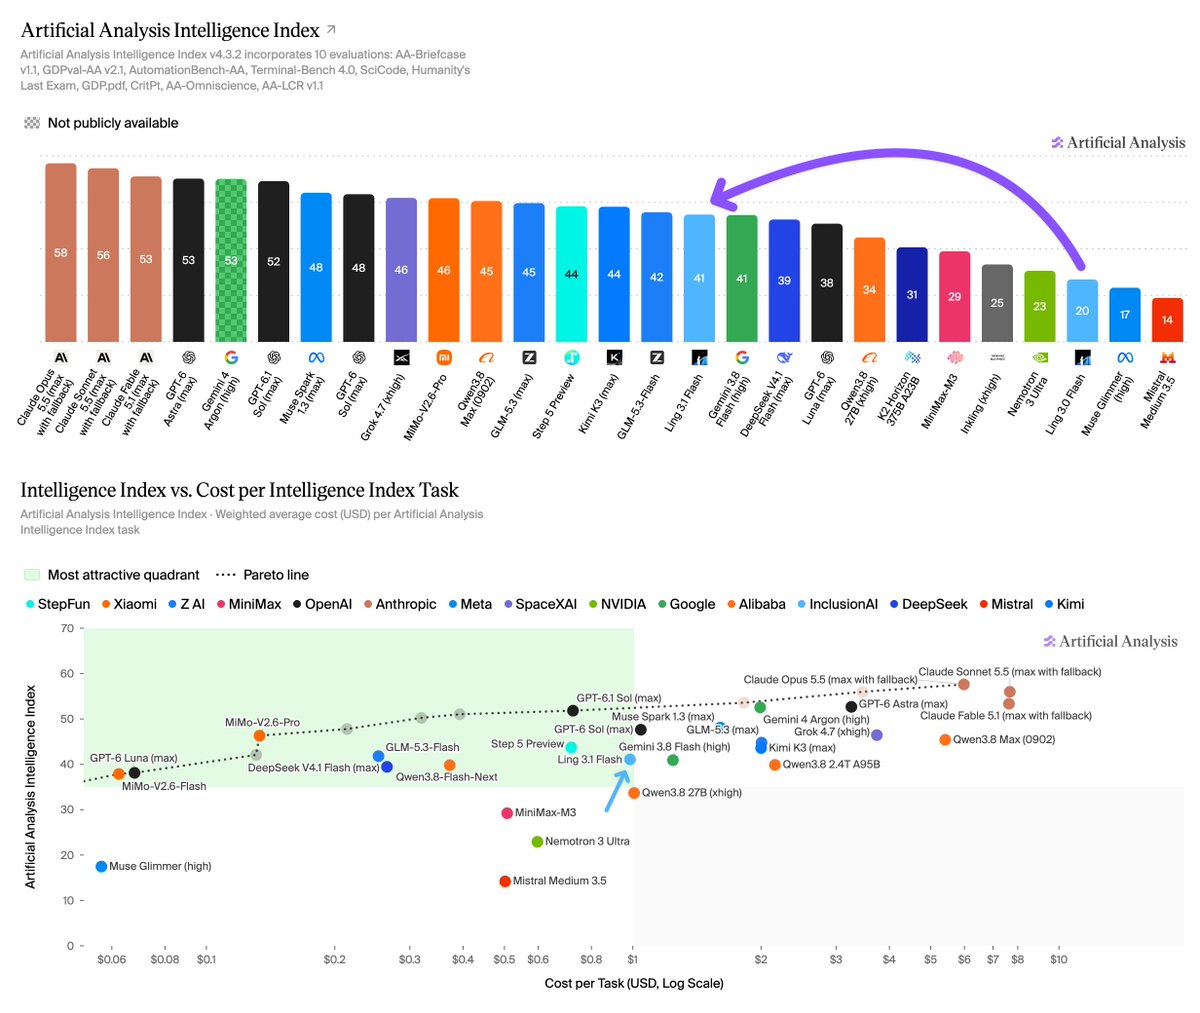
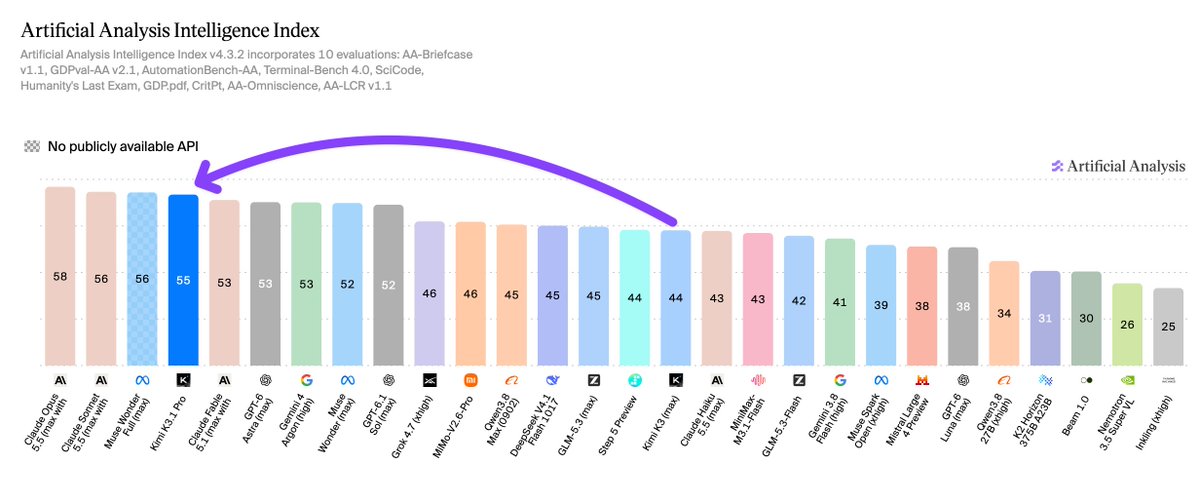
Ling 3.1 Flash makes large gains in intelligence over its predecessor, scoring 41 on the Artificial Analysis Intelligence Index with particular improvement in agentic capabilities @AntLingAGI has released Ling 3.1 Flash, a reasoning model with 560B total parameters, 25B active parameters, and a 1M token context window. It scores 41 on the Artificial Analysis Intelligence Index v4.3, up from 20 from Ling 3.0 Flash, which launched in August. Ling 3.1 Flash is expected to be open weights, with Ant Group releasing the weights soon. Key results: ➤ Ling 3.1 Flash improves agentic capabilities over its predecessor. With a GDPval-AA v2 Elo of 1,622 and an AA-Briefcase Elo of 1,400, the model rivals peer models such as GLM-5.3-Flash, Gemini 3.8 Flash (high) and DeepSeek V4.1 Flash (Max). Ling 3.1 Flash also shows notable gains on AutomationBench-AA (62%) and Terminal-Bench v4.0 (33%). ➤ Ling 3.1 Flash scores +2 on AA-Omniscience, a 22 point improvements from Ling 3.0 Flash (-18). Compared to its predecessor, its accuracy rate rose from 18% to 29% while the hallucination rate fell from 44% to 38% at a similar attempt rate (56% to 58%), demonstrating the gain comes primarily from knowing…
Context
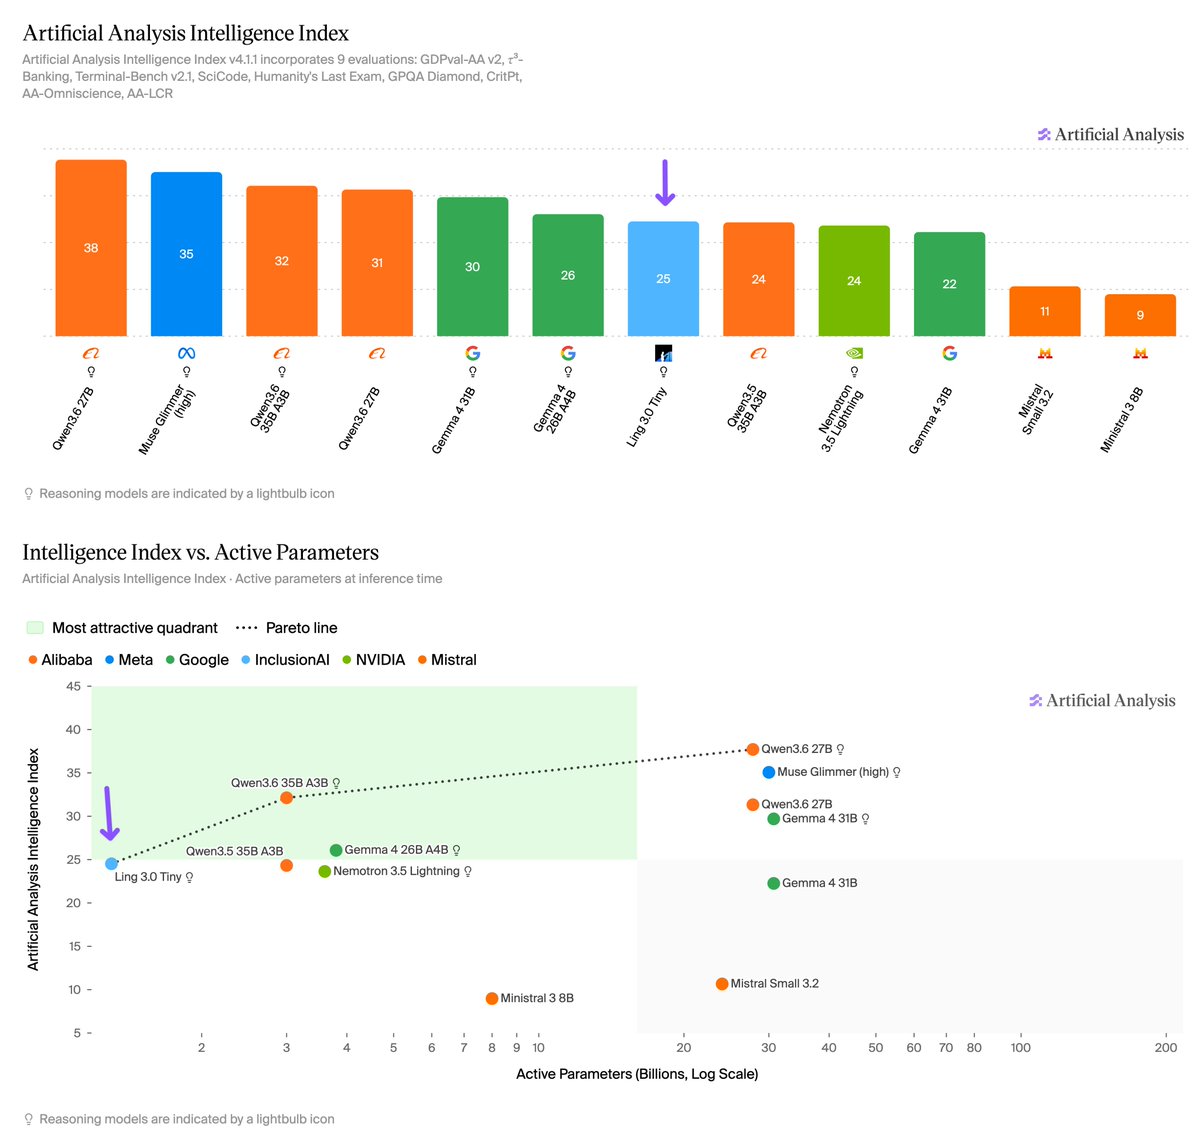
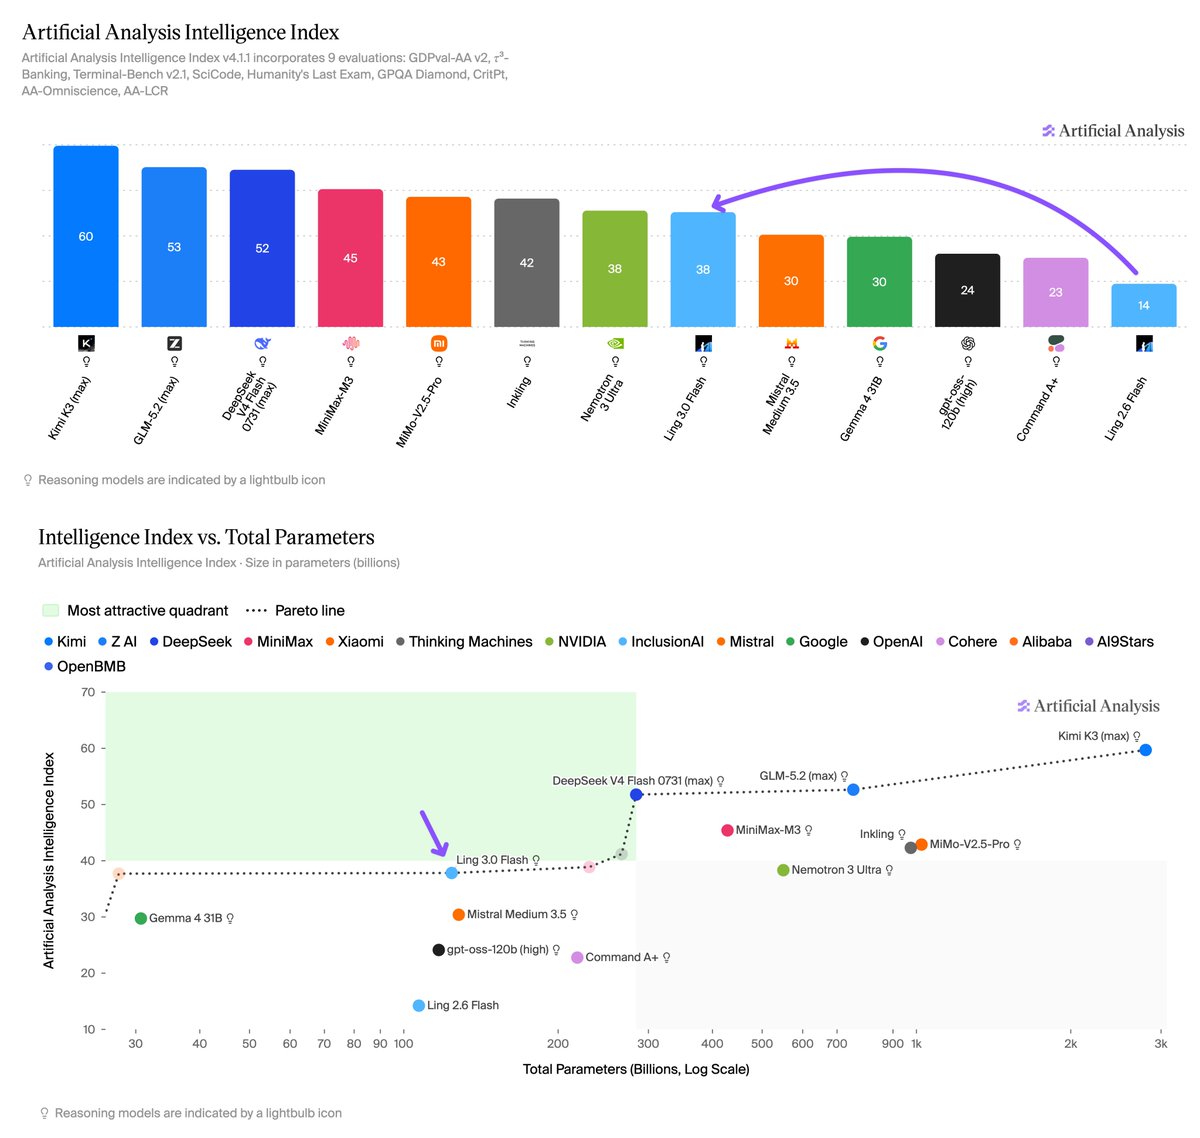
Artificial Analysis reported in a post on X on October 6 that Ling 3.1 Flash, a from the Ling team at Ant Group, scores 41 on its Intelligence Index v4.3, up from 20 for Ling 3.0 Flash, which launched in August. An earlier Artificial Analysis report gave Ling 3.0 Flash 38, a different number for the same model, so scores from the two reports are not directly comparable.
The more specific finding concerns factual recall. On AA-Omniscience, Artificial Analysis's knowledge test, accuracy rose from 18% to 29%, and its reported rate fell from 44% to 38%, while the share of questions the model attempted stayed similar (56% to 58%). Artificial Analysis reads that as the model knowing more, not answering less often.
The model is also much larger, with 560 billion total parameters (25 billion active) against 124 billion (5.1 billion) for its predecessor, and it costs more to use. Weights are expected soon; for now it is available through Novita AI.
- reasoning model — A model trained to think — generating extended internal reasoning before answering — trading time and tokens for accuracy on hard problems.
- hallucination — When a model states something false with full confidence — inventing facts, citations, or APIs that don't exist.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- open weights — A model whose trained parameters are published for anyone to download and run — unlike API-only models you can access but never possess.

Checking sign-in…
Loading comments…