Interpreting Eci
- Source
- epoch.ai
- Author
- Epoch AI publications
- Date
Context
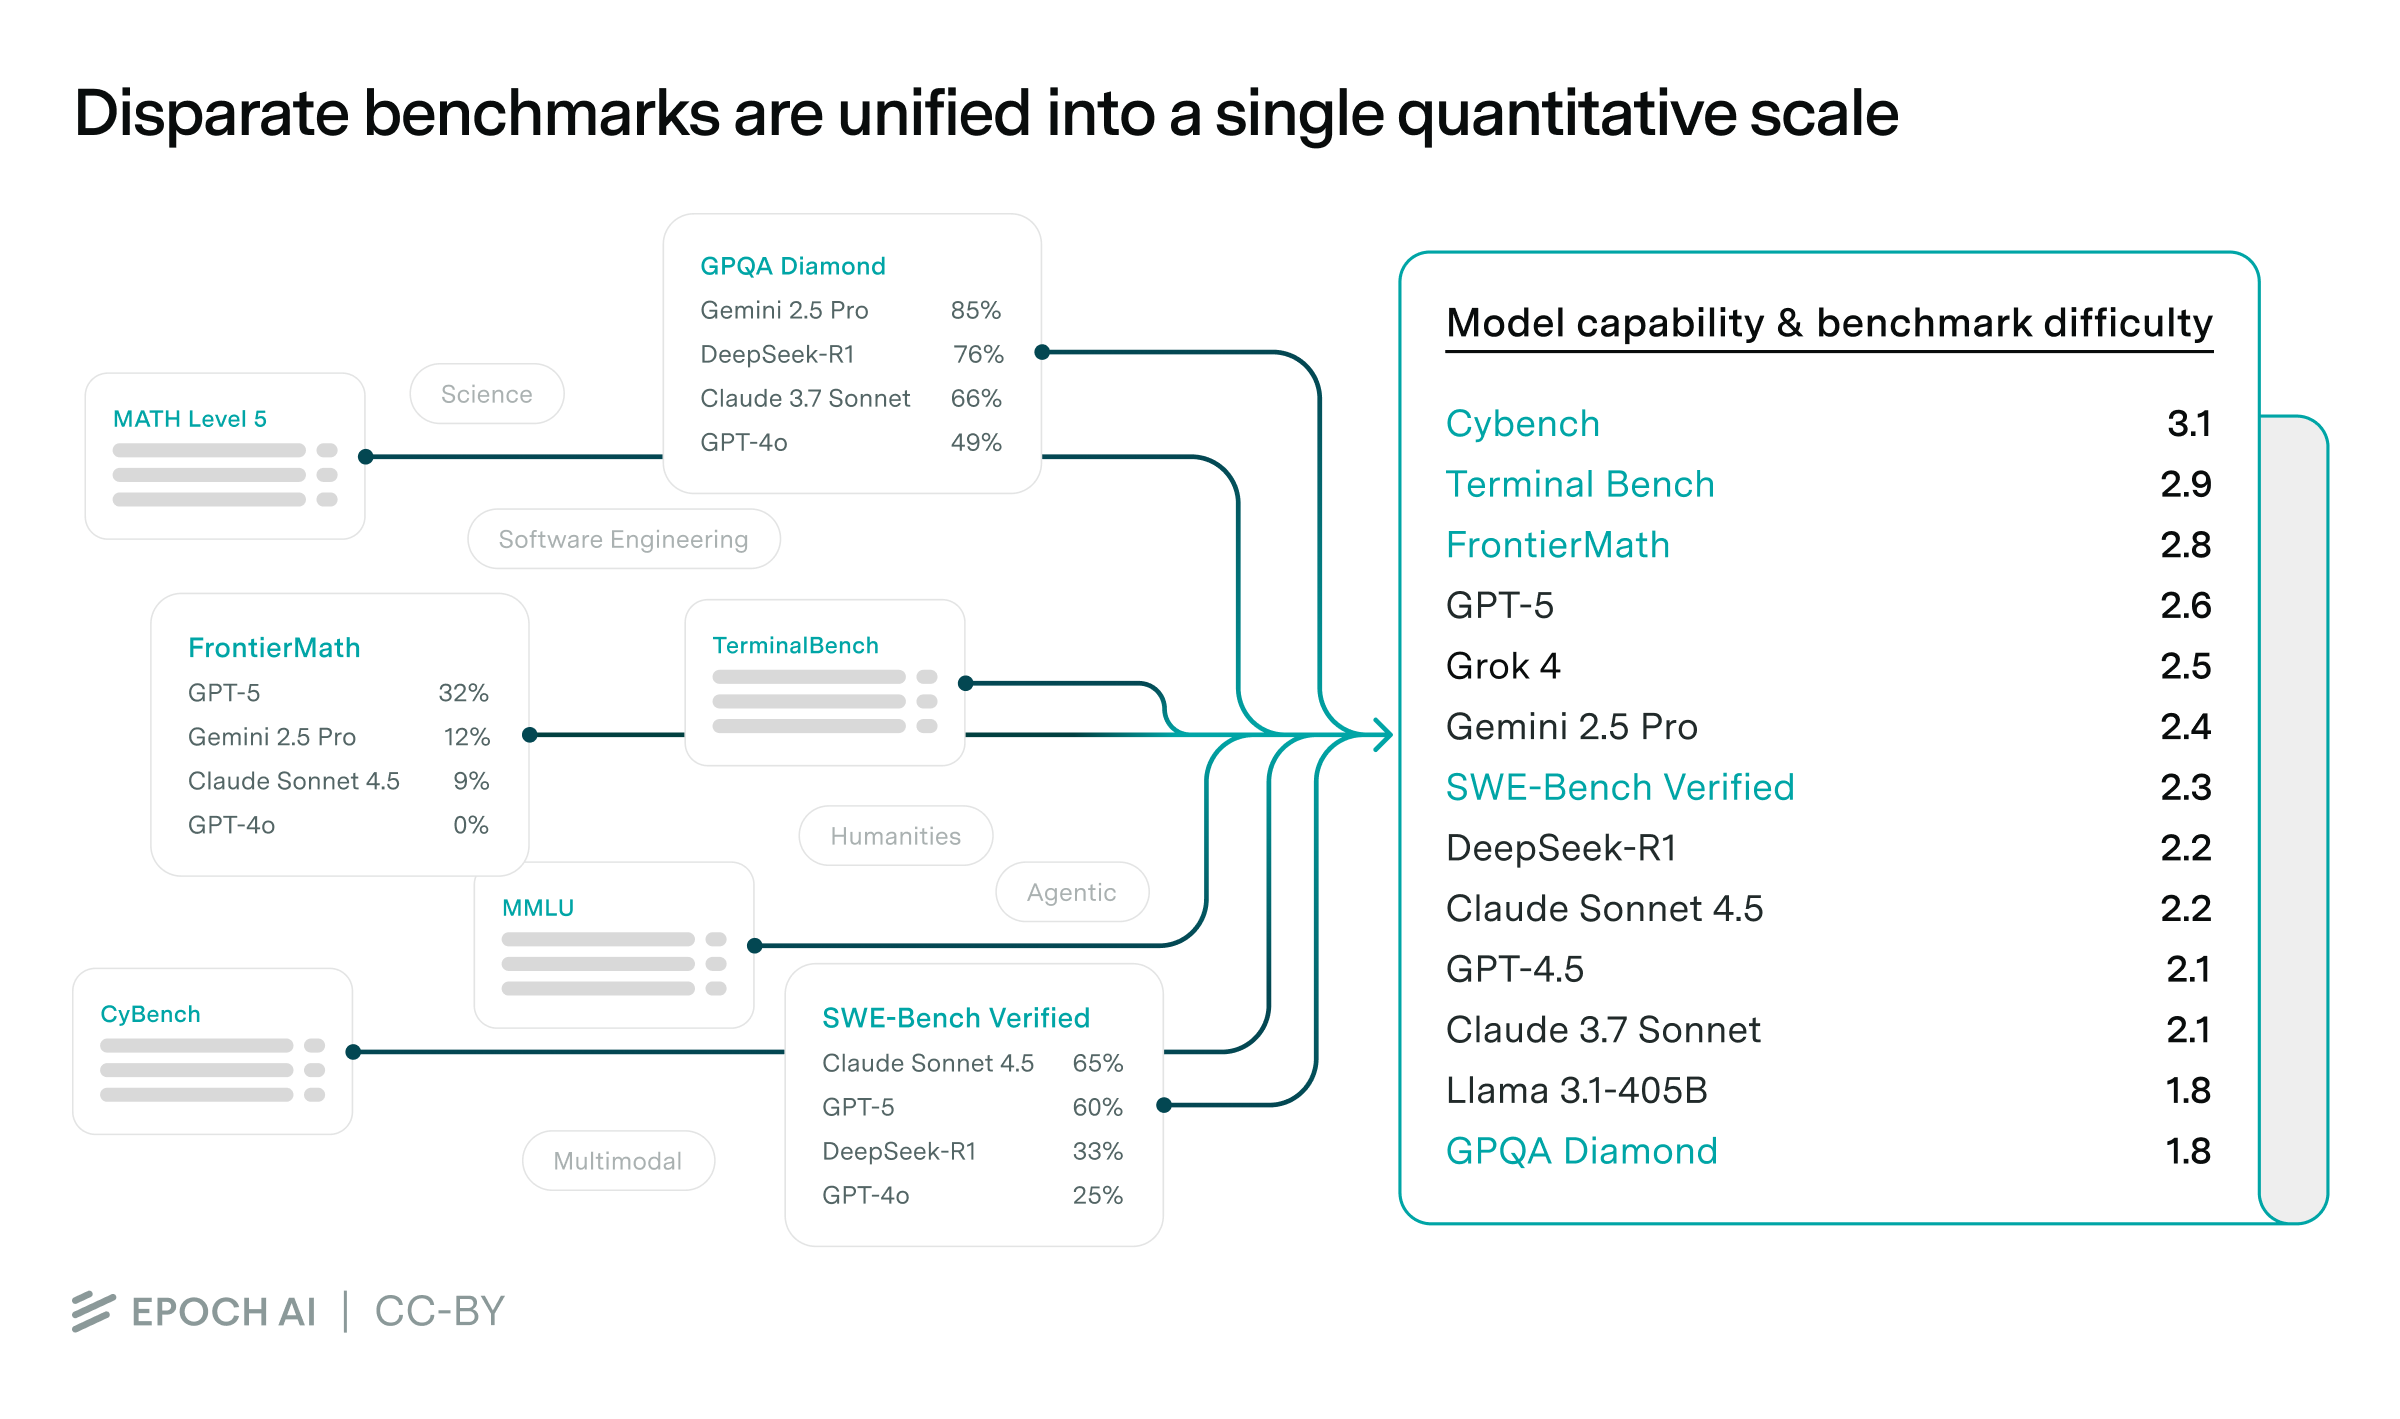
Individual AI benchmarks tend to saturate within one to three years, which makes long-run comparisons hard. The Epoch Capabilities Index (ECI) addresses this by stitching many benchmarks together, and in a November 2025 data insight Epoch AI's Jaeho Lee and Luke Emberson explain how to read its scores (epoch.ai). The index comes from a statistical model that gives each AI model a single capability score and each two fitted values: an overall difficulty and a slope describing how widely its problems vary in difficulty. A model's expected score on a benchmark then depends on how far its capability sits above or below that benchmark's difficulty. At the time, the fit used 1,123 evaluations covering 147 models and 39 benchmarks.
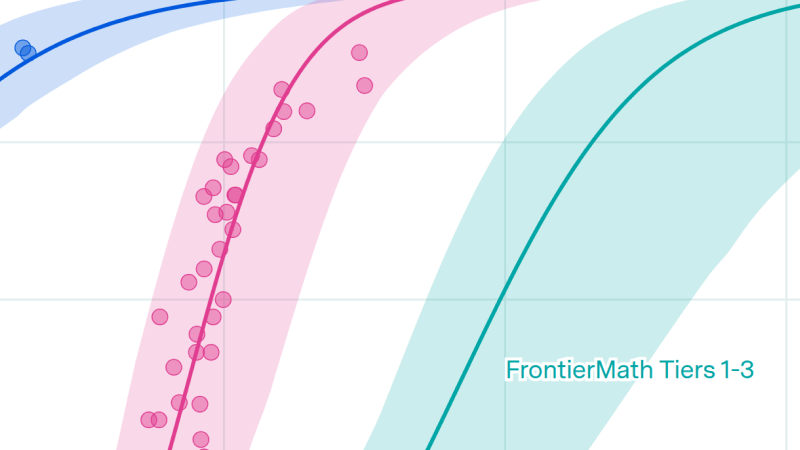
Because the scale itself is abstract, Epoch interprets a score by converting it into the expected result on a particular benchmark, plotted for GSM8K, OTIS Mock AIME 2024-2025 and FrontierMath Tiers 1-3, which range widely in difficulty. The underlying data show why one number spans so much: OpenAI's GPT-5 (high), at an ECI of about 150, scored 91% on the OTIS Mock AIME and 27% on FrontierMath.
The shaded bands on the chart are confidence intervals for the expected score, not prediction intervals, so individual models can land above or below them.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
Checking sign-in…
Loading comments…