An independent evaluation of Gemini 2.5 Deep Think shows gains in background knowledge and precise computation, and usefulness as a research assistant. It also finds limited creativity on harder proofs and citation errors, which helps set expectations before relying on it.
Key takeaways · AI-distilled
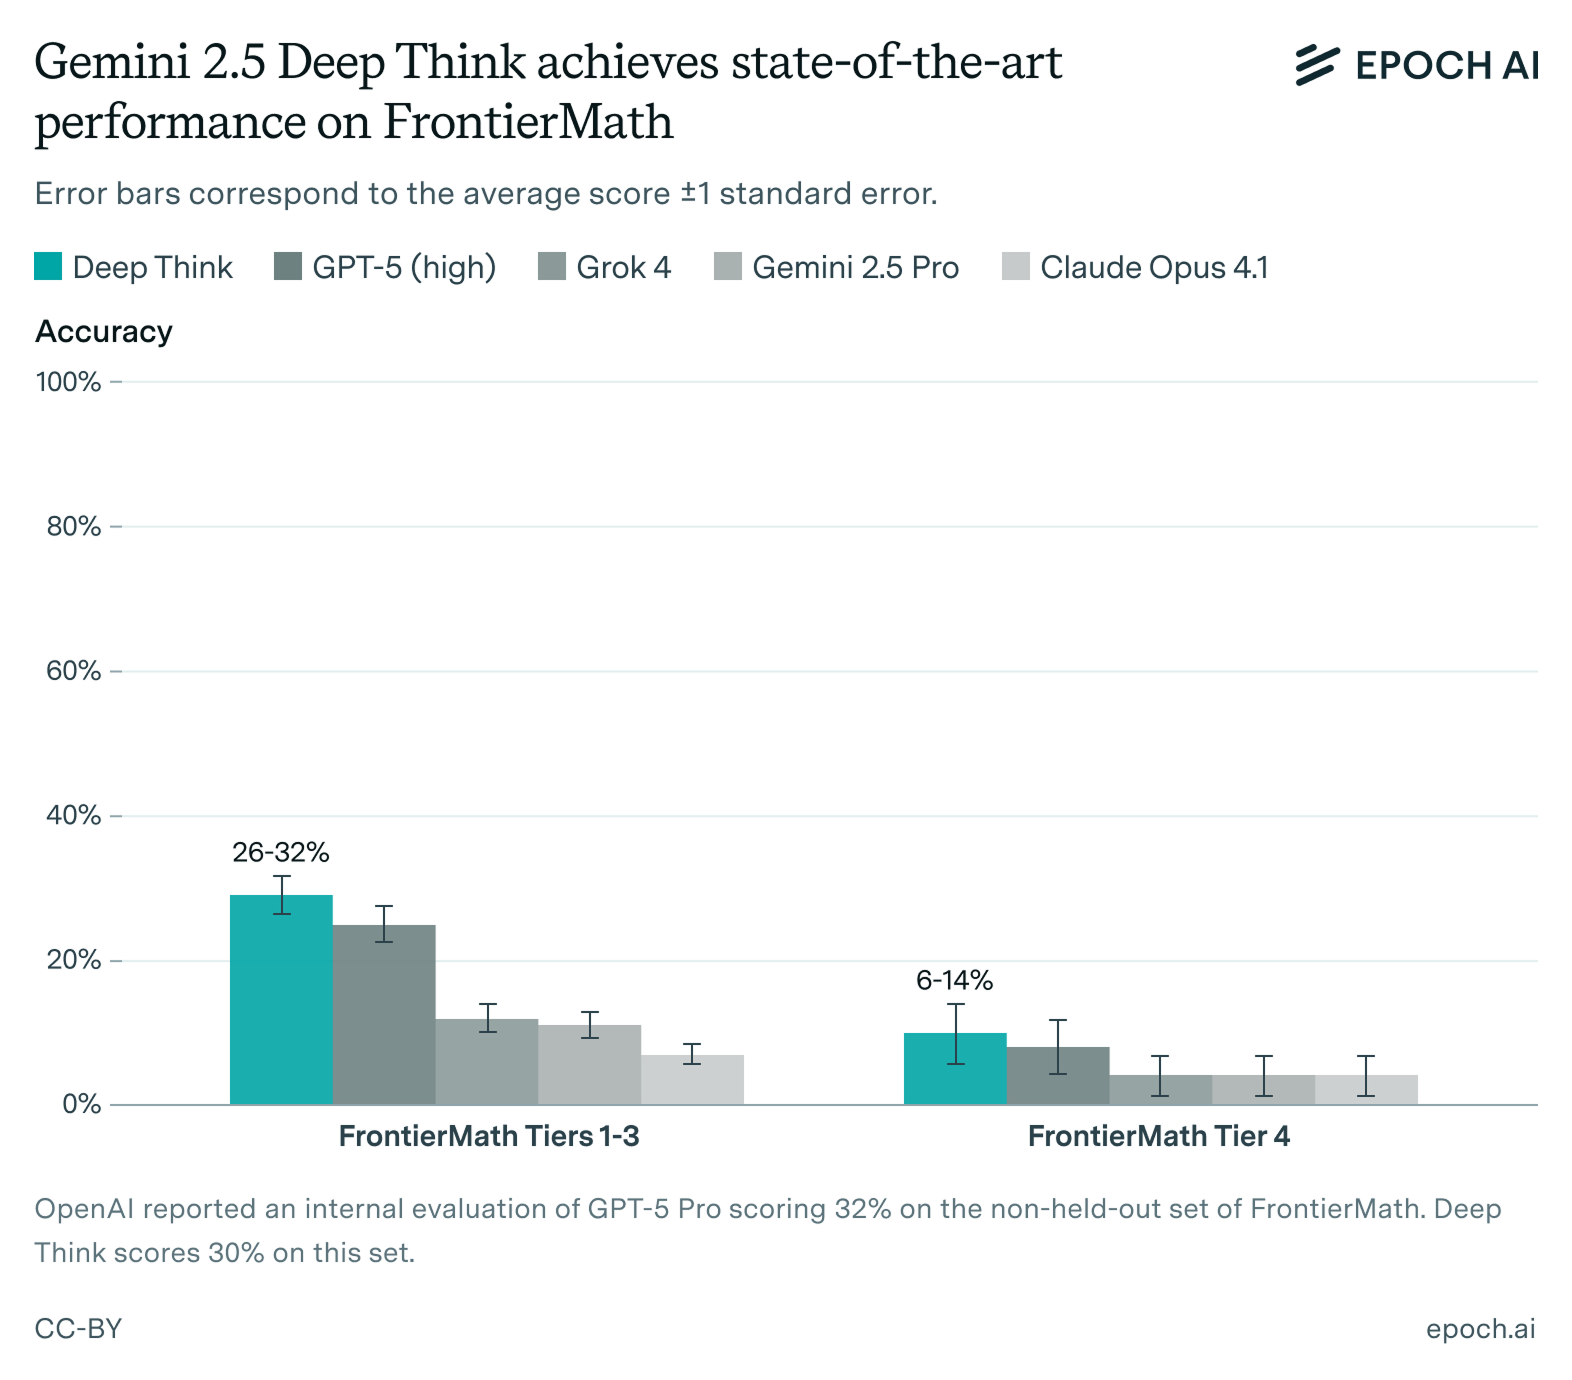
In Epoch's manual evalA repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.Full definition → via the Gemini app, Gemini 2.5 Deep Think set FrontierMath records of 29% on Tiers 1-3 and 10% on Tier 4. Epoch says this shows improved ability on short-answer problems needing deep background knowledge and precise computation.
Google's internal evaluations put this Deep Think, a variation of its IMO gold model, at a bronze-equivalent 61% on the 2025 IMO, which Epoch calls not particularly informative. It failed two medium-to-hard 2024 IMO problems in all 10 Epoch tries each.
On geometry, Deep Think relies much less on coordinate systems than other models, which Epoch reads as more conceptual. Yet in one case it got a grade-school word problem wrong, in a way reminiscent of human cognitive biases.
Two mathematicians Epoch commissioned called Deep Think a generally helpful research assistant, broadly on par with top models, but Epoch found multiple incorrect literature citations, to sources that did not exist or lacked the stated results.
Google commissioned the evaluation; Epoch says it kept editorial control and calls it the most comprehensive third-party evaluation of a high-compute model setting to its knowledge.
Terms in this piece · Glossary
eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.