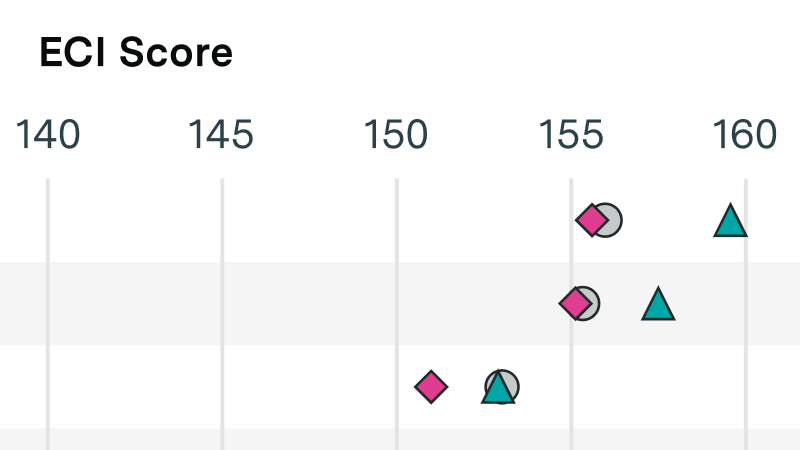
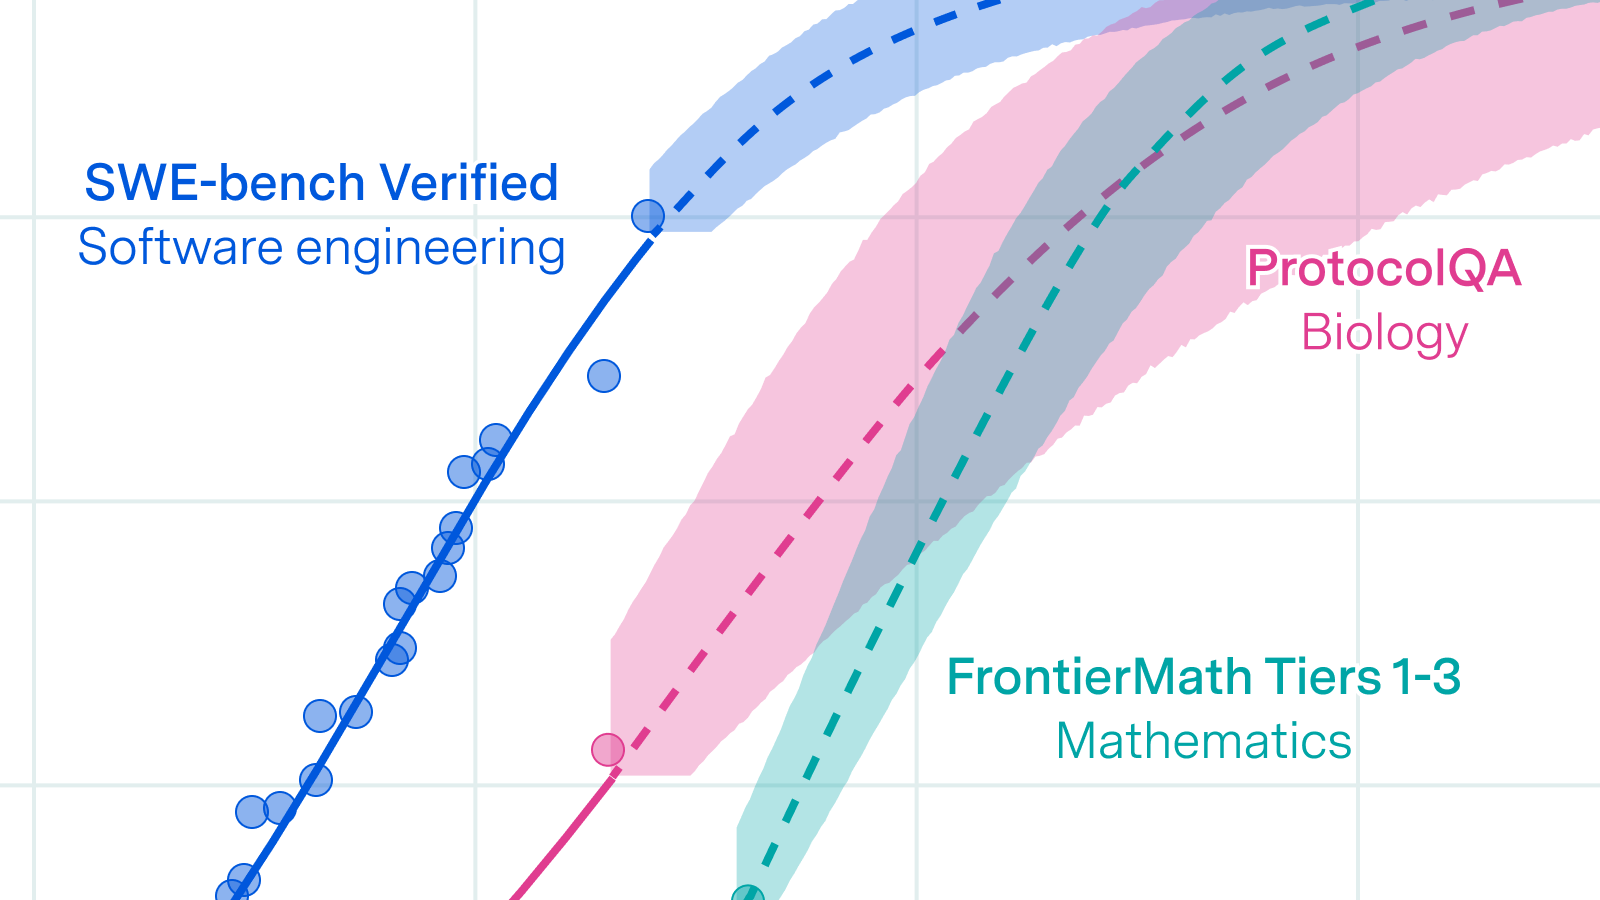
A model's overall ranking can conceal a distinct mix of strengths. Epoch AI's domain-specific analysis finds that Anthropic's Claude models generally perform better on software-engineering benchmarks than their overall index would suggest, and worse on mathematics, though Epoch says that math gap may be narrowing in recent models. Source.
These are relative scores fitted from subsets of benchmarkA standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.Full definition → results, whose coverage differs by model. They help compare capability profiles, but do not show that software engineering is inherently easier than mathematics or measure absolute progress between the two domains. The workload still determines which profile is relevant.
Terms in this piece · Glossary
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.