Diffusion model Mercury 2.5 goes GA on OpenRouter
- Source
- x.com
- Date

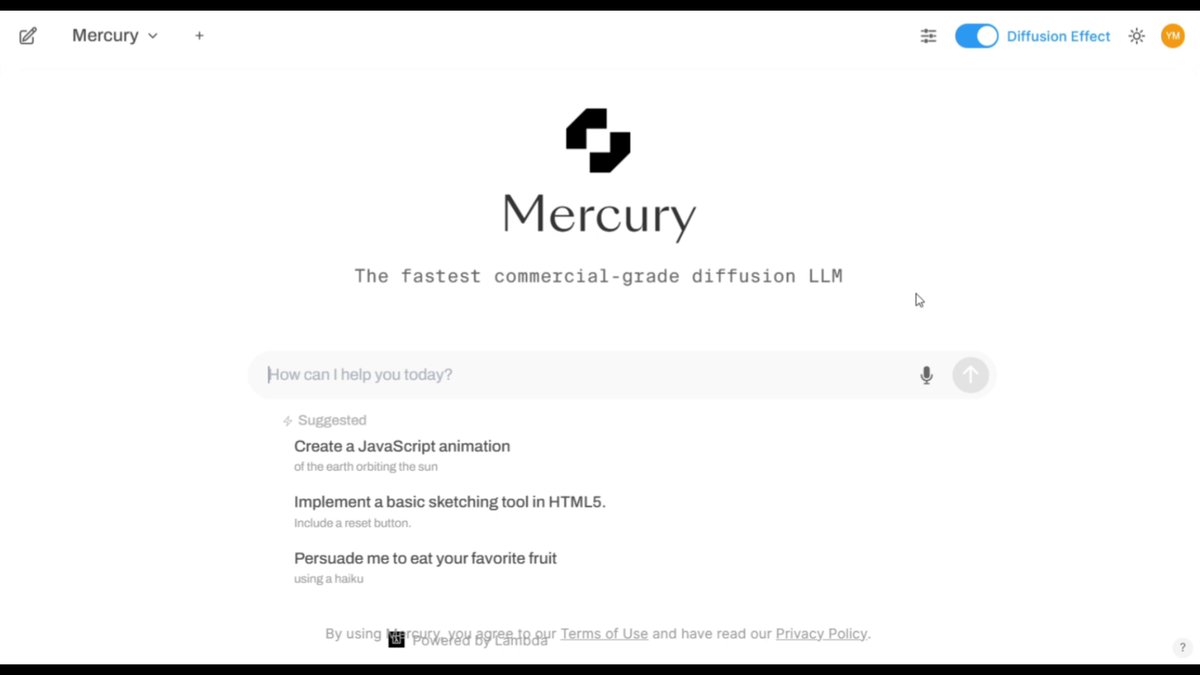
Mercury 2.5 from @_inception_ai is now generally available on OpenRouter. It's the fastest model on our Fastest Models leaderboard that doesn't require specialized hardware. A diffusion LLM: it decodes tokens in parallel rather than one at a time. The gain is largest on code-heavy prompts. Use it here: https://t.co/xTId0uFKC8
Context
Mercury 2.5, built by Inception, is now generally available on OpenRouter, a marketplace that routes API calls to many different AI models. OpenRouter's post describes it as a diffusion : instead of predicting one , feeding it back in, and predicting the next, a diffusion model starts from a rough draft of the full response and refines many tokens in parallel across several steps.
OpenRouter says that parallel decoding makes Mercury 2.5 the fastest model on its Fastest Models leaderboard among models that do not require specialized hardware, with the largest speed gains on code-heavy prompts. That matches Inception's own launch announcement the same day, which claimed roughly a 40 percent capability jump over the prior Mercury 2 and throughput above 1,100 tokens per second on widely available Nvidia GPUs, figures reported by Inception itself rather than independently measured by OpenRouter.




Checking sign-in…
Loading comments…