Mercury 2 ships as the first reasoning diffusion LLM
- Source
- x.com
- Date

Mercury 2 is live. The world's first reasoning diffusion LLM – 5x faster than leading speed-optimized autoregressive models. Built for production: multi-step agents without delays, voice AI with tight latency budgets, instant coding feedback. Diffusion-based generation enables parallel refinement, not sequential tokens. Faster. More controllable. Dramatically lower inference cost. Available today on the Inception API. @dinabass has the story in @business.

https://t.co/2WTHJUfs4a
Context
Inception launched Mercury 2 in February 2026 as a reasoning built around parallel refinement. It produces and revises multiple text units together over several steps, rather than generating each unit sequentially. The model also offers adjustable reasoning effort, letting developers control how much deliberation a request receives. The intended benefit is especially relevant to software that makes repeated model calls: time spent generating each response adds to the overall wait. Mercury 2's contribution is an alternative generation approach aimed at reducing that accumulated delay. Launch explanation
- LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
 postInception ships Mercury Decide update with ZDR and 66k context
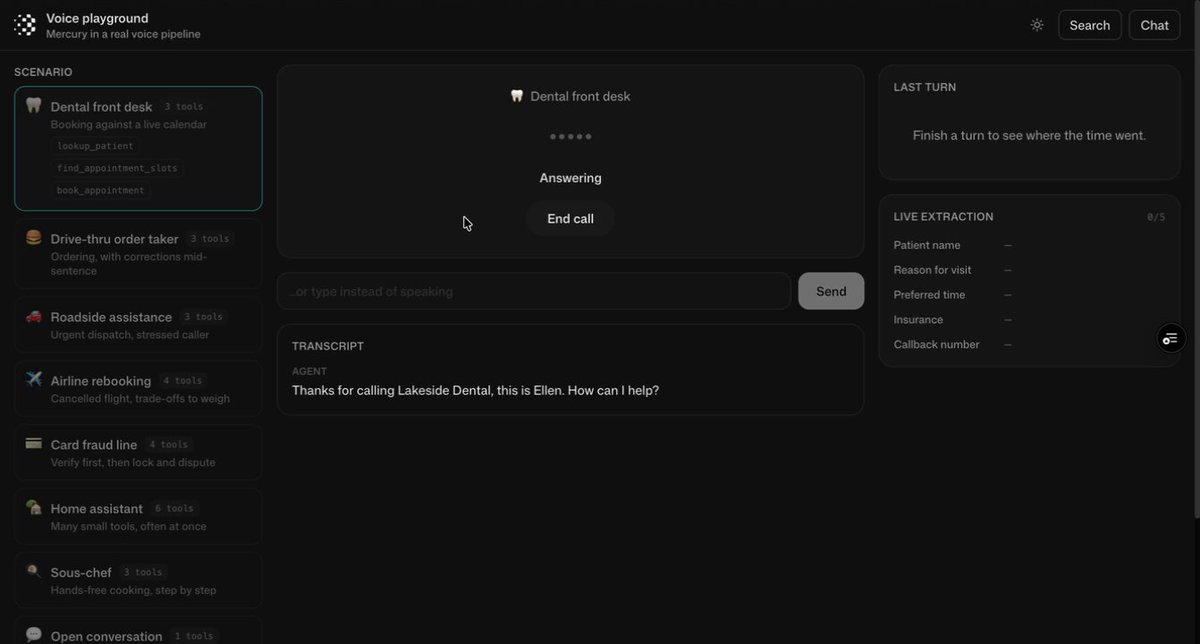 postInception launches Mercury Voice, a diffusion LLM for low-latency voice agents
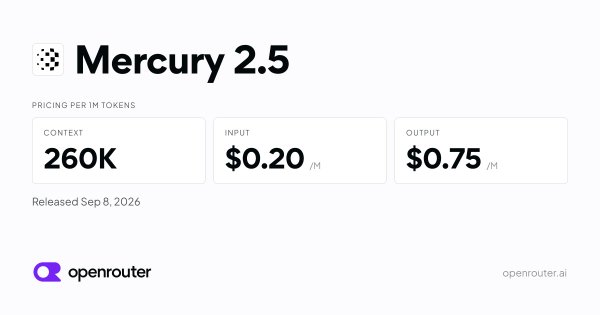
 postToday, we’re introducing Mercury 2.5, the most capable diffusion LLM on the…
 postInception ships Mercury 2.5 Preview at roughly 1,100 tokens per second
Checking sign-in…
Loading comments…