Cognition ships SWE-2, a cheaper coding model with tunable reasoning effort
- Source
- Cognition
- Date
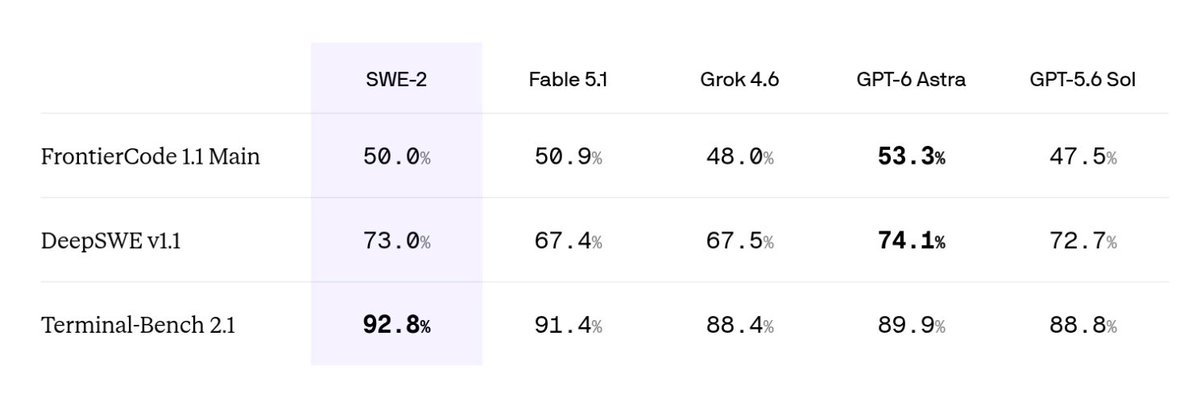
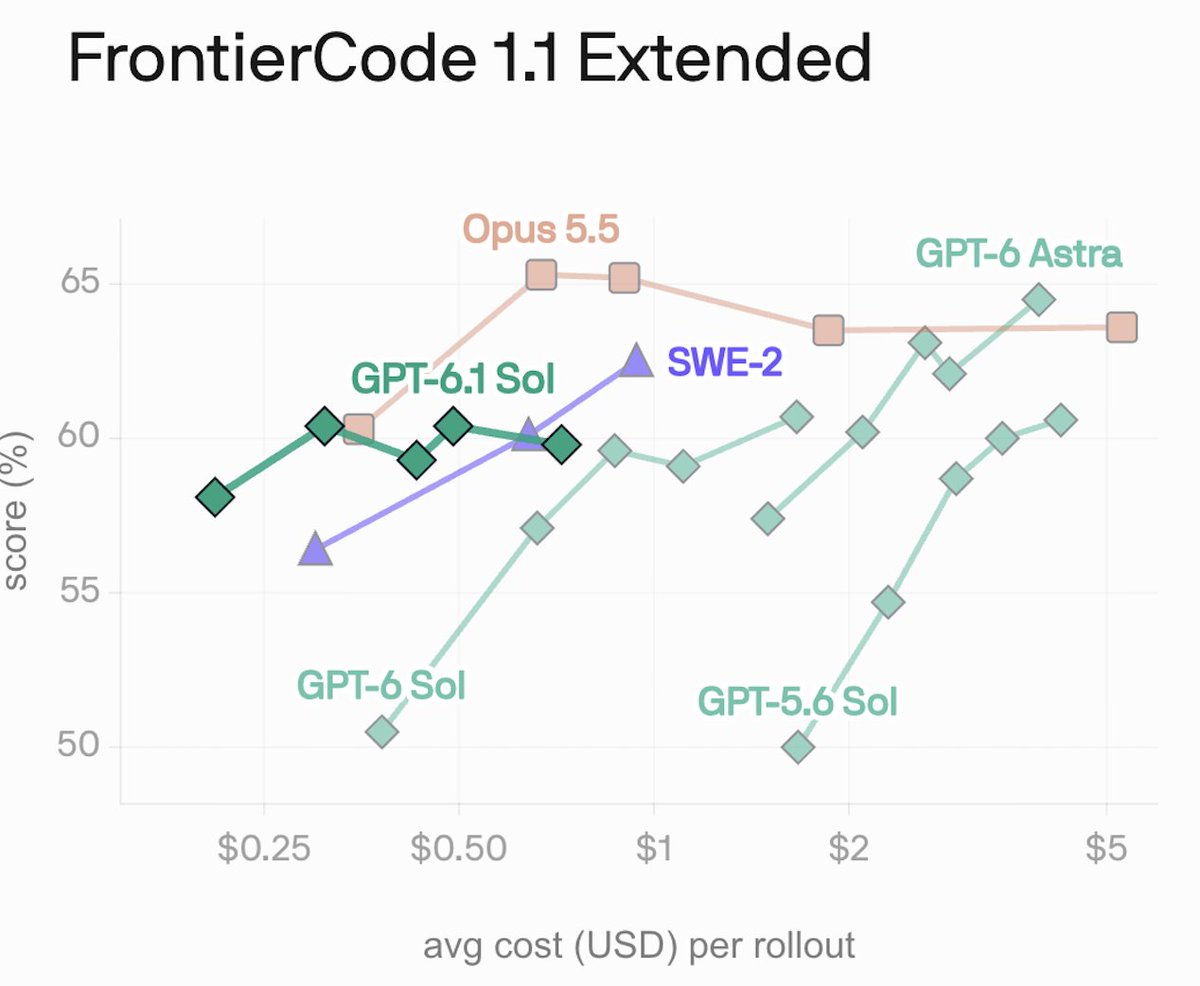
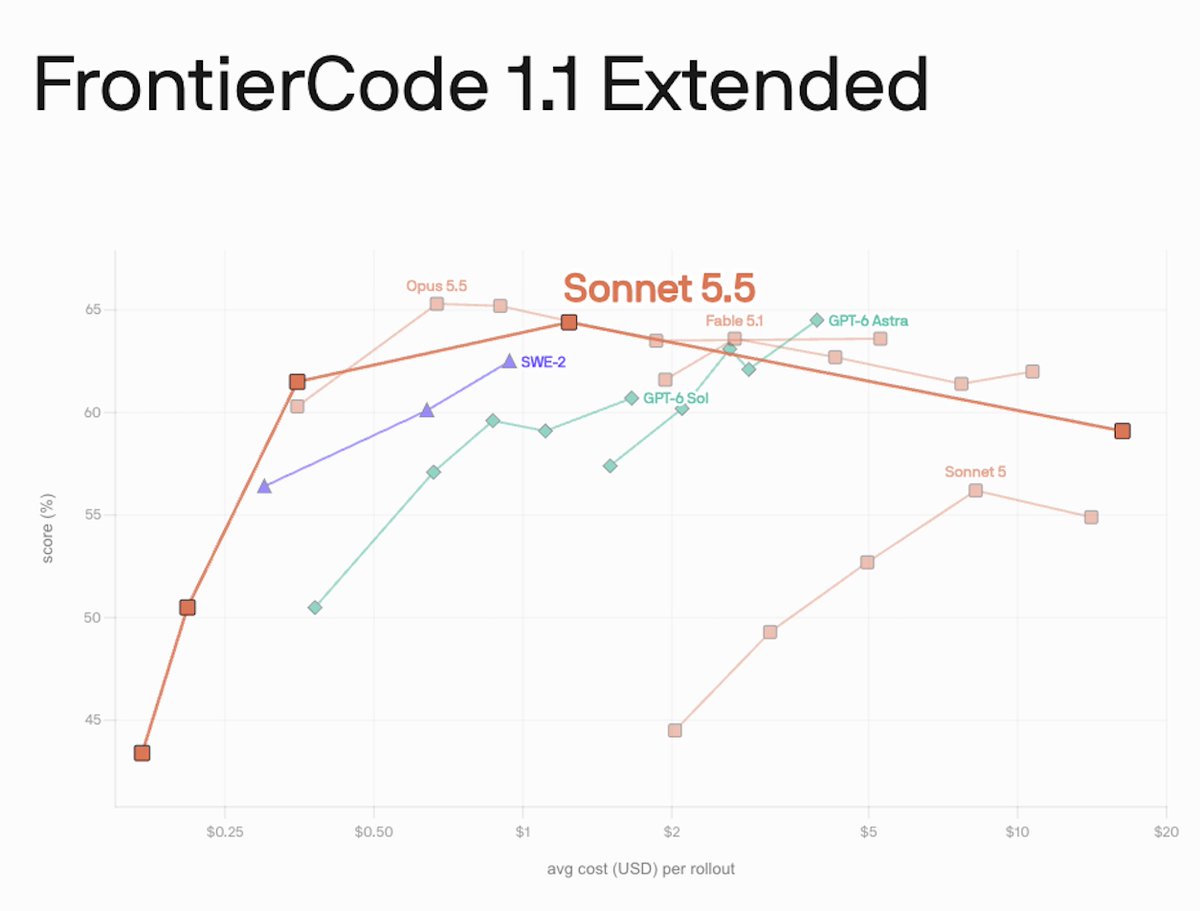
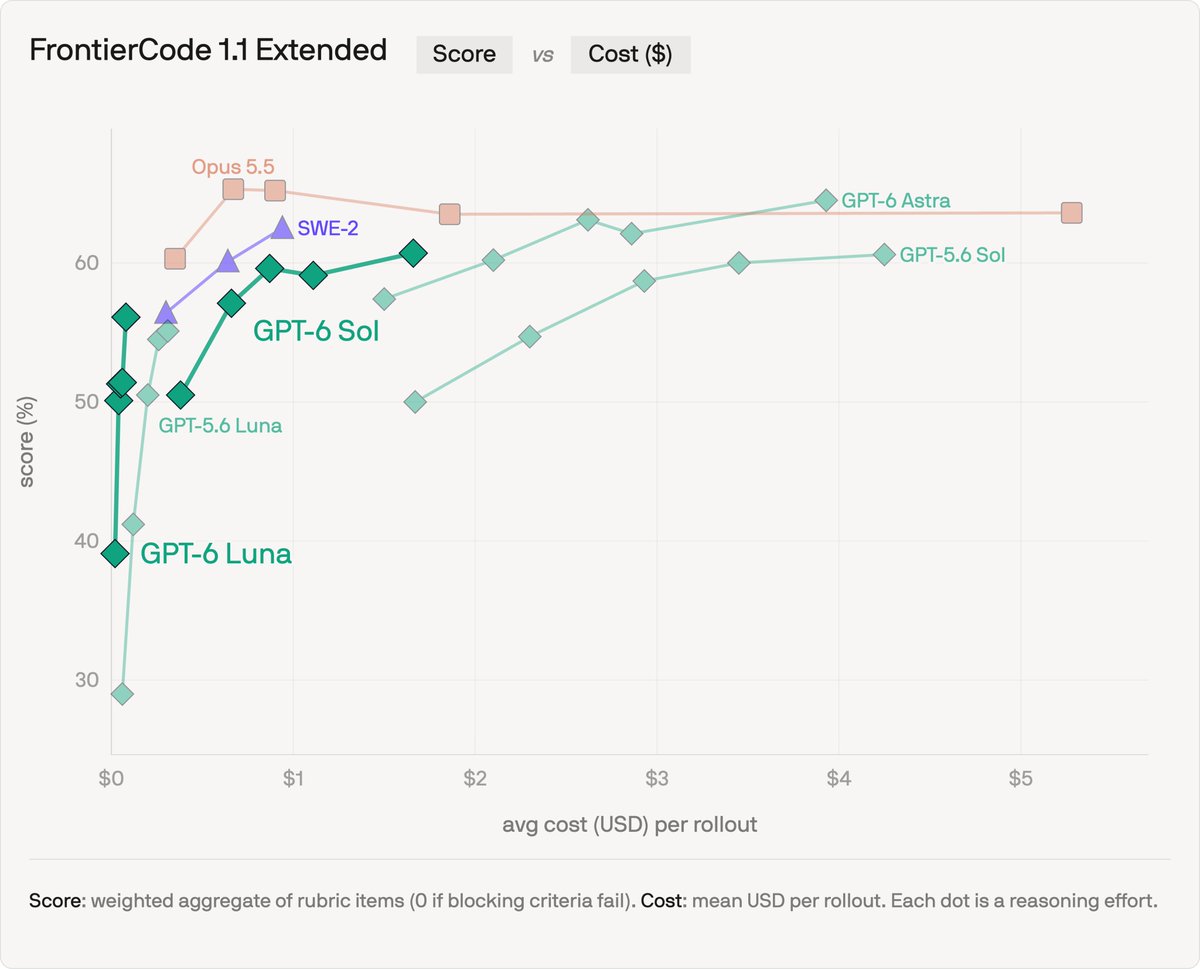
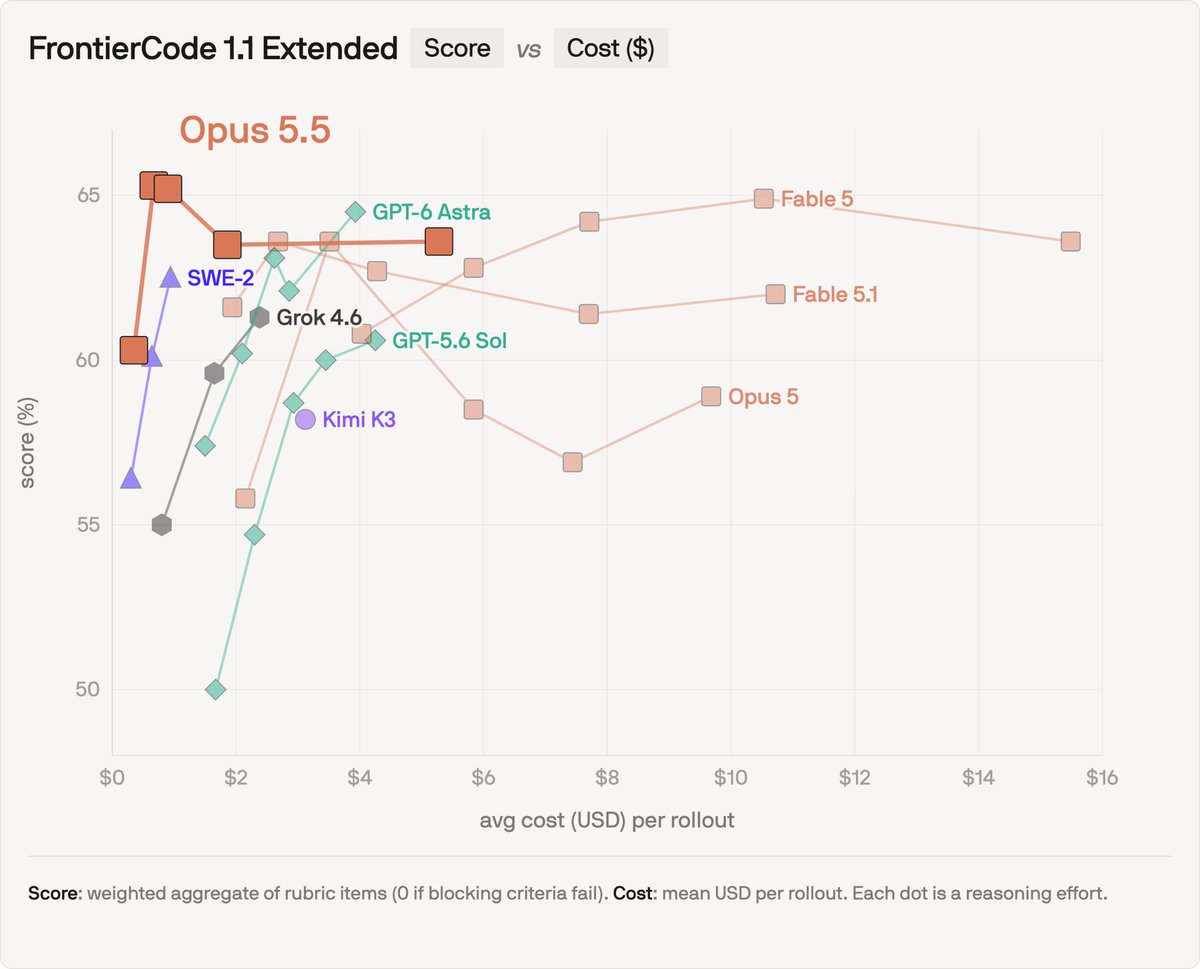
Cognition released SWE-2, a coding model post-trained on Kimi-K3 that lets developers tune reasoning effort per task instead of paying a fixed cost for every request. It ships now inside Devin Desktop and the Devin CLI, and Cognition's own benchmarks claim frontier-level FrontierCode scores at up to 70 percent less than SWE-1.7 cost to run. The tunable-effort design matters as much as the benchmark number by itself: a team can dial reasoning up for a hard refactor and down for a routine fix, instead of routing between separate cheap and expensive models to get the same effect. Vendor-reported numbers still need independent verification, but the pricing structure is a specific, checkable claim: if it holds, it undercuts the assumption that frontier-level coding performance requires frontier-level per-token cost.
Context
Cognition announced SWE-2 on September 10. The company says the model is post-trained on Kimi K3, supports adjustable reasoning effort, and is available in Devin Desktop and the CLI. Reasoning effort is a setting that generally lets a user trade more deliberation against time and cost. Cognition reports that SWE-2 scores 50.0% on FrontierCode, a coding , matching Fable 5.1 at 64% lower cost, and that its thread also shows fewer turns and lower costs than SWE-1.7. These are vendor-reported comparisons, and the announcement text reviewed here does not include independent testing, so how the cost and quality trade-off holds up outside Cognition's own benchmarks is not established.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.

Checking sign-in…
Loading comments…