Sonnet 5.5 arrives in Devin with a reported 64.4% FrontierCode score
- Source
- x.com
- Date

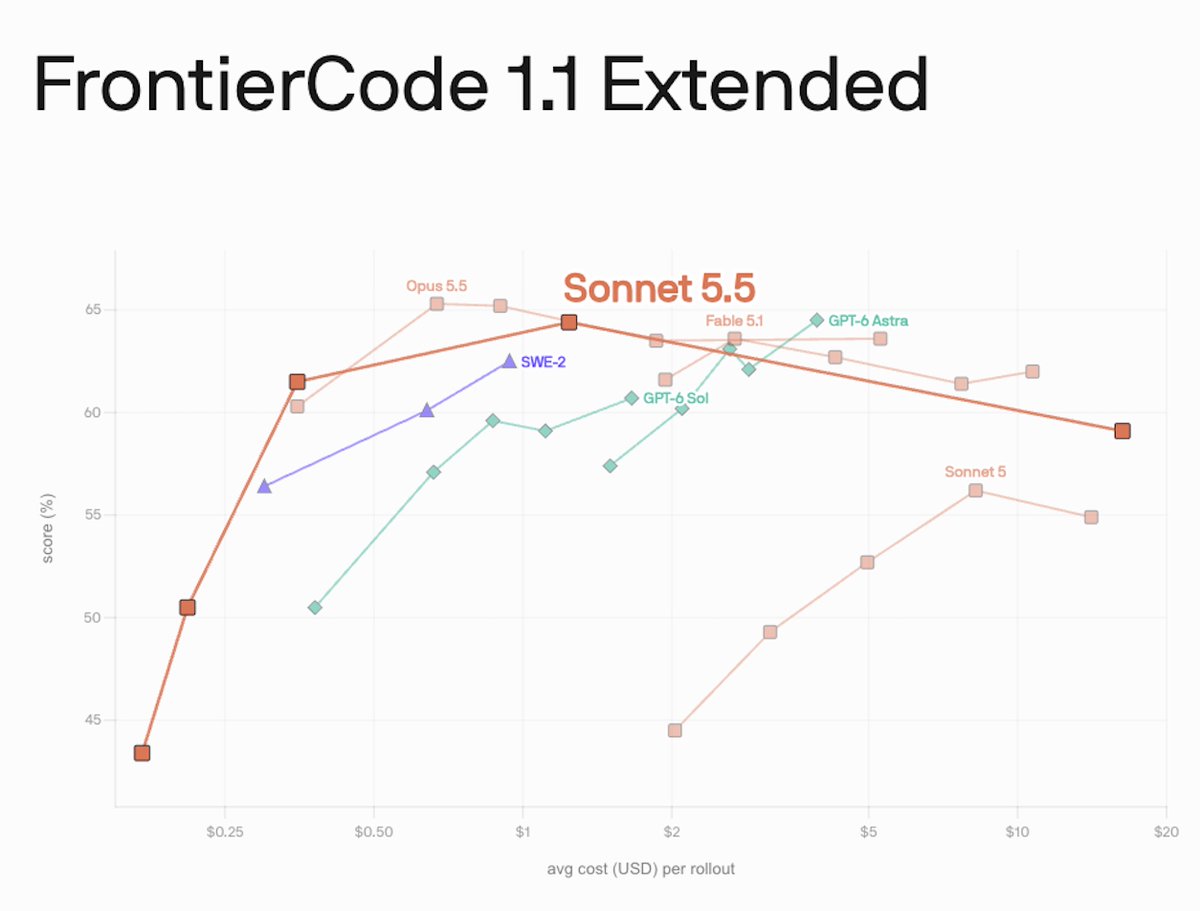
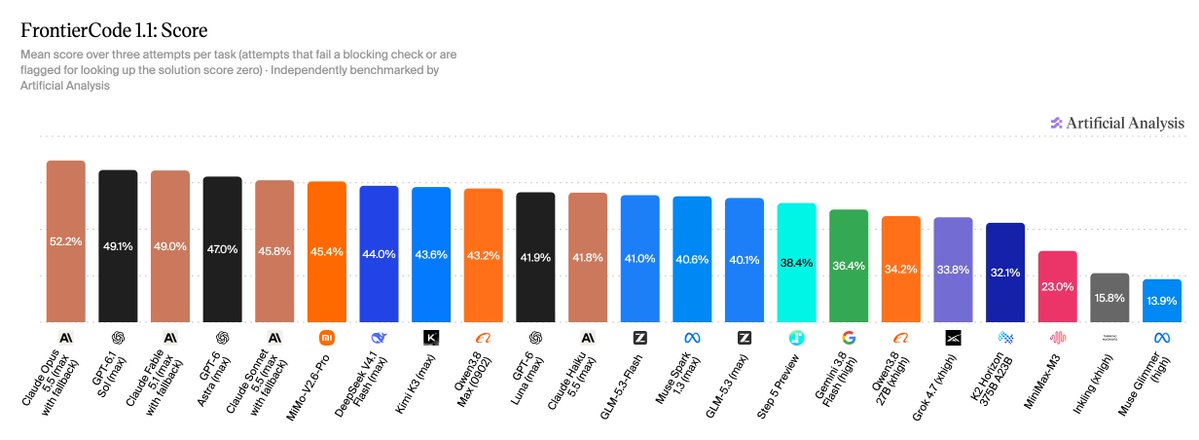
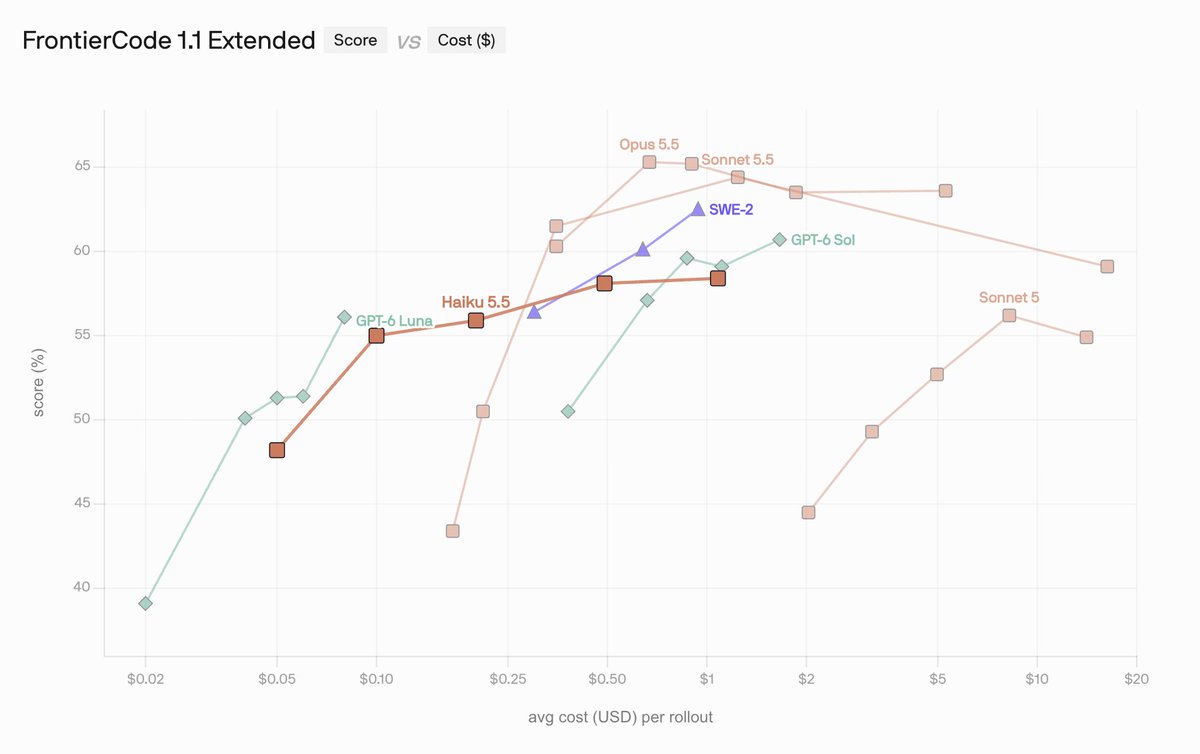
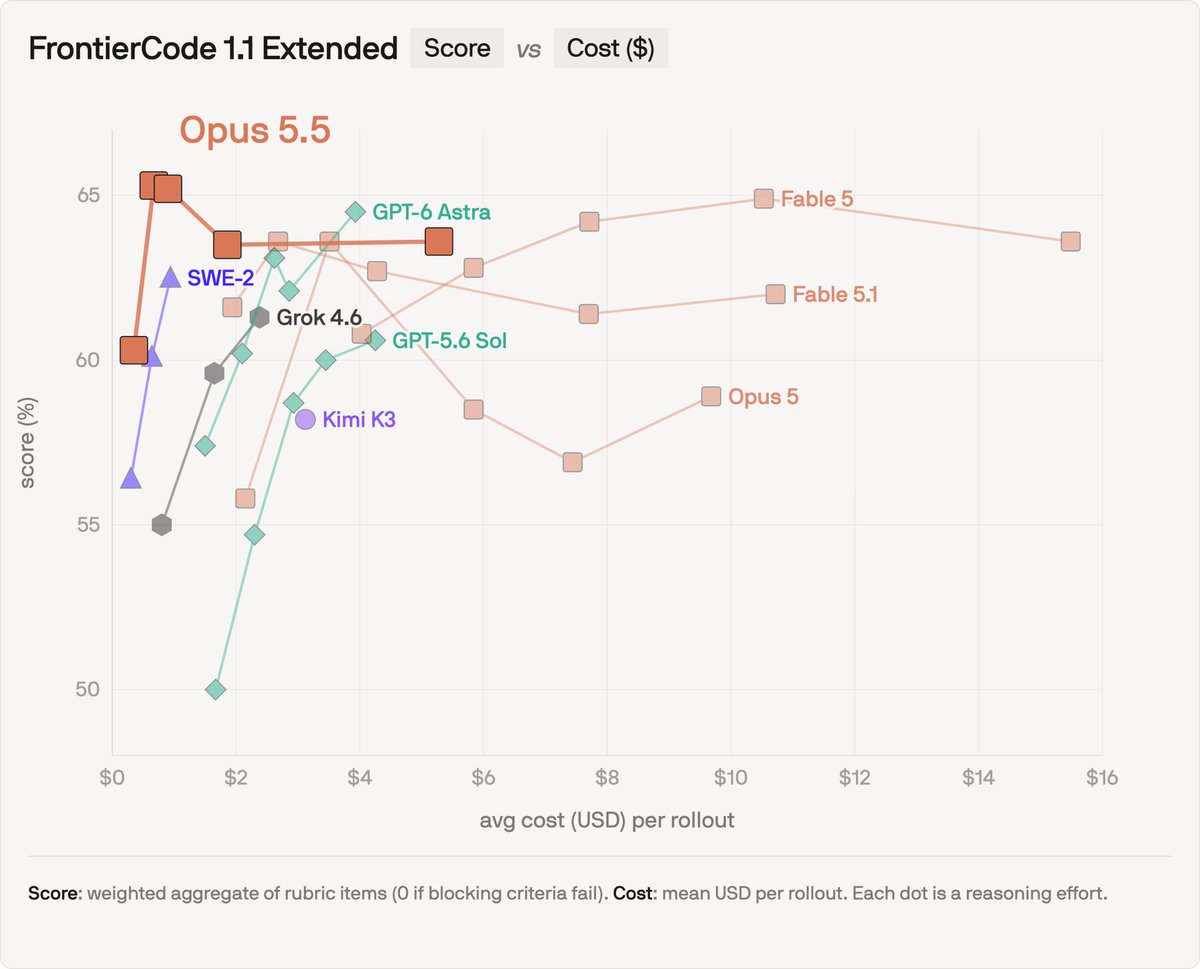
Claude Sonnet 5.5 is now available in Devin Desktop and Devin CLI. On FrontierCode 1.1 Main, it scores 64.4%, a significant improvement from Sonnet 5 (56.2%), surpassing Fable 5.1 at extra high reasoning effort.
Context
Cognition reports that Claude Sonnet 5.5 scores 64.4% on FrontierCode 1.1 Main, 8.2 points above the 56.2% it gives Sonnet 5. The post came as Cognition made the new Anthropic model available in Devin Desktop and Devin CLI, and it adds that Sonnet 5.5 surpasses Fable 5.1 run at extra high reasoning effort, a setting that lets a model spend more computation working through a problem before it answers.
FrontierCode is Cognition's own . When Artificial Analysis added it to its site in October, it described version 1.1 as testing whether AI models make code changes that maintainers of real open-source repositories would merge. Fable 5.1 is another Claude model, introduced at the start of September, so Cognition's claim is that the newer Sonnet beats a sibling model on this test even when that model is given a high reasoning setting.
The post gives only these headline numbers and an attached chart that was not available for this explanation. It does not describe the method, the number of tasks or the cost of each run. The result is Cognition's measurement on its own benchmark, so it supports a narrow conclusion: on the Main set of FrontierCode 1.1, as Cognition runs it, Sonnet 5.5 did clearly better than Sonnet 5. It is not an independent ranking of coding models.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
Checking sign-in…
Loading comments…